Monday, January 28, 2019

Introduction to SQL Server Security — Part 2

The series so far:

  1. Introduction to SQL Server Security — Part 1
  2. Introduction to SQL Server Security — Part 2

One of the most important tasks that DBAs must perform when managing a SQL Server database is to ensure that authorized users can access the data they need and carry out the necessary operations on that data. To this end, SQL Server includes a number of components for authenticating users and authorizing them to access objects at the server, database, and schema levels, while preventing unauthorized users from doing anything they should not.

In the first article in this series, I introduced you to authentication and authorization as part of a larger discussion about SQL Server security. In this article, I dig deeper into these topics and provide some examples that demonstrate how to implement basic access controls on a SQL Server 2017 instance.

Note, however, that authentication and authorization are huge topics. For this reason, you might also want to refer to a couple of other Simple Talk articles, one that I wrote and the other by Phil Factor:

You should also refer to Microsoft documentation as necessary to ensure you fully understand what types of access you’re granting to your users and what tasks they can and cannot perform. A good place to start is with Security Center for SQL Server Database Engine and Azure SQL Database, which covers a number of important aspects of SQL Server security, including access control.

Getting Started with Authentication and Authorization

SQL Server provides three types of components for controlling which users can log onto SQL Server, what data they can access, and which operations they can carry out:

  • Principals: Individuals, groups, or processes granted access to the SQL Server instance, either at the server level or database level. Server-level principals include logins and server roles. Database-level principals include users and database roles.
  • Securables: Objects that make up the server and database environment. The objects can be broken into three hierarchical levels:
    • Server-level securables include such objects as databases and availability groups.
    • Database-level securables include such objects as schemas and full-text catalogs.
    • Schema-level securables include such objects as tables, views, functions, and stored procedures.
  • Permissions: The types of access permitted to principals on specific securables. You can grant or deny permissions to securables at the server, database, or schema level. The permissions you grant at a higher level of the hierarchy also apply to children and grandchildren objects, unless you specifically deny those permissions at the lower level.

Together, these three component types provide a structure for authenticating and authorizing SQL Server users. You must grant each principal the appropriate permissions it needs on specific securables to enable users to access SQL Server resources. For example, if the sqluser01 database user needs to be able to query data in the Sales schema, you can grant the SELECT permission to that user on the schema. The user would then be able to query each table and view within the schema.

In most cases, you’ll take some or all of the following steps to provide users with the access they need to SQL Server resources:

  1. At the server level, create a login for each user that should be able to log into SQL Server. You can create Windows authentication logins that are associated with Windows user or group accounts, or you can create SQL Server authentication logins that are specific to that instance of SQL Server.
  2. Create user-defined server roles if the fixed server roles do not meet your configuration requirements.
  3. Assign logins to the appropriate server roles (either fixed or user-defined).
  4. For each applicable server-level securable, grant or deny permissions to the logins and server roles.
  5. At the database level, create a database user for each login. A database user can be associated with only one server login. You can also create database users that are not associated with logins, in which case, you can skip the first four steps.
  6. Create user-defined database roles if the fixed database roles do not meet your configuration requirements.
  7. Assign users to the appropriate database roles (either fixed or user-defined).
  8. For each applicable database-level or schema-level securable, grant or deny permissions to the database users and roles.

You will not necessarily have to carry out all these steps, depending on your particular circumstances. For example, you might not need to create any user-defined roles at the server or database levels. In addition, you do not need to follow these steps in the exact order. You might grant permissions to server logins or database users when you create them, or you might create server roles and database roles before creating the logins or users. The steps listed here are meant only as a guideline.

The examples in the following sections walk you through the process of creating principals and assigning permissions to them for specific securables. All the examples use T-SQL to carry out these operations. You can also use features built into the SQL Server Management Studio (SSMS) interface to perform many of these tasks, but knowing the T-SQL can make it easier to repeat steps and add them to your scripts.

Creating Server Logins

SQL Server supports four types of logins: Windows, SQL Server, certificate-mapped, and asymmetric key-mapped. For this article, I focus on Windows and SQL Server logins, using the CREATE LOGIN statement to define several logins. Because logins exist at the server level, you must create them within the context of the master database.

A Windows login is associated with a local Windows account or domain account. When you create the login, you must specify the Windows account, preceded by the computer name or domain name and a backslash. For example, the following CREATE LOGIN statement defines a login based on the winuser01 local user account on the win10b computer:

USE master;
GO
CREATE LOGIN [win10b\winuser01] FROM WINDOWS 
WITH DEFAULT_DATABASE = master, DEFAULT_LANGUAGE = us_english;
GO

The statement must include the FROM WINDOWS clause to indicate that this is a Windows login. In this case, the statement also includes an optional WITH clause, which specifies a default database and language.

If you’re creating a login based on a domain account, replace the computer name with the domain name, following the same format:

[<domain_name>\<windows_account>]

You should also use this format if creating a login based on a Windows group. For example, the following CREATE LOGIN statement creates a login based on wingroup01, a group defined on the local Windows computer:

CREATE LOGIN [win10b\wingroup01] FROM WINDOWS 
WITH DEFAULT_DATABASE = master, DEFAULT_LANGUAGE = us_english;
GO

By creating a login based on a group, you can provide the same level of access to any user within that group, while letting Windows and SQL Server handle authenticating and authorizing the individual users.

You can also use the CREATE LOGIN statement to define a SQL Server login (one that is not associated with a Windows account), in which case, do not include the FROM WINDOWS clause. However, you must include a WITH clause that specifies a password, as shown in the following example:

CREATE LOGIN sqluser01 
WITH PASSWORD = 'tempPW@56789' 
  MUST_CHANGE, CHECK_EXPIRATION = ON,
  DEFAULT_DATABASE = master, DEFAULT_LANGUAGE = us_english;
GO

For the password, you can provide a string value, as I’ve done here, or a hashed value, along with the HASH keyword. You can also define additional options. In this case, the WITH clause includes the MUST_CHANGE option to force the user to change the password when first logging into SQL Server. The clause also sets the CHECK_EXPIRATION option to ON, which means that the password expiration policy will be enforced on this login.

Once you’ve created a login, you can use the GRANT statement to grant permissions to that login. For example, the following statement grants the IMPERSONATE ANY LOGIN permission to the winuser01 and sqluser01 users, allowing them to run T-SQL statements within the context of another user:

GRANT IMPERSONATE ANY LOGIN TO [win10b\winuser01], sqluser01;
GO

After you’ve granted permissions to a principal, you can use the sys.server_principals and sys.server_permissions catalog views to verify that the permissions have been configured correctly:

SELECT pr.principal_id, pr.name, pe.state_desc, pe.permission_name  
FROM sys.server_principals pr INNER JOIN sys.server_permissions pe 
  ON pr.principal_id = pe.grantee_principal_id
WHERE pr.principal_id = SUSER_ID('win10b\winuser01')
  OR pr.principal_id = SUSER_ID('sqluser01');

The SELECT statement joins the two catalog views and filters the results by the two logins, using the SUSER_ID built-in function to retrieve each login’s principal identification number. Figure 1 shows the data returned by the SELECT statement.
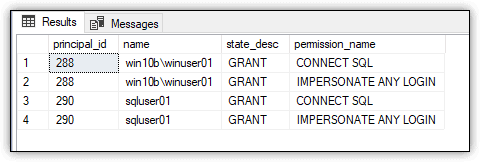
Figure 1. Viewing permissions assigned to SQL Server principals

The results show that both users have been assigned the IMPERSONATE ANY LOGIN permission, along with the CONNECT SQL permission, which is assigned by default to all logins to enable them to connect to the SQL Server instance.

Creating Server Roles

A server role makes it possible for you to group logins together in order to more easily manage server-level permissions. SQL Server supports fixed server roles and user-defined server roles. You can assign logins to a fixed server role, but you cannot change its permissions. You can do both with a user-defined server role.

Creating and configuring a user-defined server role is very straightforward. You create the role, grant permissions to the role, and then add logins—or you can add the logins and then grant the permissions. The following T-SQL takes the first approach:

CREATE SERVER ROLE devops;
GRANT ALTER ANY DATABASE TO devops; 
ALTER SERVER ROLE devops ADD MEMBER [win10b\winuser01];
GO

The CREATE SERVER ROLE statement defines a server role named devops. If you want to specify an owner for the server role, you can include an AUTHORIZATION clause. Without the clause, the login that executes that statement becomes the owner.

The GRANT statement grants the ALTER ANY DATABASE permission to the devops role, which means that any members of that role will acquire that permission. The ALTER SERVER ROLE statement adds the winuser01 login to the devops role.

That’s all there is to it. You can then use the sys.server_principals and sys.server_permissions catalog views to verify that the permissions on the devops role have been set up correctly:

SELECT pe.state_desc, pe.permission_name  
FROM sys.server_principals pr INNER JOIN sys.server_permissions pe 
  ON pr.principal_id = pe.grantee_principal_id
WHERE pr.principal_id = SUSER_ID('devops');

The statement’s results should confirm that that devops role has been granted the ALTER ANY DATABASE permission.

You can also confirm that the winuser01 login has been added to the devops role by using the sys.server_role_members and sys.server_principals catalog views:

SELECT rm.member_principal_id, pr.name  
FROM sys.server_role_members rm INNER JOIN sys.server_principals pr 
  ON rm.member_principal_id = pr.principal_id
WHERE rm.role_principal_id = SUSER_ID('devops');

The results from the SELECT statement should indicate that the winuser01 login has been added to the devops role and that no other logins are included. Of course, in a real-world scenario, you would be adding multiple logins to a user-defined server role. Otherwise, there would be little reason to create it.

Creating Database Users

After you’ve set up your server-level logins, you can create database users that map back to those logins, whether they’re Windows or SQL Server logins. You can also create database users that do not map to logins. These types of logins are generally used for contained databases, impersonation, or development and testing.

SQL Server provides the CREATE USER statement for creating database users. You must run this statement within the context of the database in which the user is being defined. For example, the following T-SQL creates a user in the WideWorldImporters database and then assigns the ALTER permission to the user on the Sales schema:

USE WideWorldImporters;
GO
CREATE USER [win10b\winuser01];
GRANT ALTER ON SCHEMA::Sales TO [win10b\winuser01]; 
GO

The winuser01 user is based on the win10b\winuser01 login. When you create a database user that has the same name as a login, you do not need to specify the login. However, if you want to create a user with a different name, you must include the FOR LOGIN or FROM LOGIN clause, as in the following example:

CREATE USER winuser03 FOR LOGIN [win10b\winuser01];
GRANT ALTER ON SCHEMA::Sales TO winuser03; 
GO

You can create only one user in a database per login. If you want to try out both these statements, you’ll need to drop the first user before creating the second. The examples that follow are based on the win10b\winuser01 user.

The two preceding examples also include a GRANT statement that assigns the ALTER permission to the user on the Sales schema. As a result, the user will be able to alter any object within that schema. Notice that the statement includes the SCHEMA::Sales element. When you grant a permission on a specific object, you must specify the type of object and its name, separated by the scope qualifier (double colons).

In some GRANT statements, the securable is implied, so it does not need to be specified. For instance, in an earlier example, you granted the ALTER ANY DATABASE permission to the devops role. Because you granted this permission at the server level for all database objects at that level, you did not need to specify a securable.

After you’ve granted permissions to a database user, you can use the sys.database_principals and sys.database_permissions catalog views to verify that the permissions have been configured correctly:

SELECT pe.state_desc, pe.permission_name  
FROM sys.database_principals pr INNER JOIN sys.database_permissions pe 
  ON pr.principal_id = pe.grantee_principal_id
WHERE pr.principal_id = USER_ID('win10b\winuser01');

Notice that the WHERE clause uses the USER_ID function and not the SUSER_ID function, which was used in the earlier examples. The USER_ID function returns the user principal ID, rather than the login principal ID. Figure 2 shows the results returned by the SELECT statement. In addition to the ALTER permission, the user is automatically granted the CONNECT permission:
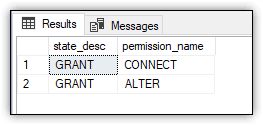
Figure 2. Viewing permissions assigned to winuser01

Creating a database user that’s associated with a SQL Server login is just as simple as creating a user based on a Windows login, especially when you use the same name, as in the following example:

CREATE USER sqluser01;
GO

The CREATE USER statement creates the sqluser01 user, but this time, the example grants no permissions. As a result, the user receives only the CONNECT permission, which you can verify by running the following SELECT statement:

SELECT pe.state_desc, pe.permission_name  
FROM sys.database_principals pr INNER JOIN sys.database_permissions pe 
  ON pr.principal_id = pe.grantee_principal_id
WHERE pr.principal_id = USER_ID('sqluser01');

You can also create a user based on a Windows account even if you don’t create a login. For example, the following statement creates the winuser02 user that’s associated with the win10b\winuser02 account on the local computer:

CREATE USER [win10b\winuser02];
GO

Creating a user in this way makes it possible to support contained databases, which do not use server logins. Once again, you can verify that the user has been granted only the CONNECT permission by running the following SELECT statement:

SELECT pe.state_desc, pe.permission_name  
FROM sys.database_principals pr INNER JOIN sys.database_permissions pe 
  ON pr.principal_id = pe.grantee_principal_id
WHERE pr.principal_id = USER_ID('win10b\winuser02');

SQL Server also lets you create a user that is not associated with either a login or Windows account. To do so, you must include the WITHOUT LOGIN clause, as shown in the following example.

CREATE USER sqluser02 WITHOUT LOGIN;
GO

Creating a user without a login can be useful for development and testing. More importantly, it can be used with SQL Server’s impersonation capabilities. Users can authenticate to SQL Server under their own credentials and then impersonate the user account that’s not associated with a login. In this way, the authentication process can be monitored, but specific types of permissions can be granted to the unassociated user.

Creating Database Roles

A database role is a group of users that share a common set of database-level permissions. As with server roles, SQL Server supports both fixed and user-defined database roles. To set up a user-defined database role, you must create the role, grant permissions to the role, and add members to the role (or add members and then grant permissions). The following example demonstrates how to set up the dbdev role:

CREATE ROLE dbdev;
GRANT SELECT ON DATABASE::WideWorldImporters TO dbdev;
ALTER ROLE dbdev ADD MEMBER [win10b\winuser01];
ALTER ROLE dbdev ADD MEMBER sqluser01;
GO

The CREATE ROLE statement creates the database role. The GRANT statement grants the role the SELECT permission on the database. The two ALTER ROLE statements add the winuser01 and sqluser01 users to the role.

You can verify that the SELECT permission has been granted to the role by running the following SELECT statement:

SELECT pe.state_desc, pe.permission_name  
FROM sys.database_principals pr INNER JOIN sys.database_permissions pe 
  ON pr.principal_id = pe.grantee_principal_id
WHERE pr.principal_id = USER_ID('dbdev');

In some cases, you might want to see the effective (cumulative) permissions granted to a principal on a securable. A simple way to do this is to use the fn_my_permissions table-valued function, specifying the securable and its type.

The trick to using this function is to call it within the execution context of the specific user. To do so, you must first issue an EXECUTE AS statement and then, after running your SELECT statement, issue a REVERT statement, as shown in the following example:

EXECUTE AS USER = 'win10b\winuser01'; 
SELECT * FROM fn_my_permissions ('Sales.BuyingGroups', 'OBJECT'); 
REVERT;  
GO

The fn_my_permissions function takes two arguments: the target securable and the type of securable. In this case, the target securable is the Sales.BuyingGroups table, and the securable type is OBJECT, which includes schema-level securables such as tables, views, and stored procedures. Figure 3 shows the results returned by the SELECT statement.
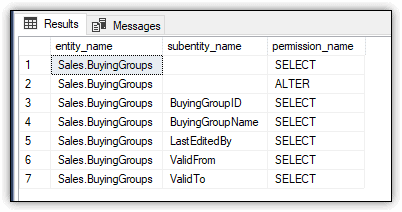
Figure 3. Viewing effective permissions for winuser01

As you’ll recall from the previous section, the ALTER permission was granted to winuser01 after the user was created, and the SELECT permission was granted to the role after it was created. Notice that each of the table’s columns is also assigned the SELECT permission.

Now run the same SELECT statement within the execution context of the sqluser01 user:

EXECUTE AS USER = 'sqluser01'; 
SELECT * FROM fn_my_permissions ('Sales.BuyingGroups', 'OBJECT'); 
REVERT;  
GO

The SELECT statement returns the results shown in Figure 4, which are specific to the user specified in the EXECUTE AS statement.
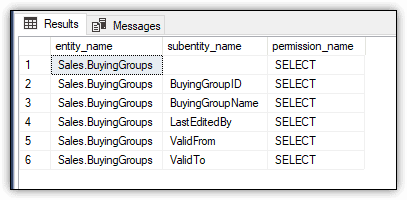
Figure 4. Viewing effective permissions for sqluser01

This time, the ALTER permission is not included in the results because that permission was never granted to that user.

Digging into Permissions

Several of the examples so far have used the GRANT statement to assign permissions to principals, but SQL Server actually provides three T-SQL statements for working with permissions:

  • Use a GRANT statement to enable principals to access specific securables.
  • Use a DENY statement to prevent principals from accessing specific securables. A DENY statement overrides any granted permissions.
  • Use a REVOKE statement to remove permissions that have been granted to principals on specific securables.

Permissions are cumulative in that the user receives all permissions granted specifically to the database user as well as to its associated login. Also, if the user has been assigned to a database role or if the login has been assigned to a server role, the user receives the role permissions as well.

Permissions are also transitive, based on the hierarchical nature of the server, database, and schema securables. For example, if you grant the UPDATE permission to a user for a specific database, the user will also be granted the UPDATE permission on all schemas and schema objects such as tables and views.

In addition, some permissions are covering, that is, they include multiple permissions under a single name. A good example of this is the CONTROL permission, which includes such permissions as INSERT, UPDATE, DELETE, EXECUTE, and several others. For instance, the following GRANT statement grants the CONTROL permission to sqluser01 for the Sales schema:

GRANT CONTROL ON SCHEMA::Sales TO sqluser01;

After granting the CONTROL permission, you can again use the fn_my_permissions function to view the effective permissions for that user on the Sales schema:

EXECUTE AS USER = 'sqluser01'; 
SELECT * FROM fn_my_permissions ('Sales', 'SCHEMA'); 
REVERT;  
GO

Figure 5 shows the results returned by the SELECT statement.
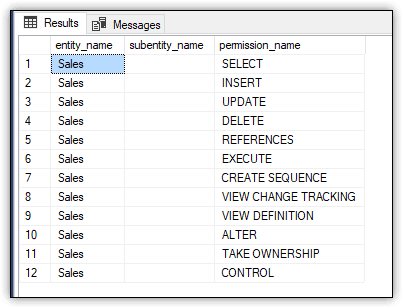
Figure 5. Viewing effective permissions on the Sales schema

The SELECT permission was granted to the user at the database level through the dbdev role and at the schema level as part of the CONTROL permission, as are the rest of the permissions shown in the results. You can also view the effective permissions on an object within the Sales schema by using the following SELECT statement:

EXECUTE AS USER = 'sqluser01'; 
SELECT * FROM fn_my_permissions ('Sales.BuyingGroups', 'OBJECT'); 
REVERT;  
GO

In this case, the fn_my_permissions function specifies the BuyingGroups table as the target object. As a result, the SELECT statement now returns 25 rows of permissions on that table for sqluser01. Figure 6 shows the first 13 rows from that result set.
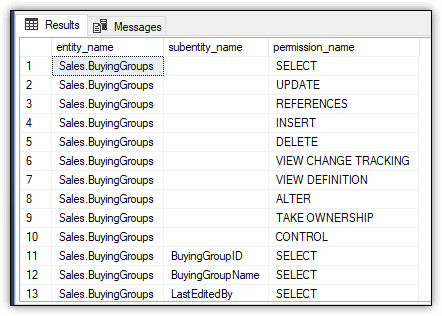
Figure 6. Viewing effective permissions on the BuyingGroups table

As you can see, covering permissions help simplify the process of granting access to the database objects. Without them, your GRANT statements would look more like the following:

GRANT SELECT, INSERT, UPDATE, DELETE, REFERENCES, 
EXECUTE, CREATE SEQUENCE, VIEW CHANGE TRACKING, 
VIEW DEFINITION, ALTER, TAKE OWNERSHIP, CONTROL
ON SCHEMA::Sales TO sqluser01;

You can also deny permissions on securables. This can be useful when you want to grant permissions at a higher level in the object hierarchy but want to prevent those permissions from extending to a few of the child objects. For example, you can deny the CONTROL permission to sqluser01 on an individual table within the Sales schema, as shown in the following example:

DENY CONTROL ON OBJECT::Sales.BuyingGroups TO sqluser01;

When you deny the CONTROL permission, you deny all permissions that are part of CONTROL, including the SELECT permission. You can verify this by running the following SELECT statement:

EXECUTE AS USER = 'sqluser01'; 
SELECT * FROM fn_my_permissions ('Sales.BuyingGroups', 'OBJECT'); 
REVERT;  
GO

The SELECT statement returns an empty result set, indicating that sqluser01 no longer has any type of permissions on the BuyingGroups table.

The DENY permission takes precedence over all granted permissions, no matter where in the object hierarchy permissions are granted or denied. However, denying permissions on one object does not impact other objects unless they’re child objects. For example, the following SELECT statement shows that all permissions are still intact on the CustomerCategories table in the Sales schema:

EXECUTE AS USER = 'sqluser01'; 
SELECT * FROM fn_my_permissions ('Sales.CustomerCategories', 'OBJECT'); 
REVERT;  
GO

However, if you deny permissions on an object that contains child objects, the permissions are also denied on the child objects. For instance, the following DENY statement denies sqluser01 the ALTER permission on the Sales schema:

DENY ALTER ON SCHEMA::Sales TO sqluser01;

If you now run the following SELECT statement, you’ll find that the ALTER permission is no longer granted at the Sales schema:

EXECUTE AS USER = 'sqluser01'; 
SELECT * FROM fn_my_permissions ('Sales', 'SCHEMA'); 
REVERT;  
GO

You’ll get the same results if you check the effective permissions on one of the objects in the Sales schema, such as the CustomerCategories table:

EXECUTE AS USER = 'sqluser01'; 
SELECT * FROM fn_my_permissions ('Sales.CustomerCategories', 'OBJECT'); 
REVERT;  
GO

Once again, the ALTER permission is no longer listed.

In some cases, you will need to roll back the permissions that have been granted on an executable, in which case, you can use the REVOKE statement. For example, the following REVOKE statement removes the CONTROL permission from the Sales schema for sqluser01:

REVOKE CONTROL ON SCHEMA::Sales TO sqluser01;

After revoking the CONTROL permission, you can once again use the fn_my_permissions function to view the effective permissions for that user on the Sales schema:

EXECUTE AS USER = 'sqluser01'; 
SELECT * FROM fn_my_permissions ('Sales', 'SCHEMA'); 
REVERT;  
GO

This time, only the SELECT permission is listed. That’s because this permission was granted separately at the database level as part of the dbdev role. You can also verify the effective permissions on the CustomerCategories table:

EXECUTE AS USER = 'sqluser01'; 
SELECT * FROM fn_my_permissions ('Sales.CustomerCategories', 'OBJECT'); 
REVERT;  
GO

Once again, the results indicate that only the SELECT permission has been granted on this table, as shown in Figure 7.
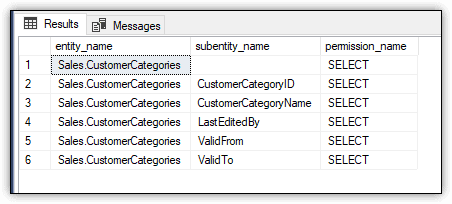
Figure 7. Viewing effective permissions on the CustomerCategories table

When working with permissions, be careful not to confuse the DENY statement with the REVOKE statement. You could end up unintended consequences when users receive permissions from multiple sources, as in the examples above. For example, if you had denied sqluser01 the CONTROL permission to the Sales schema, rather than revoke the permission, the user would no longer have SELECT permissions to the schema and its objects.

Controlling Access to SQL Server Data

Controlling access to SQL Server becomes an increasingly complex process as more users are added and the data structure itself becomes more complicated. Your goal should be to limit users to the least amount of privileges they need to do their jobs. Don’t grant the CONTROL permission on the database when they need only the SELECT permission on a couple of tables. At the same time, don’t make more work for yourself than necessary. If a user needs the SELECT permission on all tables in a schema, grant the permission at the schema level.

SQL Server provides the ability to grant users the access they need at the level they need it. The GRANT, DENY, and REVOKE statements—along with the wide assortments of permissions (230 in SQL Server 2016 and 237 in SQL Server 2017)—make it possible to implement controls at a very granular level, while still providing the flexibility necessary to accommodate access at a higher level in the object hierarchy. However, controlling access takes careful planning and implementation. This is not the time for shortcuts or casual one-offs. The more diligently you control data access, the better for everyone and the more precise the control you have over the data.

The post Introduction to SQL Server Security — Part 2 appeared first on Simple Talk.


from Simple Talk http://bit.ly/2HCdUYp
via

Tuesday, January 22, 2019

The BI Journey: The Analyst

AdventureWorks, the famous bicycle and accessories seller, has hired a new intern who joined the North American regional sales department. Ruthie, who is studying for a degree in IT, landed the internship to work for the Sales Manager Stephen as an analyst among other roles. Energetic and enthusiastic as she is, Ruthie is always on the lookout to provide value and help her boss do his job better. Recently over lunch, Stephen was telling Ruthie about how his friend’s finance company was looking at analytics to help drive business while wondering how it could probably help sales at AdventureWorks and help him make informed decisions.

Ideas

Ruthie was at once taken up by the idea and decided to do some research. She soon found out about the value of data, and how analytics could help gain insights into the business, which in turn could be used to take appropriate action or make informed decisions about the business’ direction. She called one of the database administrators at AdventureWorks and requested a set of sales data. After a bit of reluctance and mumbling about data security, the DBA, Dan, gave her a dataset that he had pulled out of the sales database, warning her to be aware of the security of the data. Ruthie immediately got to work.

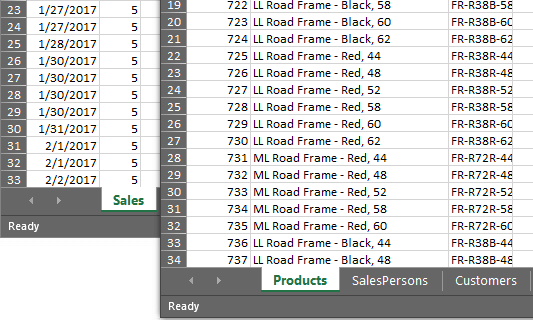
After some research, she decided to use Power BI since she could get started fast for free, and for the plethora of learning and support materials that were available on the Internet. After spending a couple of days familiarizing herself with the tool, she was ready to start. The data she received was an Excel spreadsheet with sales transactions and another Excel spreadsheet with a few entities which were part of the sales process.

Figure 1: Sheets from Excel Sources (sales.xlsx and entities.xlsx)

The first task that she knew she had to do was to create a dataset from these files to facilitate building her very first “dashboard,” essentially a Power BI report. The AdventureWorks’ first ever venture into Business Intelligence. Something that Ruthie nor Stephen had realized.

Business intelligence, in a lot of cases, starts within departments of an organization. However, not many know about it in the wider organization. These initiatives are usually performed by analysts with some support from IT using Excel. The success of these initiatives has mixed results. It is up to those driving these initiatives to keep evolving it by improving it to provide more value.

Data Access

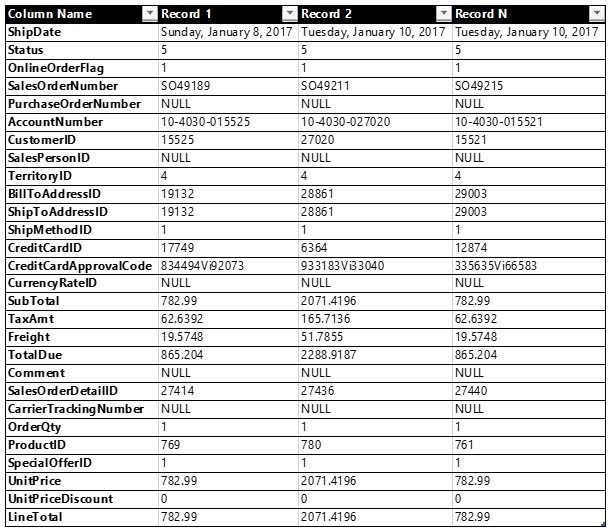
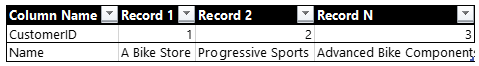
The sales transactions data was a crude combination of sales order header and detailed records, with IDs of each entity that were supplied in the entities file. The entities file had a sheet each for the following entities:

  • Products
  • SalesPersons
  • Customers

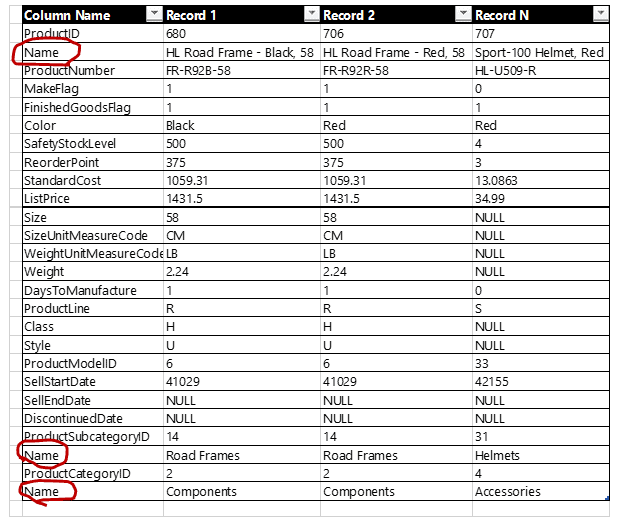
Going through the products sheet, Ruthie saw that it was a quick dump, just like the sales transactions without much formatting. There were three columns called “Name” with different values for the same record. She quickly figured that one was for the products’ actual names, the other was the products’ subcategories, and the third was the products’ categories. Ruthie gave a thankful smile that Dan had given a little thought to the data he had given her despite his grouchiness. She figured that she will have to analyze the rest of the sheets, as well as the sales transaction thoroughly so that she could profile data as being part of a hierarchy, how they related with data from other tables, if data was completely available, so on and so forth, before she could start to create her reports. Other than that, to Ruthie, it looked like the files had enough information for her to get started with.

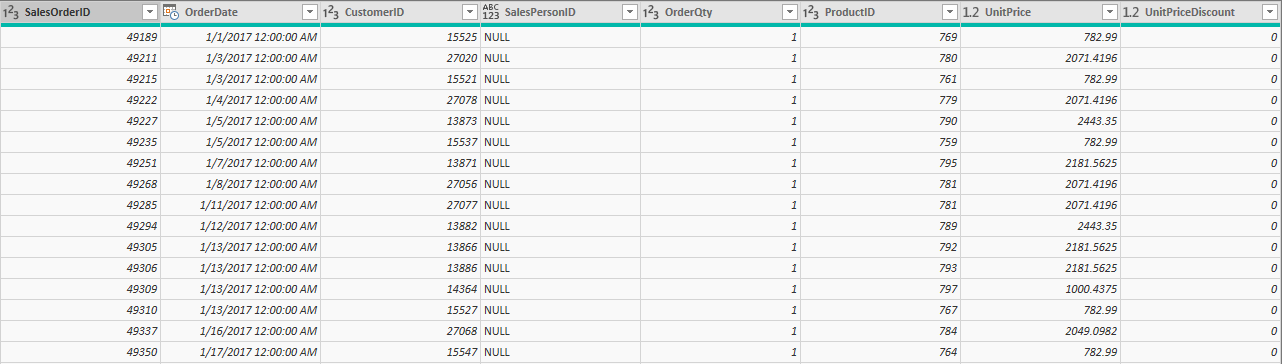
Figure 2: Sample data from Sales transaction file (Sales.xlsx)

Figure 3: Sample data from Entities file – Products sheet (Entities.xlsx)

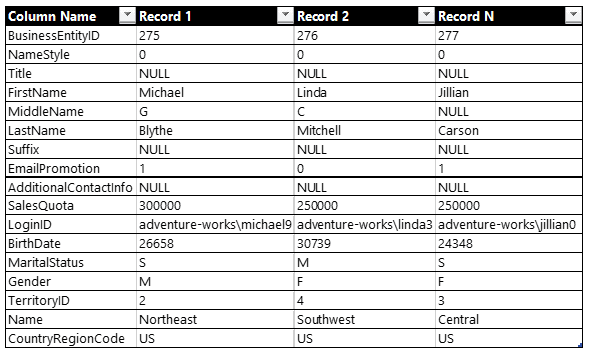
Figure 4: Entities file – SalesPersons sheet (Entities.xlsx)

Figure 5: Sample data from Entities file – Customers sheet (Entities.xlsx)

Getting access to data is one of the first steps in analytics. Despite being a simple step as assumed by most, especially in a corporate setting, obtaining data access is a tedious process. The major reason for this being the security of data. Would a DBA want to put the organization’s data in the hands of an intern? No. Therefore, until the value is shown through business intelligence and becomes a necessity, you usually would only be blessed with a small subset of it.

Data Preparation

What Ruthie had in mind, as would so many others who were new to building reports was of a flat dataset that combined data from all the sheets from both the files, without the columns that she thought were not necessary or not valuable enough to report on. She also decided to focus on just one business activity for her pilot for a quick win: sales orders analysis.

To get started on her dataset, Ruthie opened Power BI Desktop on her PC and connected to the sales.xlsx file. She used the Power Query Editor to build the query to structure her dataset.

She then performed the following general steps:

  1. Chose the fields that she felt were important for analysis
    (including the ID fields of the entities, since she knew she this was the only link to the entities in the Entities file)
  2. Formatted the fields with appropriate data types

Figure 7: Cleansed sales orders

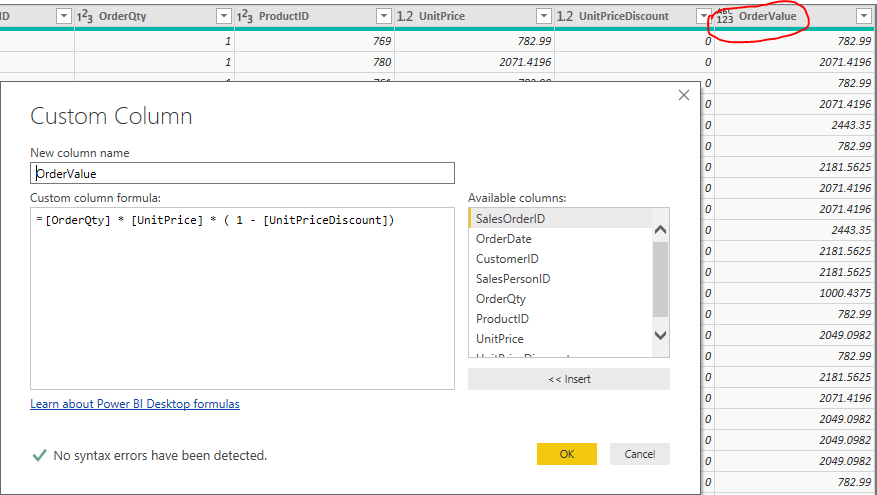
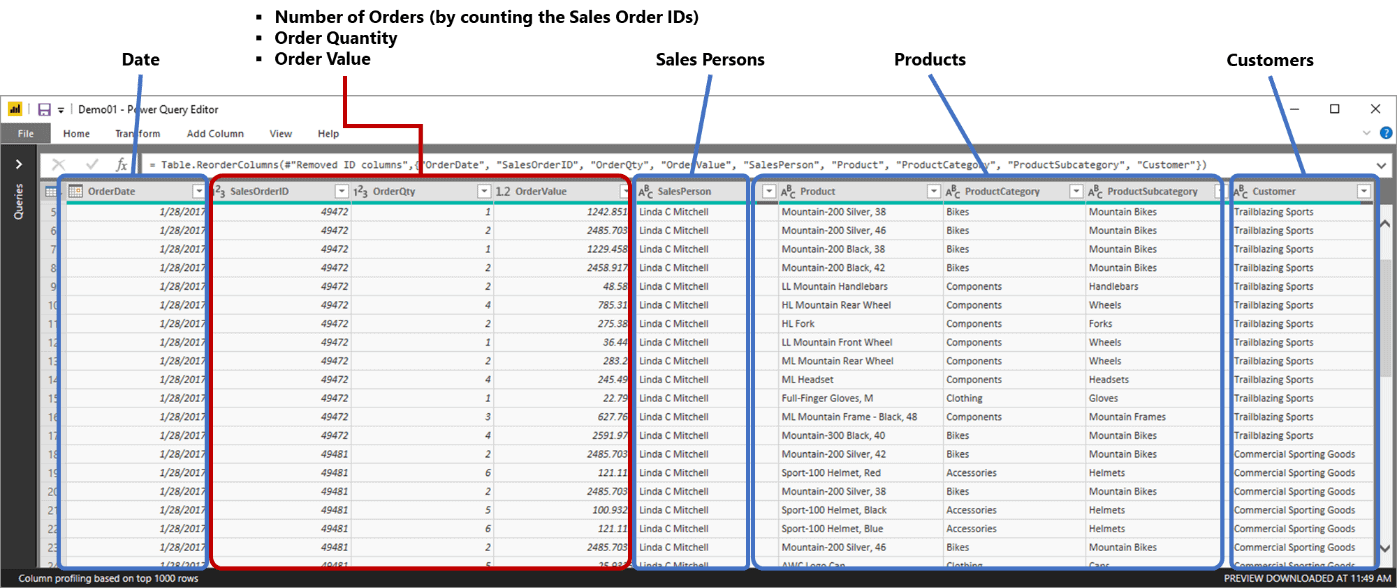
She could then analyze the number of sales orders (by counting SalesOrderID), the quantity of items ordered (by summing up OrderQty), and the value of items ordered (by calculating it using OrderQty, UnitPrice, and UnitPriceDiscount).

By adding a custom column to calculate the order value and getting rid of the UnitPrice and UnitPriceDiscount, she now had what she needed in terms of data to measure.

Figure 8:Cleansed sales orders with OrderValue as a calculated column

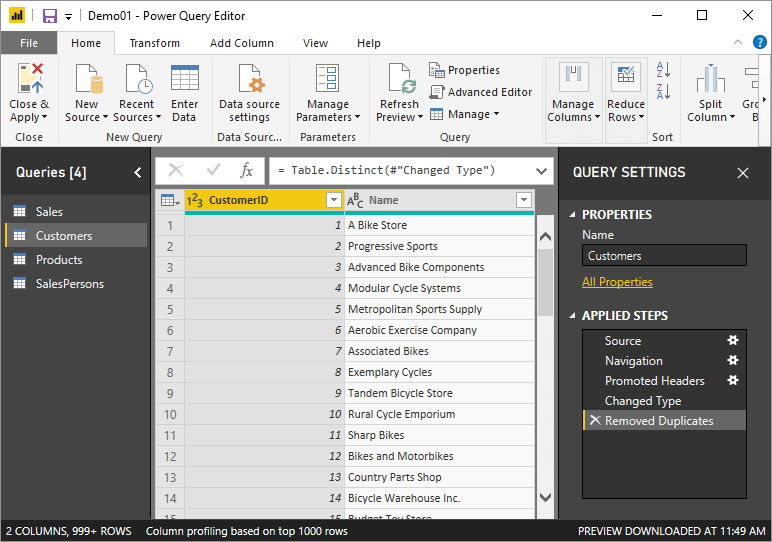
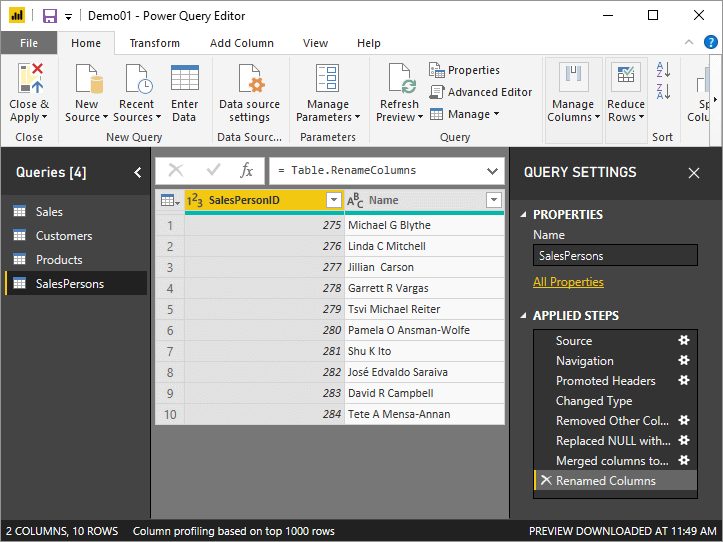
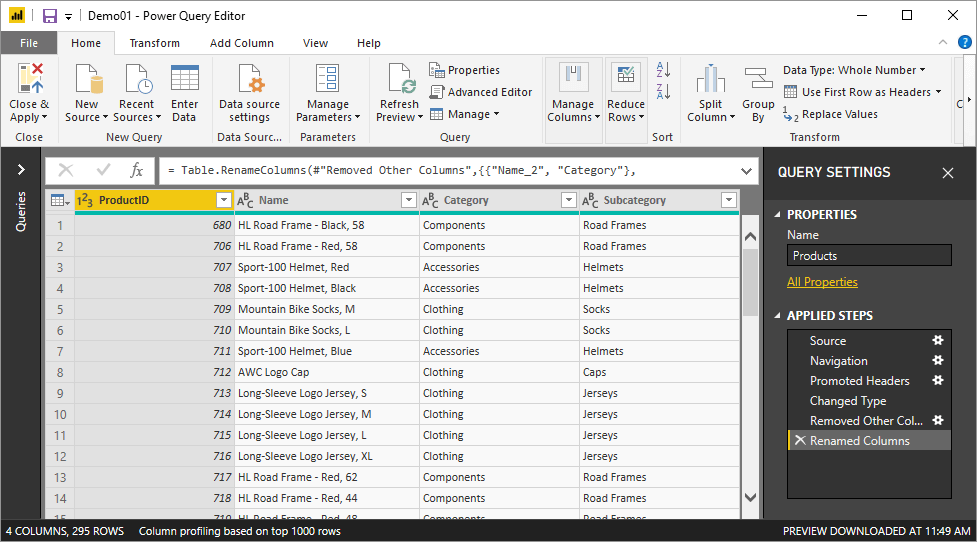
She felt this was good enough for now and should now bring in the entities. She once again pulled up the Power Query Editor and connected to the Entities.xlsx file and chose all the sheets. She then performed the same two steps she performed on the sales.xlsx files. She then performed several more steps on the queries to end up with simple results for each entity query. The following images show what the results of these queries look like.

Figure 9:Cleansed Customers

Figure 10: Cleansed SalesPersons

Figure 11: Cleansed Products

Each query contains the ID along with the name of the entity, except for Products, which contains two additional columns for subcategories and categories for the products. She then merged the entities with the entity queries with the sales query and removed the ID columns.

The final query looks like this, a big fat sales orders table with relevant entities columns:

Figure 12: Sales Orders

Prepping and modeling data are probably the most time-consuming tasks when building a business intelligence solution. Data needs to be profiled and checked for all sorts of errors, business logic validated, and then structured and formatted. It will probably also need to be combined with other tables to make up the perfect model for reporting.

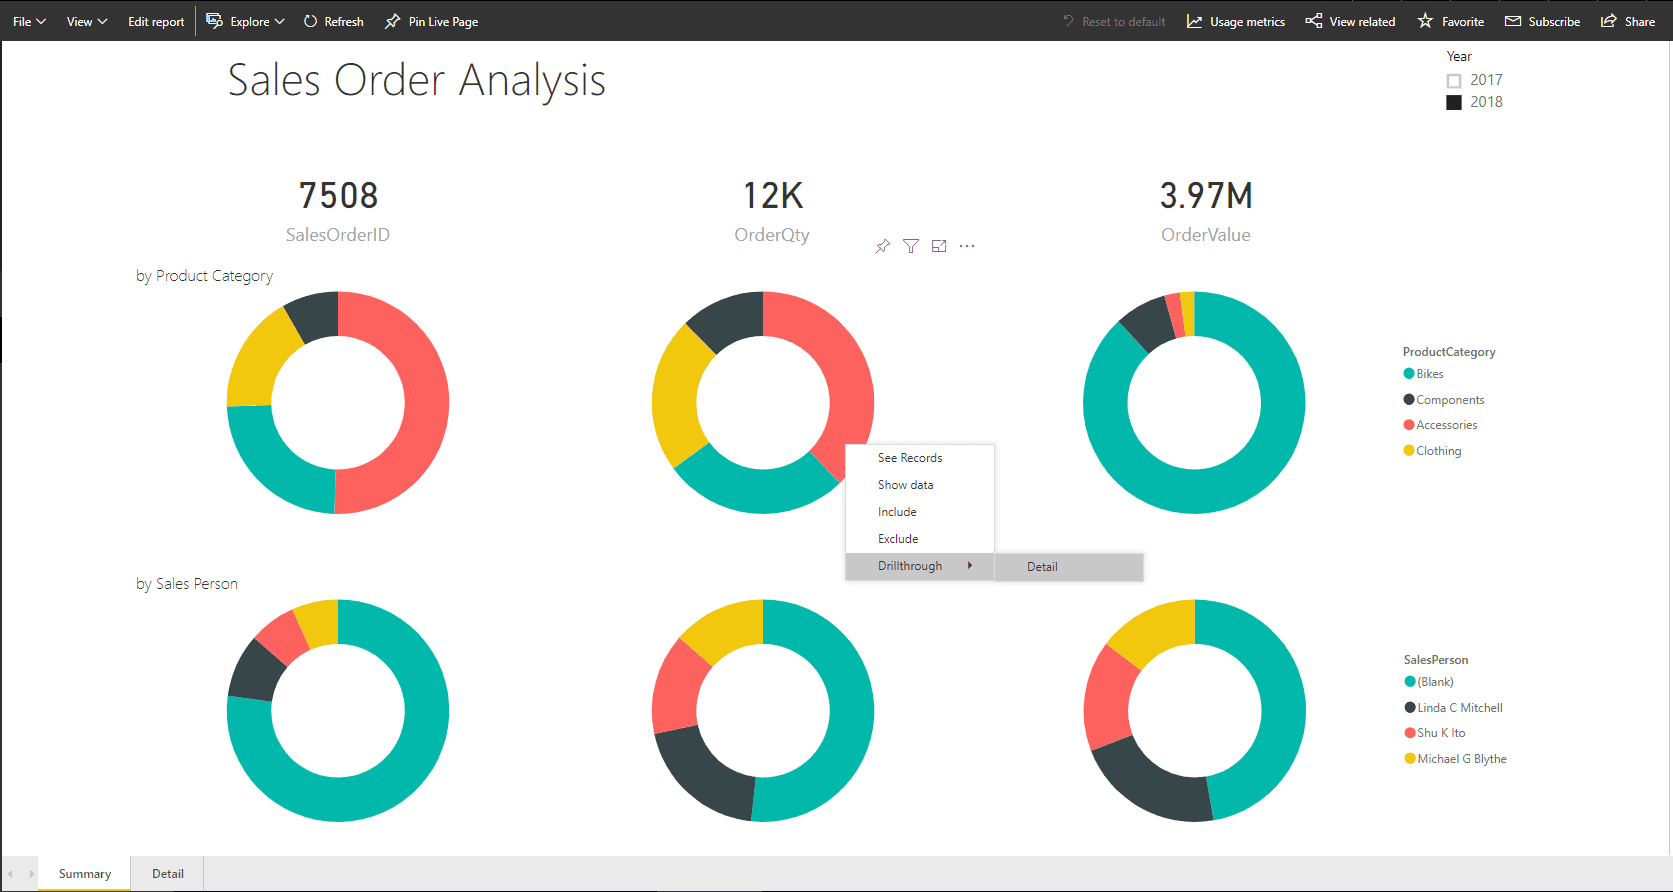
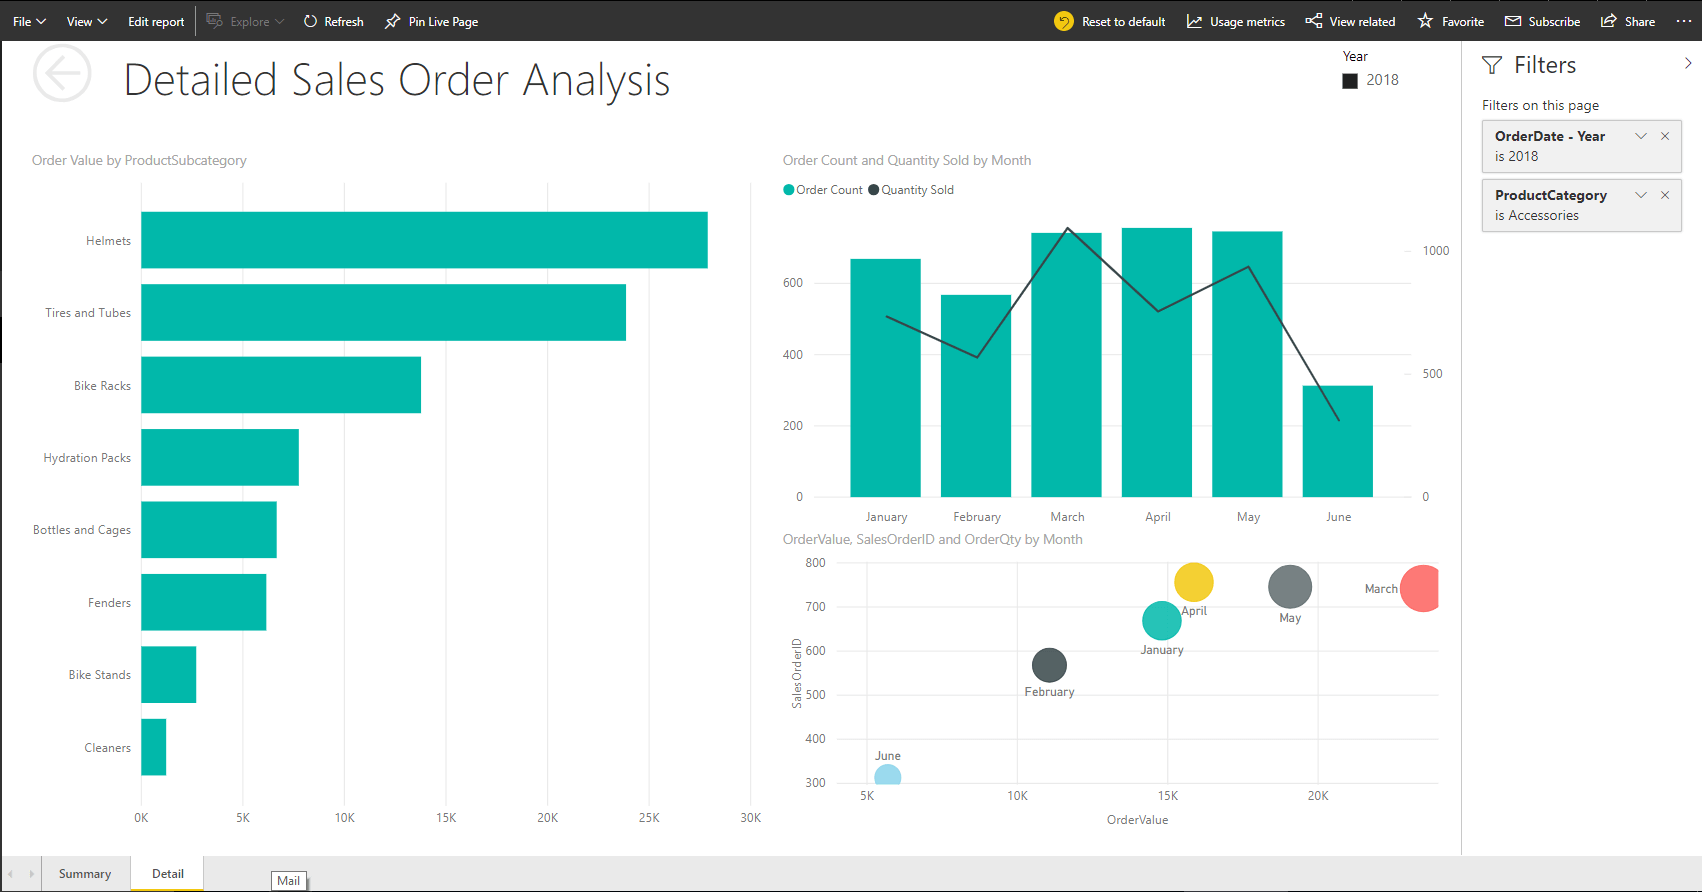
Now that the data structure is in place, Ruthie began building the report. She came up with a Sales Order Analysis dashboard which depicts the number of orders, the value of orders and the number of items sold. The dashboard has doughnut chart-based depictions of the three metrics by product category and by salespersons. The product category doughnuts allow for drill through to the Detail page, which shows a detailed analysis of the selected product category.

Figure 13: Sales Order Analysis “dashboard”

Figure 14: Detailed Sales Order Analysis page

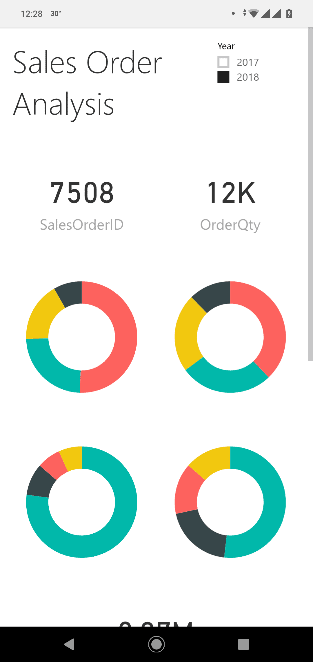
The report shows some basic metrics, with detailed analysis. It, however, does the job, and Ruthie believed this would be good enough to get Stephen interested and his head sparking off ideas. She also included a phone view of the report, so that Stephen could see what was going on with sales wherever he was.

Getting to this point with the report was not a straightforward activity. Data was first tried out on the canvas several times with different visuals to build a story.

A close up of a logo Description generated with high confidence

Figure 15: Sales Order Analysis on phone view

Ruthie did not waste time before showing this to Stephen. She quickly scheduled a meeting before Stephen left for the day, and ran him through the entire report, and even showed him how he could whip up his own report quite easily off the data structure she had built.

Stephen was quite impressed, especially since it just took a couple of days’ effort to get to this point. He was already shooting off ideas in his head as Ruthie guided him through the report. He could see so much potential in this type of solution where Ruthie had not relied on IT’s help too much, and the ability to build reports himself as long as he had the data set-up.

Tweaking for Value

He remembered that he used an Excel spreadsheet to store monthly sales targets that he set for all his sales representatives. He had never used it to measure the sales representatives’ performance effectively; he only used it to draw out the monthly targets based on the previous years’ sales patterns before sending it to the sales representatives – it was all just manual. Maybe he could ask Ruthie to include this spreadsheet into the mix and see if she could come up with more valuable insights.

He also found that switching between the two years to compare the previous year’s sales against this year’s sales was cumbersome, and he could not gauge how well sales were doing this year compared to the last. He quickly put down a list of improvements he would like to see in the next version of the report and handed it down to Ruthie.

Ruthie sighed. Stephen had not shown any enthusiasm nor excitement, except for the grunting sound he made when he kept clicking on the Year slicer switching back and forth between the previous and current year repeatedly. But then she held that piece of paper he had handed her. It was an impressive set of requirements: he wouldn’t want her to do all that if he didn’t find the solution appealing.

The list:

  • A better way of comparing the current year against the previous year
  • Use my targets spreadsheet. I want to measure each of the reps’ sales against it
  • Get proper naming, I can’t stand words stuck together, and I want to understand the dataset better if I was to do my own reporting
  • I want to see territory-wise as well. Will be nice on a map! I don’t know if you could do that
  • It would be nice to see which reps are more motivated. You know if they were single would they perform better, or if they were younger would they not be too enthusiastic, you know that kind of thing
  • And Ruthie, make sure numbers are properly formatted. I don’t know if one thing is in dollars or quantity!
  • Sales trends for the last five years would be a good thing too

Ruthie smiled to herself and packed her backpack. She planned to spend her weekend working on the report. It was way more interesting than the movie marathon she had planned with her BFFs. But just before she left for the day, she stopped by the DBA’s cubicle. Dan was usually in the office until late. She asked him if she could have more data and got into a conversation about analytics with him. Dan said he would see if he could send her the data before he left for the day but was in no mood to talk about analytics. He thought it was great that organizations were getting into it, but his passion was automating whatever he could with PowerShell. He gave her the contact information of a local analytics guy who worked a lot with the community; he said George would surely be happy to talk to her about it and that he would give George a heads up. The ever-enthusiastic Ruthie didn’t waste time contacting George who was more than ready to help and set up to meet for breakfast at the local coffee shop.

George was already at the coffee shop after his morning jog when Ruthie got there. He liked those who took up technology with a zing, especially if it was analytics. He took a look at the dataset Ruthie had built, shook his head slightly, then nodded at it. He looked at the list Stephen had given her and then proceeded to explain how to build a proper dataset. He called it a semantic model, something Ruthie thought sounded pretentious but decided to go along with since, after all, he was an expert.

An Expert’s Advice

George explained that the dataset that she had created was good enough for the current scenario but would soon become cumbersome when she needed to mash up data with more data sources. The best example he pointed was the targets spreadsheet that Stephen had given. The granularity of the current data set was product + customer + salesperson + date; the combination of each entity that makes up your transaction. The granularity of the targets spreadsheet, however, is product category + salesperson + month. Hence, these cannot be combined into one query (or table). He quickly tutored how to structure the data using a technique called dimensional modeling, which divides the data into facts and dimensions. Facts were those columns that she would measure or analyze, whereas dimensions were those columns that you used to analyze by. It was the entities that turned into dimensions, and you often you could group up dimensions within a single table itself such as the product dimension having the product name, product subcategory and product category. Or the date dimension which would contain the date, week, month, quarter and year columns. He drew up the semantic model for Ruthie’s case, and explained that once she’d got a correctly designed data model, then reporting on top of that would be very flexible; reports could be drawn up to answer different types of questions that get asked.

George also gave Ruthie a few more tidbits of best practices and advice when building a semantic model:

  • Create measures (using DAX) and hide relevant fact columns
  • On measure tables, ensure that only measures are made visible
  • On dimension tables, ensure only columns that make sense for analysis are made visible
  • ID columns, regardless of measure or dimension table, should be hidden
  • Format measures appropriately with currency symbols, thousand separators, percentages, etc.
  • Create hierarchies out of columns for users to easily use them in reports
  • Name tables and columns with proper business jargon, while formatting them to give maximum user-friendliness

Towards noon, while Ruthie got ready to start work back at her apartment, she received an email from Dan. He had created views on top of all the tables that she needed and had also created a special credential for her to access all this. Ruthie was content and started on her work.

When it comes to getting business value out of a business intelligence solution, there are a few cycles that one would have to go through. This includes new data points, change of visuals, and sometimes the underlying data model itself, along with changes to the user interface. This section outlined what can be expected when it comes to tweaking a self-service business intelligence solution, plus provided some rules and best practices that should be followed.

Aftermath

On Monday morning, Ruthie was super excited to show Stephen the results of her project. She had covered almost everything that he had asked her to.

The impressed Stephen spent most of the day understanding the analysis, playing around with the reports, and noting down feedback and changes that he wanted. He was now seeing real value: he could see which of his salespeople were pulling their weight, which products were successful in which regions, and how healthy his KPIs as a sales manager were. Throughout the course of the next few days, Stephen and Ruthie spent time perfecting the little solution. What they now had was a business intelligence solution built in-house using self-service.

When it comes to business intelligence, a solution need not be a comprehensive solution that spans multiple technologies, or multiple services, or many weeks of requirements gathering, or many months of development. The ultimate criterion is that it gives value fast. Hence, even a Power BI based model with a couple of reports, if done right, can be sufficient. However, today’s solution will not suffice tomorrow. The needs of business users keep changing; the questions they ask keep changing; the answers they seek keep changing. These changes may require more data from new and complex sources, and that’s when you start looking for new technologies or methods to help support the new requirements if necessary. Business Intelligence and Analytics, consequently, are evolutionary. It is a journey an organization needs to take.


The post The BI Journey: The Analyst appeared first on Simple Talk.


from Simple Talk http://bit.ly/2HmPyBt
via

Monday, January 21, 2019

Implementing DevOps Doesn’t Get Rid of Database Administrators

I hear from a lot of database administrators who are worried about being automated out of a job. These kinds of worries are not new.

Over the course of my career, I’ve seen CTOs outsource large groups of IT jobs to different regions around the world to save money. IT has long been regarded as a cost center from which the organization needs to get “good enough” service for the lowest amount of money.

With this history, many database administrators are wary of any change that might trigger layoffs. Improvements in database-as-a-service offerings from cloud providers now automate and outsource traditional DBA tasks such as backups and high availability, so this concern is back with a vengeance.

It is natural that DBAs are therefore somewhat wary of DevOps. The following assumptions are easily made:

  • If DevOps means “developers doing operations,” no jobs remain for the IT staff who did operations before
  • Further, DevOps emphasizes automation so that IT jobs are no longer needed

These two points, however, are mistaken.

IT jobs are changing, but they are not going away

CTOs around the world are changing their focus, based on pressure from their CEOs and Boards of Directors. Companies who continue to follow the model of improving their products and services slowly, while minimizing IT costs, are now at risk of going out of business. We live in a time when a clever organization can quickly enter a market and offer products and services which solve problems in a new way, rapidly attracting new customers via the internet and stealing market share away from established companies.

The leaders of older companies, burdened by legacy applications and staff working long days to maintain existing processes, are becoming rightfully worried about their survival. This is occurring across all industries, from food service to banking to lawnmower manufacturers.

To rapidly discover which new products and features attract and retain customers in markets full of “disruptors,” existing companies don’t want to make developers take over all of operations work. Even with automation, developers already have a large amount of skills to maintain and tasks to perform without becoming network administrators, database administrators, and security specialists.

Instead, the goal is to make the people in each of these roles more productive, and to change the way we work so that each of these roles can leverage the expertise of the other roles more efficiently.

As Andrew Hatch writes in his excellent article, “Why We Don’t Need a DevOps team,” DevOps brings Operations into Development and it brings Development Into Operations.

This doesn’t mean that IT staff need to learn six programming languages overnight – or even one. But it does mean that collaborating with developers, focusing on customer input, exploring scripting languages, and seeking to reduce manual work is a big part of the future of IT.

How will roles change over the next ten years?

Let’s look at the role of the DBA in the Microsoft Data Platform space. Microsoft is working hard to make services available that dramatically reduce the amount of work it takes to implement high availability and prevent data loss. They are also working on automatic tuning features which make it easier to identify root causes for poor performance and implement solutions.

With cloud adoption increasing in the Data Platform area, but competition between cloud providers remaining strong, it is likely that efforts in these areas will continue, and further improvements will be made.

Let’s think back to our CTO, who needs to change his or her organization to innovate more rapidly, with the ability to get feedback from users and quickly test out changes to products and services inexpensively.

What does that CTO really want from a DBA?

They want a specialist who can:

  • Tailor source control strategies for database code to work best for the organization
  • Automate testing and release of database code with the right review and approval gates to produce stable, safe deployments
  • Efficiently identify risky database changes which require careful code review
  • Quickly provision databases which mask or remove sensitive data for new projects
  • Optimize practices to reduce bugs and outages caused by database code releases

Will this be the only role of DBAs?

This is not the role of a developer, but rather the role of a Senior DBA who integrates well with development teams and specializes in the architecture, management, deployment, and tuning of database code.

We will continue to have a variety of specializations for database administrators – this will not be the only route to a ‘Senior’ level IT job with databases. However, standardization of database code into version control and automation of release processes will only grow in importance, so it’s a smart bet for all DBAs to become familiar with developer concepts and practices as they grow in their careers.

NOTE: I’ll be talking about “How DevOps keeps DBAs safe from being automated out of a job” with Redgate’s James King and my fellow Microsoft MVPs Hamish Watson and William Durkin on Thursday, March 28th. I’d love for you to join us for this free panel to discuss the future of DBA careers, and why DBAs are essential to DevOps. Register here.

Commentary Competition

Enjoyed the topic? Have a relevant anecdote? Disagree with the author? Leave your two cents on this post in the comments below, and our favourite response will win a $50 Amazon gift card. The competition closes two weeks from the date of publication, and the winner will be announced in the next Simple Talk newsletter.

The post Implementing DevOps Doesn’t Get Rid of Database Administrators appeared first on Simple Talk.


from Simple Talk http://bit.ly/2FSGZMm
via

Thursday, January 17, 2019

Introduction to Mobile Development with Unity

Two things were introduced in 2008 almost at the same time. The iOS and Google Play Store opened up the world of mobile gaming. This new world introduced a new way to play games, all on your smartphone. Since then, it has only gotten easier to create your own apps and release them on a store for all to download and play instantly. It should come as no surprise then that Unity can be used to easily create your own mobile projects. Whether you intend to make a game for yourself or for the world, for iOS or Android, you can make that vision come to life with Unity.

But where do you get started? The same place any creator should begin—with the basics. Follow along and you’ll create a basic app using Unity that does three simple tasks. The first objective is to tap on an object to make it change color. Next, a button will be created that the user may tap whenever they wish to lock the game camera in place. Why would you lock the camera? Well, for the final objective you will be rotating the in-game camera using your phone’s gyroscope. That’s right, by moving your phone in real life the camera will move in your game. All these tasks combine to create a simple app that introduces you to the basics of creating a mobile game in Unity.

Setup

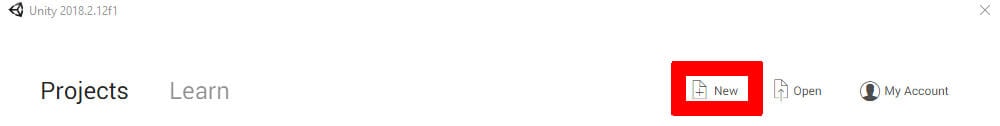
Creating the project is like any other Unity project. Being a mobile project does not change this part of the process. After opening Unity, create a new project as shown in Figure 1.

Figure 1: Creating a new project
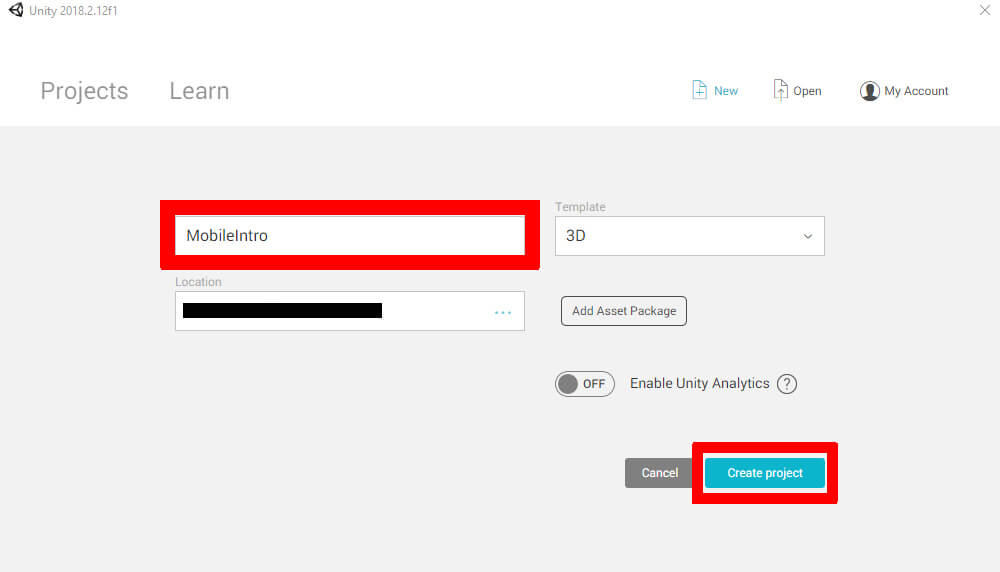
Next, name this MobileIntro. Make sure the project is a 3D project then choose the Location for the project. Once you’ve done all this, you’re ready to create the project. It should look similar to Figure 2.

Figure 2: Naming and creating the project.
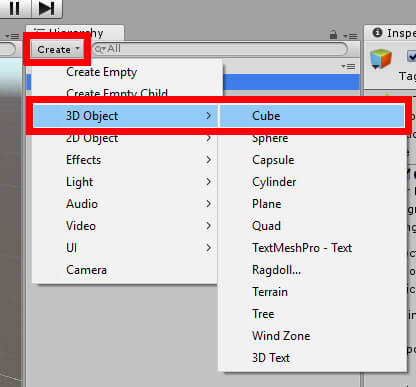
You may wish to start by creating the objects that will be important to this project. Start by creating a cube. This will be the object the user can tap to change its color to a random color. To create this object, click the Create button in the Hierarchy window. Then navigate to 3D Object->Cube to create the cube object as shown in Figure 3.

Figure 3: Creating a cube.

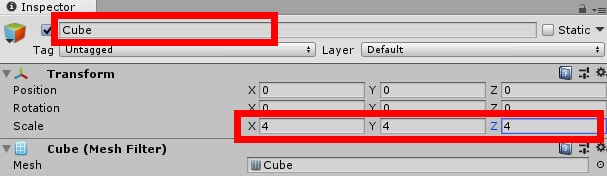
The cube is rather small at the moment, and anyone that’s done virtually anything with a mobile app knows how difficult it is to tap small objects. You’ll want to increase the cube’s size. Click on the Cube object in the Hierarchy. After this, navigate to the Inspector window and find the Transform component. This should be the first component you see at the very top of the Inspector window. Once found, change all variables in the Scale fields to four as shown in Figure 4.

Figure 4: Naming the object and setting the scale.

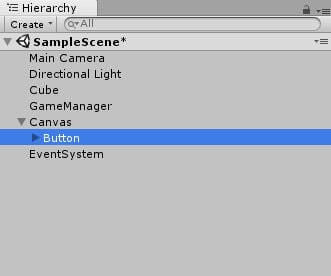
Next, you’ll create two more objects. The first is simply a manager that will hold the script that makes the project run. The second will be the user interface (UI) that the user can interact with to lock the game’s camera to its current position. Using the same Create menu in the Hierarchy window, create an empty game object and call it GameManager. Then, once again using the Create menu, navigate to UI->Button to create the button that the user will tap to perform the camera locking function. When finished, the Hierarchy should look similar to Figure 5 below.

Figure 5: The current hierarchy.

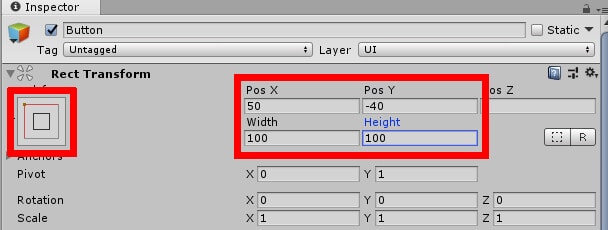
You may need to adjust the position of the button you just created to get it in exactly the position you want. Select the Button object in the Hierarchy window and go to the Transform component in the Inspector. Set the anchor to the top left part of the screen. Then set Pos X to 50 and Pos Y to -40. Finally, change the Width and Height of the button to 100 as shown in Figure 6.

Figure 6: Setting the anchor, position, width, and height.

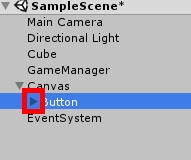
Next, you will want to change the text of the button to say LOCK. In the Hierarchy window, click the arrow next to the Button object as shown in Figure 7.

Figure 7: Opening the child objects.

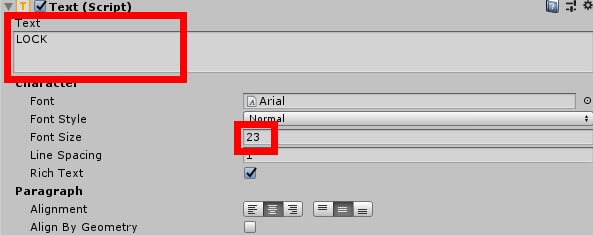
The button’s Text object will appear. Select it and navigate to the Text component in the Inspector window. You’ll then need to change the text to say LOCK, then adjust the size of the text using Font Size. When finished, the component should look like Figure 8 below.

Figure 8: Setting the text and font size.

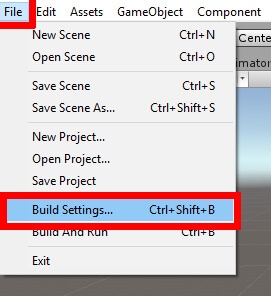
With this completed, all the objects needed for the project are in place, but it’s not quite time to write code yet. As this is intended to be a mobile project, you will need to perform a few actions to make the program run on your mobile device. From the top menu select File->Build Settings as shown in Figure 9.

Figure 9: Opening the build settings.

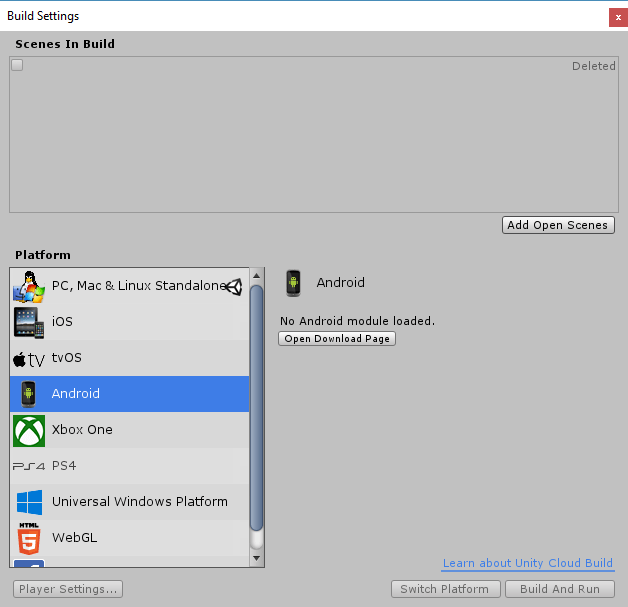
This opens up the Build Settings dialog which shows you the many platforms where you could run an app created in Unity. For each platform, however, different modules will need to be installed. Figure 10 shows the dialog and the message you’ll see about installing the module for Android development.

Figure 10: The Build Settings without having the necessary modules installed.

This is where you would go to build your project to be run on whichever device you choose. In addition, you can navigate to the player settings and change some properties of your build such as the image your application will use. Depending on how you installed Unity you may also need to install the Android or iOS modules for your copy of Unity. You can use the same Unity installer you used to install Unity onto your machine to do this. Just be sure to only select the Android and/or the iOS module for installation.

You may also need to download an SDK for your project to work. This example will be looking at how to install the Android SDK in particular. This can be accomplished either through command line tools or the Android Studio application. Instructions for both methods can be found in Unity’s documentation, found here.

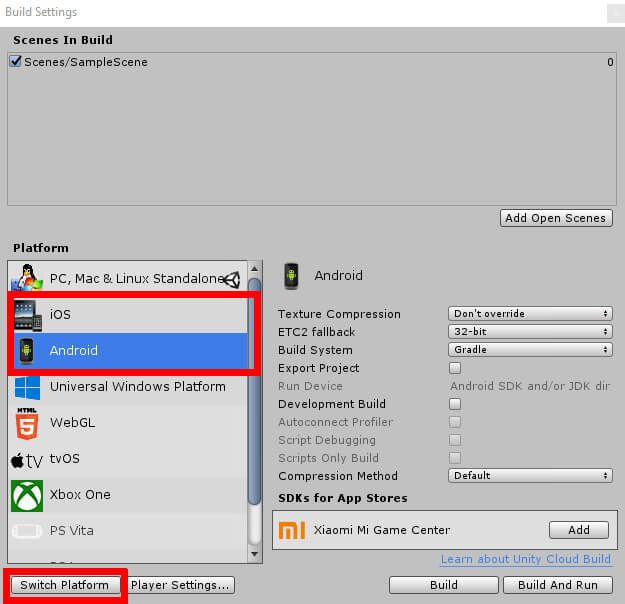
If you already have the above completed, then you’ll need to let Unity know that this is a mobile project. Once again, the example figures will show selecting Android devices as the platform of choice, but you should just as easily be able to use this project on an iOS device. Select the appropriate mobile device for you, then near the bottom of the Build Settings window you will need to click Switch Platform as shown in Figure 11.

Figure 11: Switching platforms.

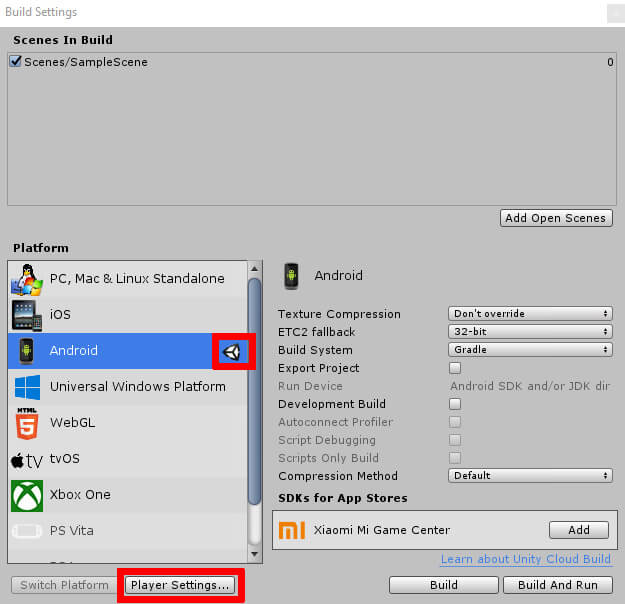
Once this is done, Unity will rebuild the project and set the target platform to your choice. You’ll see the Unity logo will be next to the platform you selected once the process is complete. Now you’ll need to change a few of the player settings for your project. To the immediate right of the Switch Platform button (now grayed out), click Player Settings shown in Figure 12.

Figure 12: Platform selected. Now on to player settings.

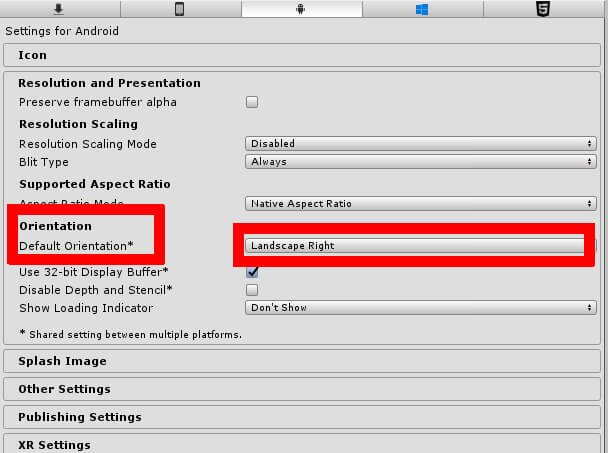
The Inspector window will change showing which player settings you can change for your project. You can do a lot here such as change the app icon or API settings. For this project you will start by changing the orientation of the app. Click Resolution and Presentation, then find the Orientation settings. This project will assume you set the orientation to Landscape Right. Figure 13 shows the settings.

Figure 13: Setting your app’s default orientation.

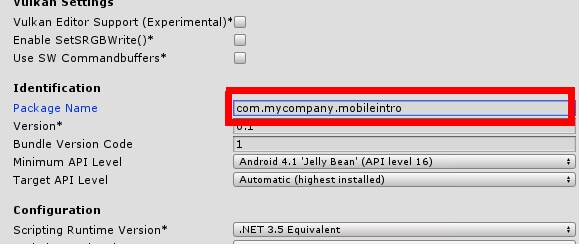
After this, search for Other Settings. In order to test your project on your phone later, you will need to set up a package name for the project. Under Other Settings you will need to locate the Package Name field. The required format for this package name is com.CompanyName.PackageName. Leave the com part of the name and change the CompanyName and PackageName. It can be set to whatever you wish, but the example below in Figure 14 will simply use com.mycompany.mobileintro as the package name for the project.
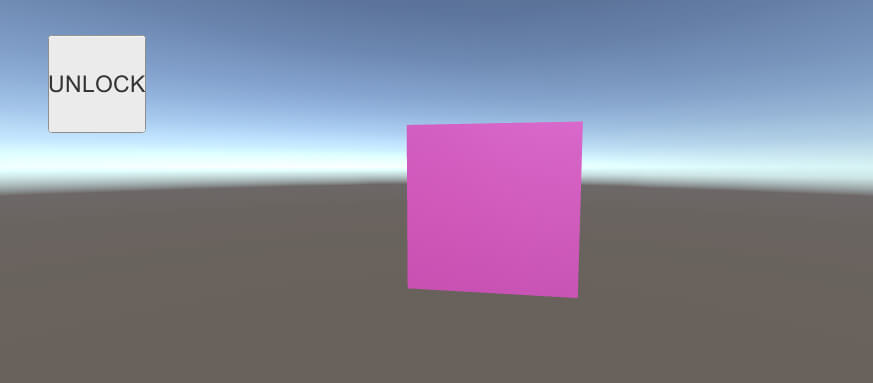
Figure 14: Creating a package name for apk file.

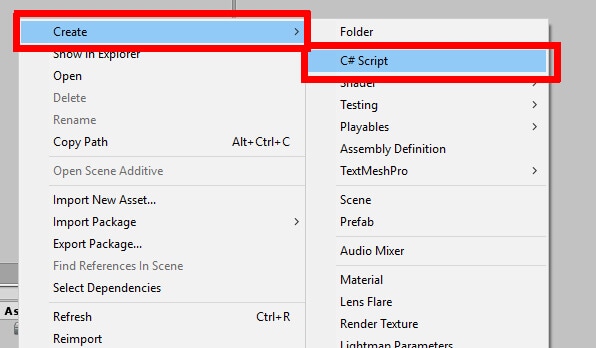
Your project’s mobile specific settings have now been configured, and it is time to write the project’s code. Right click in the Assets window and select Create->C# Script as shown in Figure 15.

Figure 15: Creating a C# script.

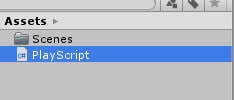
Name this script PlayScript. Once you’re done, the Assets window should look similar to Figure 16.

Figure 16: The Assets window with PlayScript

Double click the script to open it up in Visual Studio.

The Code

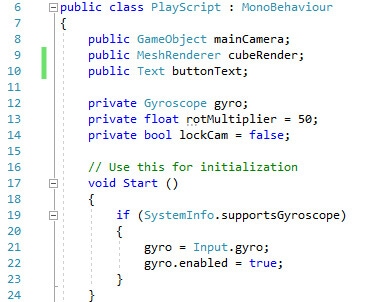
Thankfully, no additional using statements are needed to make this project. The line using UnityEngine should already be in the code upon creation. In addition, you’ll need to add using UnityEngine.UI in order to change the text of the UI button. Finally, you’ll need to declare some variables that will relate to three objects in the project. These objects are the in-game camera, the text in the button, and the cube you created.

public GameObject mainCamera;
public MeshRenderer cubeRender;
public Text buttonText;

After this, a few private variables will be declared. One of them is of the type Gyroscope. As you may have guessed, this has to do with your phone’s internal gyroscope that will be used to move the in-game camera. The next variable, called rotMultiplier, is used to increase how much the camera moves when you rotate your phone. By default, it’s not going to move very far. With this variable you can increase the amount the camera moves whenever the gyroscope detects rotation. In this example the value of rotMultiplier is fifty, but you may need to adjust this number in your own project. Finally, a boolean is created that will tell the project whether to lock the camera or not.

private Gyroscope gyro;
private float rotMultiplier = 50;
private bool lockCam = false;

Now, you move on to the Start function. Whenever the game starts, there will be a quick check to see if the phone you’re using has a gyroscope. Most mobile devices these days have gyroscopes, so why even have the check? This is primarily done to enable the gyroscope functionality for Unity. If for some reason, a mobile device lacks a gyroscope, this could prevent the project from crashing. In that event, you would most likely desire to add an else statement after the if statement and perform anything you wish the project to do in the event that the gyroscope is unavailable. However, this example will assume that your device has a gyroscope, and that no further code is needed. In the interest of good coding habits, the if statement will be used in this example.

if (SystemInfo.supportsGyroscope)
{
        gyro = Input.gyro;
        gyro.enabled = true;
}

The Start function is complete and the code should look similar to Figure 17.

Figure 17: Variable declarations and Start function.

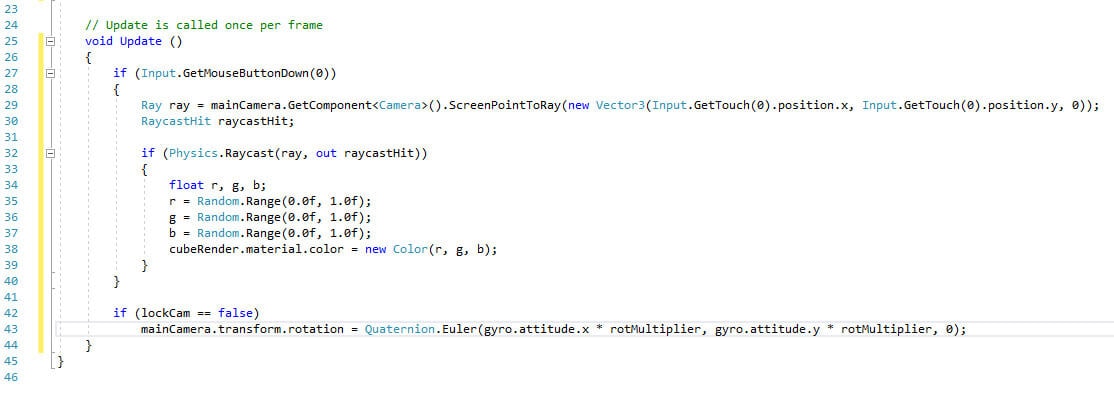
Next, you’ll need to move on to the Update function. Here you will code in the functionality to detect when the cube has been tapped on as well as the camera rotation. The code that catches when the cube has been tapped is as follows:

if (Input.GetMouseButtonDown(0))
{
        Ray ray = mainCamera.GetComponent<Camera>().ScreenPointToRay(
                 new Vector3(Input.GetTouch(0).position.x, 
                 Input.GetTouch(0).position.y, 0));
        RaycastHit raycastHit;
        if (Physics.Raycast(ray, out raycastHit))
        {
                float r, g, b;
                r = Random.Range(0.0f, 1.0f);
                g = Random.Range(0.0f, 1.0f);
                b = Random.Range(0.0f, 1.0f);
                cubeRender.material.color = new Color(r, g, b);
        }
}

That’s curious. Why are you looking for mouse input? Here’s a handy little tip about Unity. You can use some of the same code that you would use for both games that run on a desktop computer as well as games that run on mobile devices. While you could specifically search for a tap of the screen, you may find it easier to simply look for a mouse click. Plus, if you aim to make a project that can work on both PC and mobile, that’s less code to change for each version. This can also be helpful when testing the program on a desktop computer before performing further testing on mobile.

You check to see if a mouse click has occurred. Once you do that, a raycast is created at the point where the mouse cursor was located at the time. A raycast can be thought of as an arrow being shot forward. If it hits something, the program can then gain information on what was hit and even change the object in question upon impact. A good example of this lies in nearly every first-person shooter game. Whenever you fire a gun, you’re not really shooting a bullet out of a gun. Rather, the game is firing a raycast from the gun. Depending on what it hits, a certain action will occur whether that be damaging an enemy or leaving a hole in the wall.

In this case, whenever a raycast hits your cube, the cube will get a new random color applied to it. After getting three random numbers representing red, green, and blue, you get the color variable from cubeRender and assign the new color. After these, you create the code that controls the camera movement. These next two lines of code are fairly simple. If the lockCam variable is false, then rotate the camera based on the inputs from the gyroscope.

if (lockCam == false)
   mainCamera.transform.rotation = 
       Quaternion.Euler(
            gyro.attitude.x * rotMultiplier, 
            gyro.attitude.y * rotMultiplier, 0);

With this code entered into the Update function, you can now move on. The code should look like Figure 18.

Figure 18: The Update function.

Before exiting Visual Studio, there’s one last function to be created. This function, called LockCamera, will be put to use in the UI button you made earlier. Whenever you tap that button, this function will be called. All it does is set lockCam to true or false and changes the text in your button. Placed underneath the Update function, the code looks like this:

public void LockButton()
{
        if (lockCam == false)
        {
                lockCam = true;
                buttonText.text = "UNLOCK";
        }
        else
        {
                lockCam = false;
                buttonText.text = "LOCK";
        } 
}

And with that out of the way, the code for this project is complete. Save your work and head back to the Unity editor to finish the project.

Completing the Project

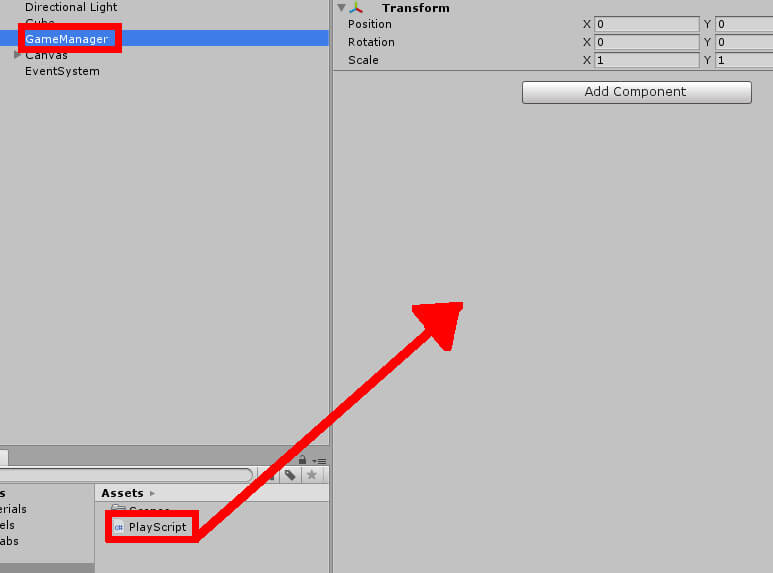
Remember the GameManager object from before? You’ll attach your freshly made script to this object. With GameManager selected in the Hierarchy, click and drag PlayScript from the assets window into the Inspector as shown in Figure 19.

Figure 19: Attaching PlayScript to the GameManager

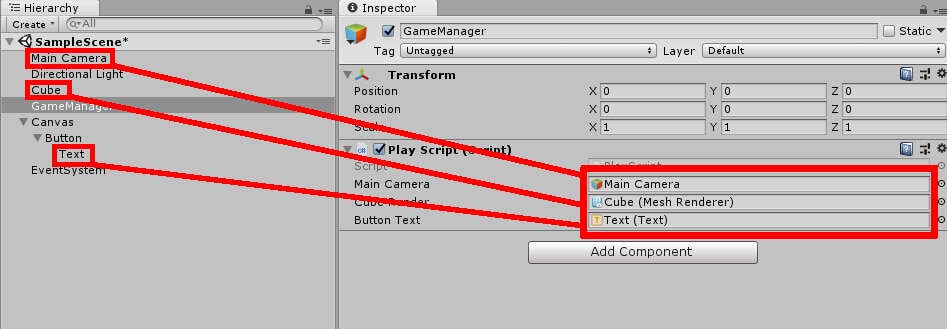
Next, you’ll need to fill in the Main Camera and Cube Render fields. In the Hierarchy, select the Main Camera object and drag it into the Main Camera field. Likewise, drag Cube into Cube Render. Figure 20 shows how this looks.

Figure 20: Setting the Main Camera, Button Text, and Cube Render variables.

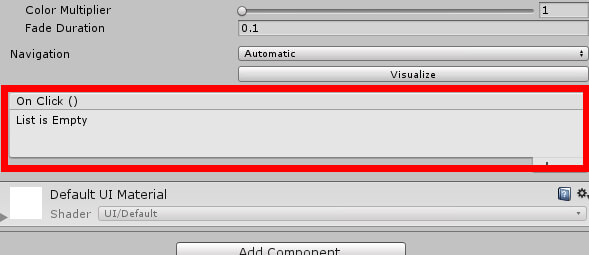
Next, locate the Button object in the Hierarchy. After selecting it, find the On Click event list in the Inspector as shown in Figure 21.

Figure 21: List of On Click events, currently empty.

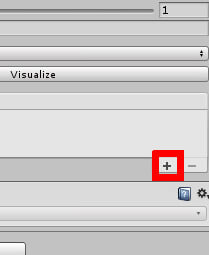
Click the + icon to add a new On Click event to your button shown in Figure 22.

Figure 22: Adding an On Click event.

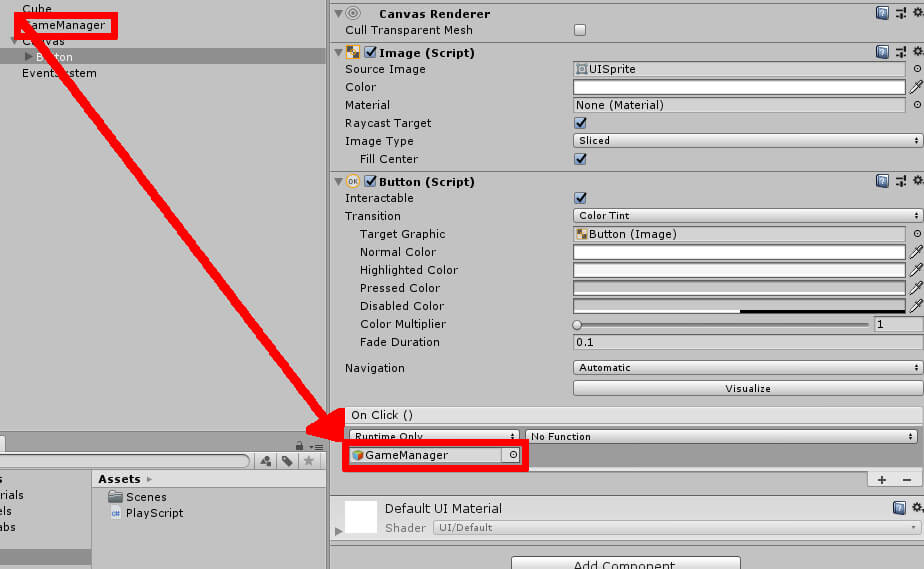
After this you will need to click and drag GameManager from the Hierarchy into the Object field. Figure 23 shows you what to do.

Figure 23: Setting GameManager as the object to pull code from.

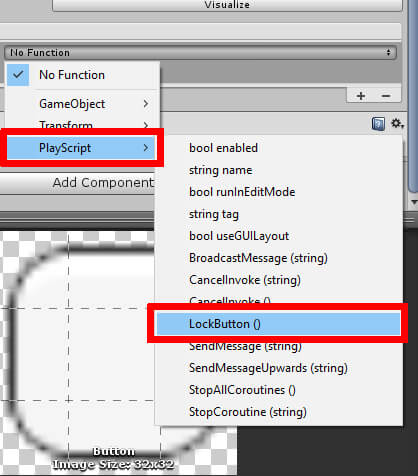
Once this is complete, click the drop down menu that current says No Function. Navigate to PlayScript->LockButton to set the LockButton function to this button’s On Click event as shown in Figure 24.

Figure 24: Setting LockButton as the function to call when your button is tapped.

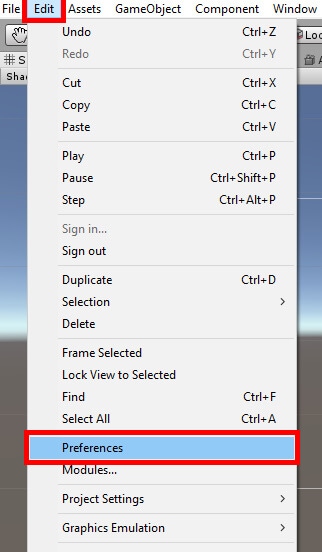
Two steps remain before you can test your project out properly. The necessary modules and SDK you need for the project have been installed. Unfortunately, the SDK doesn’t do much good if Unity doesn’t know where it is. Go to Edit->Preferences to take care of that as shown in Figure 25.

Figure 25: Accessing Unity Preferences.

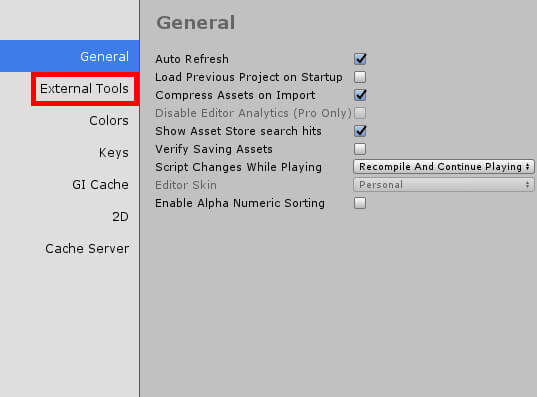
This opens the Unity Preferences dialog where you adjust settings such as the colors Unity uses. For this project, you’ll want to navigate to External Tools shown in Figure 26.

Figure 26: Navigating to External Tools.

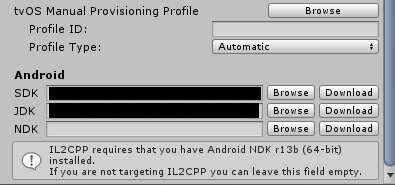
Scroll down until you find settings for Android. This is where you specify the file path for your SDK as well as the JDK (Java Development Kit) and Android NDK. You can also download the things you need using the convenient Download button. For mobile projects, you’ll at least want the SDK and JDK filled in. After installing everything you need, use the Browse button and find the path to your SDK and JDK as shown in Figure 27.

Figure 27: Specifying a path for the Android SDK and JDK.

There’s another step involved to make this project run on your phone, but it takes place outside of Unity. You’ll need to enable developer mode on your mobile device in order to build the project to your phone. On Android, you simply need to navigate to Settings->About phone->Software Information and then find the Build Number. Tap Build Number multiple times to enable developer mode on your phone. For iOS, the process is a little different. You’ll need Xcode running on your desktop, followed by plugging a USB cable from your phone into the computer. From there, navigate your settings until you find Developer. Finding this means you have developer mode enabled on your phone.

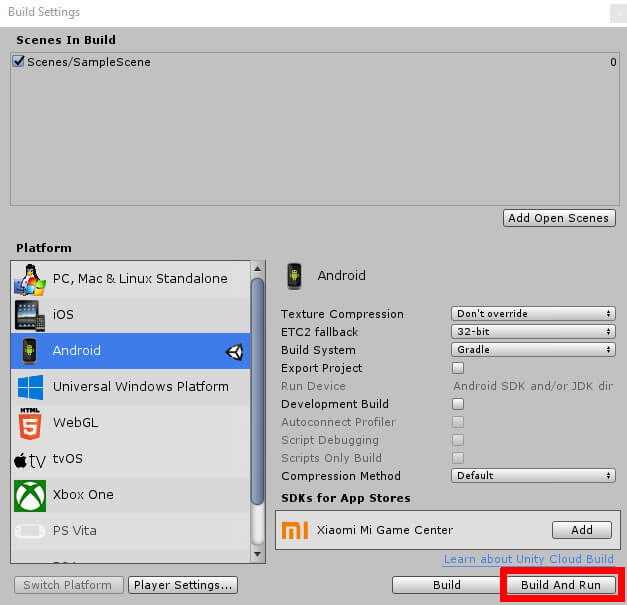
After all the above steps have been completed, your project is now ready, but how do you test this out on your phone? After all, it’s hard to test gyroscope functionality on a desktop computer. You can get around this by navigating to File->Build Settings. Once there, you’ll need to click the Build and Run button near the bottom of the window shown in Figure 28.

Figure 28: Building your project and running it on your mobile device.

This will build your game and then upload it to your phone. From there the program should begin running on your phone. Of course, you will need a USB cable connected from your computer to your mobile device for this method to work. Another window will pop up before the build begins saying you need to save the apk file somewhere on your computer. You may save this file wherever you wish, as it will not affect building the apk to your phone. In addition, it’s possible that a dialogue box with a message about JDK will pop up saying it found an up to date version. Go ahead and click Yes on this dialogue.

Once the build is complete, you should see your project begin to play on your phone. If for some reason it doesn’t play automatically, try searching around your apps and see if MobileIntro is anywhere to be found. Once the game begins, go ahead and rotate the device and notice the in-game camera move with your phone’s movements. If there’s a certain angle you like, you can tap the UI button near the top right to lock the camera in place. Finally, try tapping the cube and watch it change to a random color. Remember when I said that you can look for mouse input when looking for taps on your phone screen? You can see that in action both by tapping the cube and tapping the UI button. The app will look something like Figure 29.

Figure 29: Mobile project in action.

Conclusion

As you can see, creating a mobile project is easier than you might think. If you ever wanted to create another mobile game in the future, some settings you edited here in Unity would carry over into other projects, namely the path to the SDK. In some cases, there isn’t much difference between code for a mobile project and code for a PC project, so controlling different versions of the same app becomes easier too. However, it would have been a little underwhelming if all you did was make code that works on both PC and mobile, so you took advantage of your mobile device’s gyroscope to move the camera in time with your own movements. From here you can build off this example project to create your own mobile experience, whatever that may be.


The post Introduction to Mobile Development with Unity appeared first on Simple Talk.


from Simple Talk http://bit.ly/2swfrod
via