Tuesday, February 11, 2020

Get Your Scalar UDFs to Run Faster Without Code Changes

Over the years, you probably have experienced or heard that using user-defined functions (UDF’s) do not scale well as the number of rows processed gets larger and larger. Which is too bad, because we have all heard that encapsulating your code into modules promotes code reuse and is a good programming practice. Now the Microsoft SQL Server team have added a new feature to the database engine in Azure SQL Database and SQL Server 2019 that allows UDF’s performance to scale when processing large recordsets. This new feature is known as T-SQL Scalar UDF Inlining.

T-SQL Scalar UDF Inlining is one of many new features to improve performance that was introduced in the Azure SQL Database and SQL Server 2019. This new feature contains many options available in the Intelligent Query Processing (IQP) feature set. Figure 1 from Intelligent Query Processing in SQL Databases shows all the IQP features introduced in Azure SQL Database and SQL Server 2019, as well as features that originally were part of the Adaptive Query Processing feature set that was included in the older generation of Azure SQL Database and SQL Server 2017.
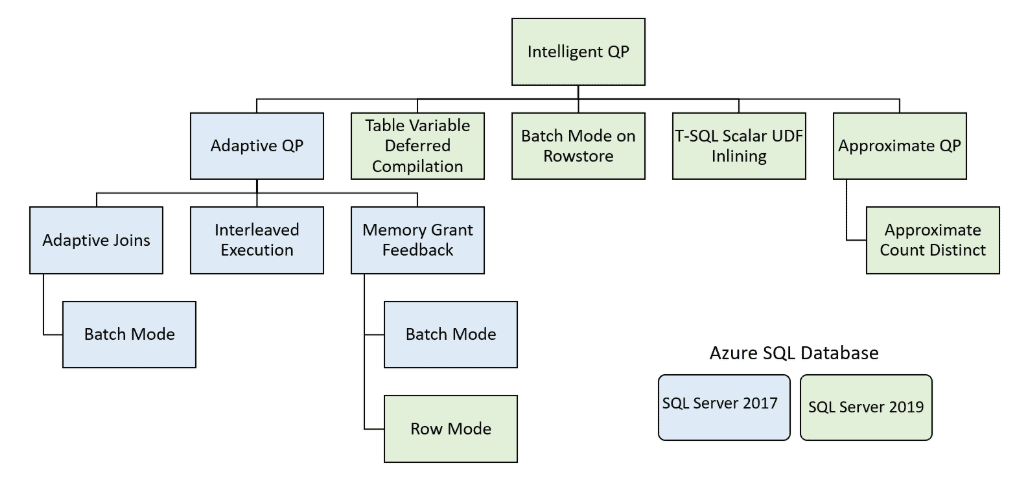
Figure 1: Intelligent Query Processing

The T-SQL Scalar UDF Inlining feature will automatically scale UDF code without having to make any coding changes. All that is needed is for your UDF to be running against a database in Azure SQL Database or SQL Server 2019, where the database has the compatibility level set to 150. Let me dig into the details of the new inlining feature a little more.

T-SQL Scalar UDF Inlining

The new T-SQL Scalar UDF Inlining feature will automatically change the way the database engine interprets, costs, and executes T-SQL queries when a scalar UDF is involved. Microsoft incorporated the FROID framework into the database engine to improve the way scalar UDFs are processed. This new framework refactors the imperative scalar UDF code into relational algebraic expressions and incorporates these expressions into the calling query automatically.

By refactoring the scalar UDF code, the database engine can improve the cost-based optimization of the query as well as perform set based optimization that allows the UDF code to go parallel if needed. Refactoring of scalar UDFs is done automatically when a database is running under compatibility level 150. Before I dig into the new scalar UDF inlining feature, let me review why scalar UDF’s are inherently slow, and discuss the differences between imperative and relational equivalent code.

Why are Scalar UDF Functions inherently slow?

When running a scaler UDF on a database with a compatibility level set to less than 150, they just don’t scale well. By scale, I mean they work fine for a few rows but run slower and slower as the number of rows processed gets larger and larger. Here are some of the reasons why scalar UDF’s don’t work well with large recordsets.

  • When a T-SQL statement uses a scalar function, the database engine optimizer doesn’t look at the code inside a scalar function to determine its costing. This is because Scalar operators are not costed, whereas relational operators are costed. The optimizer considers scalar functions as a black box that uses minimal resources. Because scalar operations are not costed appropriately, the optimize is notorious for creating very bad plans when scalar functions perform expensive operations.
  • A Scalar function is evaluated as a batch of statements where each statement is run sequentially one statement after another. Because of this, each statement has its own execution plan and is run in isolation from the other statements in the UDF, and therefore can’t take advantage of cross-statement optimization.
  • The optimize will not allow queries that use a scalar function to go parallel. Keep in mind, parallelism may not improve all queries, but when a scalar UDF is being used in a query, that query’s execution plan will not go parallel.

Imperative and Relational Equivalent Code

Scalar UDFs are a great way to modularize your code to promote reuse, but all too often they contain procedural code. Procedural code might contain imperative code such as variable declarations, IF/ELSE structures, as well as WHILE looping. Imperative code is easy to write and read, hence why imperative code is so widely used when developing code for applications.

The problem with imperative code is that it is hard to optimize, and therefore query performance suffers when imperative code is executed. The performance of imperative code is fine when a small number of rows are involved, but as the row count grows, the performance starts to suffer. Because of this, you should not use them for larger record sets if they are executed on a database running with a compatibility less than 150. With the introduction of version 15.x of SQL Server, the scaling problem associated with UDFs has been solved by the refactoring of imperative code using a new optimization technique known as the FROID framework.

The FROID framework refactors imperative code into a single relational equivalent query. It does this by analyzing the scalar UDF imperative code and then converts blocks of imperative code into relational equivalent algebraic expressions. These relational expressions are then combined into a single T-SQL statement using APPLY operators. Additionally, the FROID framework looks for redundant or unused code and removes it from the final execution plan of the query. By converting the imperative code in a scalar UDF into re-factored relational expressions, the query optimizer can perform set-based operations and use parallelism to improve the scalar UDF performance. To further understand the difference between imperative code and relational equivalent code, let me show you an example.

Listing 1 contains some imperative code. By reviewing this listing, you can see it includes a couple of DECLARE statements and some IF/ELSE logic.

Listing 1: Imperative Code Example

DECLARE @Sex varchar(10) = 'Female';
DECLARE @SexCode int;
IF @Sex = 'Female'
        SET @SexCode = 0
ELSE 
        IF @Sex = 'Male'
           SET @SexCode = 1;
     ELSE 
        SET @SexCode = 2;
SELECT @SexCode AS SexCode;

I have then re-factored the code in Listing 1 into a relational equivalent single SELECT statement in Listing 2, much like the FROID framework might doing it when compiling a scalar UDF.

Listing 2: Relational Code Example

SELECT B.SexCode FROM (SELECT 'Female' AS Sex) A
OUTER APPLY  
  (SELECT CASE WHEN A.Sex = 'Female' THEN 0 
                  WHEN A.Sex = 'Male' THEN 1
                     ELSE 2 
                END AS SexCode) AS B;

By looking at these two examples, you can see how easy it is to read the imperative code in Listing 1 to see what is going on. Whereas in Listing 2, which contains the relational equivalent code, requires a little more analysis/review to determine exactly what is happening.

  • Currently, the FROID framework is able to rewrite the following scalar UDF coding constructs into relational algebraic expressions:
  • Variable declaration and assignments using DECLARE or SET statement
  • Multiple variable assignments in a SELECT statement
  • Conditional testing using IF/ELSE logic
  • Single or multiple RETURN statements
  • Nested/recursive function calls in a UDF
  • Relational operations such as EXISTS and ISNULL

The two listings found in this section only logically demonstrate how the FROID framework might convert imperative UDF code into relational equivalent code using the FROID framework. For more detailed information on the FROID framework, I suggest you read this technical paper.

In order to see FROID optimization in action, let me show you an example that compares the performance of a scalar UDF running with and without FROID optimization.

Comparing Performance of Scalar UDF with and Without FROID Optimization

To test how a scalar UDF would perform with and without FROID optimization, I will run a test using the sample WorldWideImportersDW database (download here). In that database, I’ll create a scalar UDF called GetRating. The code for this UDF can be found in Listing 3.

Listing 3: Scalar UDF that contains imperative code

CREATE OR ALTER FUNCTION dbo.GetRating(@CityKey int)
RETURNS VARCHAR(13) 
AS 
BEGIN
   DECLARE @AvgQty DECIMAL(5,2);
   DECLARE @Rating VARCHAR(13);
   SELECT @AvgQty  = AVG(CAST(Quantity AS DECIMAL(5,2)))
   FROM Fact.[Order]
   WHERE [City Key] = @CityKey;
   IF @AvgQty / 40 >= 1  
          SET @Rating = 'Above Average';
   ELSE 
          SET @Rating = 'Below Average'; 
   RETURN @Rating
END

By reviewing the code in Listing 3 you can see that I am creating my scalar UDF that I will be using for testing. This function calculates a rating for a [City Key] value. The rating returned is either “Above Average” or “Below Average” based on 40 being the average rating. Note that this UDF contains imperative code.

In order to test how scalar inlining can improve performance I will be running the code in Listing 4.

Listing 4: Code to test performance of scalar UDF

-- Turn on Time Statistics
SET STATISTICS TIME ON;
GO
USE WideWorldImportersDW;
GO
-- Set Compatibility level to 140
ALTER DATABASE WideWorldImportersDW SET COMPATIBILITY_LEVEL = 140;
GO
-- Test 1
SELECT DISTINCT ([City Key]), dbo.GetRating([City Key]) AS CityRating
FROM Dimension.[City]
-- Set Compatibility level to 150
ALTER DATABASE WideWorldImportersDW SET COMPATIBILITY_LEVEL = 150;
GO
-- Test 2
SELECT DISTINCT ([City Key]), dbo.GetRating([City Key]) AS CityRating
FROM Dimension.[City]
GO

The code in Listing 4 runs two tests. The first test (Test 1) calls the scaler UDF dbo.GetRating using compatibility level 140 (SQL Server 2017). For the second test (Test 2), I only changed the compatibility level to 150 (SQL Server 2019) and ran the same UDF as Test 1 without making any coding changes to the UDF.

When I run Test 1 in Listing 4, I get the execution statistics shown in Figure 2 and the execution plan shown in Figure 3.
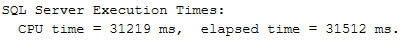
Figure 2: Execution Statistics for Test 1
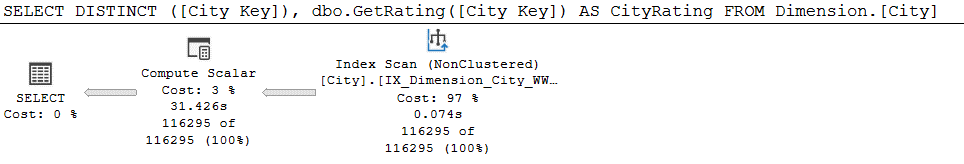
Figure 3: Execution plan when using compatibility level 140 using Test 1

Prior to reviewing the time statistics and execution plan for Test 1 let me run Test 2. The time statistics and execution plan for Test 2 can be found in Figure 4 and Figure 5, respectfully.
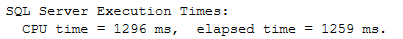
Figure 4: Execution Statistics for Test 2
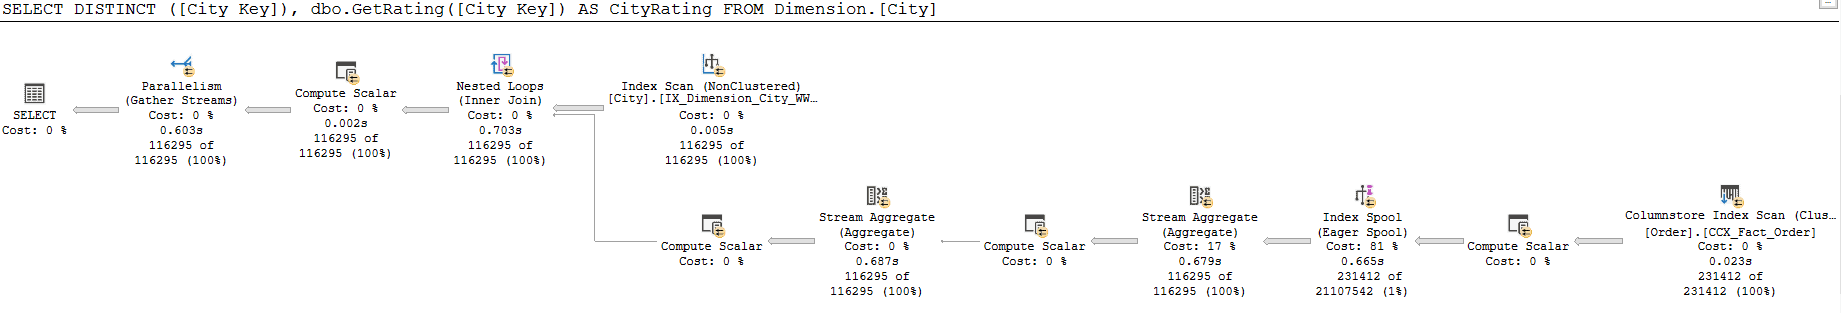
Figure 5: Execution plan when using compatibility level 150 using Test 2

Performance Comparison between Test 1 and Test 2

The only change I made between Test 1 and Test 2 was to change the compatibility level from 140 to 150. Let me review how the FROID optimization changed the execution plan and improved the performance when I executed my test using compatibility level 150.

Before running the two different tests, I turned on statistics time. Figure 6 compares the time statistics between the two different tests.
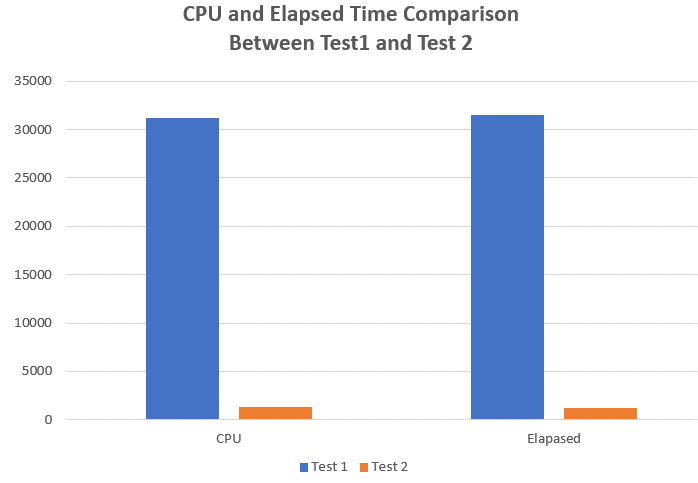

Figure 6: CPU and Elapsed Time Comparison Between Test 1 and Test 2

As you can see, when I executed the Test 1 SELECT statement in Listing 4 using compatibility level 140, the CPU and elapsed time took a little over 30 seconds. Whereas, when I changed the compatibility level to 150 and ran the Test 2 SELECT statement in Listing 4, my CPU and Elapsed time used just over 1second of time each. As you can see, Test 2, which used compatibility level 150 and the FROID framework, ran magnitudes faster than List 1 which ran under compatibility 140 without the FROID framework optimization. The improvement I gained using the FRIOD framework and compatibility level 150 achieved this performance improvement without changing a single line of code in my test scalar UDF. To better understand why the time comparisons were so drastically different between these two executions of the same SELECT statement, let me review the execution plans produced by each of these test SELECT queries.

If you look at Figure 3, you will see a simple execution plan when the SELECT statement was run under compatibility 140. This execution plan didn’t go parallel and only includes two operators. All the work related to calculating the city rating in the UDF using the data in the Fact.[Order] table is not included in this execution plan. To get the rating for each city, my scalar function had to run multiple times, once for every [City Key] value found in the Dimension.[City] table. You can’t see this in the execution plan, but if you monitor the query using an extended event, you can verify this. Each time the database engine needs to invoke my UDF in Test 1, a context switch has to occur. The cost of the row by row operation nature of calling my UDF over and over again causes the query in Test 1 to run slow.

If we look at the execution plan in Figure 5, which is for Test 2, you see a very different plan as compared to Test 1. When the SELECT statement in Test 2 was run, it ran under compatibility level 150, which allowed the scalar function to be inlined. By inlining the scalar function, FROID optimization converted my scalar UDF into a relational operation which allowed my UDF logic to be included in the execution plan of the calling SELECT statement. By doing this, the database engine was able to calculate the rating value for each [City Key] using a set-based operation, and then joins the rating value to all the cities in the Dimension.[City] table using an inner join nested loop operation. By doing this set based operation in Test 2, my query runs considerably faster and uses fewer resources than the row by row nature of my Test 1 query.

Not all Scalar Functions Can be Inlined

Not all scalar function can be inlined. If a scalar function contains coding practices that cannot be converted to relational algebraic expressions by the FRIOD framework, then your UDF will not be inlined. For instance, if a scalar UDF contains a WHILE loop, then the scalar function will not be inlined. To demonstrate this, I’m going to modify my original UDF code so it contains a dummy WHILE loop. My new UDF is called dbo.GetRating_Loop and can be found in Listing 5.

Listing 5: Scalar UDF containing a WHILE loop

CREATE OR ALTER FUNCTION dbo.GetRating_Loop(@CityKey int)
RETURNS VARCHAR(13) 
AS 
BEGIN
   DECLARE @AvgQty DECIMAL(5,2);
   DECLARE @Rating VARCHAR(13);
-- Dummy code to support WHILE loop
   DECLARE @I INT = 0;
   WHILE @I < 1
   BEGIN
          SET @I = @I + 1;
   END
   SELECT @AvgQty  = AVG(CAST(Quantity AS DECIMAL(5,2)))
   FROM Fact.[Order]
   WHERE [City Key] = @CityKey;
   IF @AvgQty / 40 >= 1  
          SET @Rating = 'Above Average';
   ELSE 
          SET @Rating = 'Below Average'; 
   RETURN @Rating
END

By reviewing the code in Listing 5, you can see I added a dummy WHILE loop at the top of my original UDF. When I run this code using the code in Listing 6, I get the execution plan in Figure 7.

Listing 6: Code to run dbo.GetRating_Loop

USE WideWorldImportersDW;
GO
-- Set Compatibility level to 150
ALTER DATABASE WideWorldImportersDW SET COMPATIBILITY_LEVEL = 150;
GO
-- Test UDF With WHILE Loop
SELECT DISTINCT ([City Key]), 
    dbo.GetRating_Loop([City Key]) AS CityRating
FROM Dimension.[City]
GO
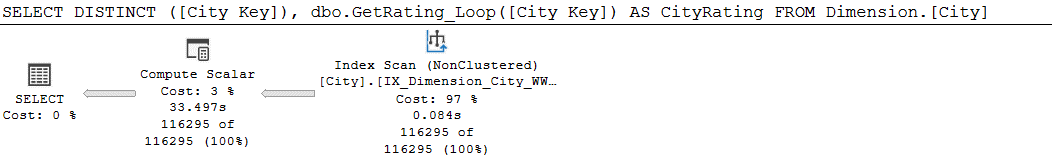
Figure 7: Execution plan created while execution Listing 6.

By looking at the execution plan in Figure 7, you can see that my new UDF didn’t get inlined. The execution plan for this test looks very similar to the execution plan I got when I ran my original UDF in Listing 3 under database compatibility level 140. This example shows not all scalar UDF functions will be inlined. Just those scalar UDF that use only the functionality support by the FRIOD framework will be inline.

Disabling Scalar UDF Inlining

With this new version of SQL Server, the design team wanted to make sure you could disable any new features at the database level or statement level. Therefore, you can use the code in Listing 6 or 7 to disable scalar UDF inlining. Listing 6 shows how to disable scalar UDF inlining at the database level.

Listing 6: Disabling inlining at the database level

ALTER DATABASE SCOPED CONFIGURATION SET TSQL_SCALAR_UDF_INLINING = OFF;

Listing 7 shows how to disable scalar inlining when the scalar UDF is created.

Listing7: Disabling when defining UDF

CREATE FUNCTION dbo.MyScalarUDF (@Parm int)
RETURNS INT
WITH INLINE=OFF
...

Make Your Scalar UDF just Run faster by Using SQL Server version 15.x

If you want to make your Scalar UDF run faster without making any coding changes, then SQL Server 2019 is for you. With this new version of SQL Server, the FROID framework was added. This framework will refactor a scalar UDF function into relational equivalent code that can be placed directly into the calling statement’s execution plan. By doing this, a scalar UDF is turned into a set-based operation instead of being called for every candidate row. All it takes to have a scalar UDF refactored is to set your database to compatibility level 150.


The post Get Your Scalar UDFs to Run Faster Without Code Changes appeared first on Simple Talk.


from Simple Talk https://ift.tt/2Sd9sCy
via

Monday, February 10, 2020

Why Empathy is Not Enough in Tech

In 2020, my main personal goal is to reduce doing harm, and this has been mainly inspired by the work of Kim Crayton and the #causeascene Guiding Principles. Kim is a business strategist, tech leader coach, professional educator, and founder of the #causeascene movement.

Tech is not neutral.

Actually, it has never been neutral, nor has it been apolitical. While we, as developers, want to believe differently, the news is full of examples of how tech has been and is continuously used to harm people, especially the ones that are already most vulnerable:

  • Careless or intentionally malicious handling of private data (Facebook)
  • Nonconsensual use of Profile picture to use as (flawed and insecure) face recognition (AirBnB)
  • Tech companies using their products to spy on employees and shut down protests (Google)
  • Racism and sexism built directly into AI algorithms (Amazon)
  • Social Media being used to harass and shutdown members of marginalized groups, spread fake-news and amplify hate

But it doesn’t stop at the big tech companies; harm is being done on all levels, be it the language used by technologists (“If you don’t get this, you have no business in coding”, “Problem exists between keyboard and chair”), the bias in hiring process (“Not a culture fit”) or the use of racist terms and “jokes” under the coat of freedom of speech.

These harmful actions, processes, and policies have come at great cost for teams, the trade as such, and also its products.

It has led to an artificially narrowed pool of “talent” and therefore also a narrowed viewpoint, rendering many tech companies unable to predict the potential harm their products and services are causing.

Luckily, there’s empathy and compassion – let’s assume we have good intentions, and if we try hard enough to walk in each other’s shoes, we’ll be able to solve all the problems we don’t even know exist. How hard can it be to imagine how a black woman in her 50s from the other side of the globe will use our software. As a white man in my 30s, I just must be empathetic enough, right?

In fact, we’re not even able to be empathetic enough to create soap dispensers or fitness trackers that work on non-white skin tones.

Don’t get me wrong – empathy is a great skill to develop, but it can never be a replacement for authentic lived experience. The only chance to really broaden our views is to introduce diversity into our teams, and to be able to do so, we need to become inclusive. Focusing on being compassionate won’t do it if we don’t develop a clear strategy.

“The road to hell is paved with good intentions”

If we want to stop doing harm, we need to create strategies that allow us to focus on the impact of our actions. We need strategies that allow us to learn what impact our actions have on people different than us, what (unintended) side-effects our actions have, how our work can be used in ways we don’t wan,t and how we can learn and improve from mistakes we made.

Commentary Competition

Enjoyed the topic? Have a relevant anecdote? Disagree with the author? Leave your two cents on this post in the comments below, and our favourite response will win a $50 Amazon gift card. The competition closes two weeks from the date of publication, and the winner will be announced in the next Simple Talk newsletter.


The post Why Empathy is Not Enough in Tech appeared first on Simple Talk.


from Simple Talk https://ift.tt/2w7JZSv
via

But the Database Worked in Development! Checking for Duplicates

The series so far:

Like all grownup database developers, you will do your best to ensure that there are unique constraints and unique indexes in place to prevent duplicates ever getting into the database. These checks are essential, and the RDBMS requires very little effort to make the check when data is inserted. Unless you are working with a very good business analyst, you’ll always miss a few when you create a database, so the addition or alteration of these duplicate checks are an essential part of database maintenance.

Where you were able to do development work on the actual production database, you could check and remove existing duplicates, before you added these constraints, and then provide a data-migration script to go with the deployment. Nowadays, it is more awkward. You’ll probably be required to work on masked data or entirely generated data. You cannot check data if it isn’t exactly what is on production, and it is difficult to predict what could be lurking in the production data.

Now, you have to do all your development work on the constraints and rely on someone else to run the code to remove the duplicates. This is potentially awkward, unless you change your habits to allow easier cooperation between teams. You can, however, very easily generate the code to do these checks, and, even if someone else runs the code, have enough detail about the offending rows to be able to correct the data in a migration script, which can be tested by Ops people on staging.

The same applies to an automated build process. When you’re building a database and then loading in data, it’s much better to check a dataset before constraints are enabled. Once again, what you need is a test script that runs the checks and reports on all the offending rows and only enables constraints if there is no data that would cause an error.

The first article in the series went over the principles of how you might do this as part of a deployment process, with check constraints. Now we move on to checking for duplicates, as defined by your unique indexes.

Reporting on what must be unique in a database

To determine what is defined as being unique in a database, you need to look at both unique constraints that cause a unique index to be created automatically, and unique indexes that are declared directly and explicitly. (All code samples in this series can be found on GitHub.)

DROP PROCEDURE IF EXISTS #ListAllUniqueIndexes
GO
CREATE PROCEDURE #ListAllUniqueIndexes
/**
Summary: >
  This creates a JSON list of all the unique indexes in the database. 
  This includes indexes in the database that have been explicitly 
  declared as well as those that have been automatically created 
  to enforce UNIQUE or PRIMARY KEY constraints
Author: Phil Factor
Date: 12/12/2019
Example:
   - DECLARE @OurListOfUniqueIndexes  NVARCHAR(MAX)
     EXECUTE #ListAllUniqueIndexes 
            @TheJsonList=@OurListOfUniqueIndexes OUTPUT
     SELECT @OurListOfUniqueIndexes AS theUniqueIndexes
   - DECLARE @OurListOfUniqueIndexes  NVARCHAR(MAX)
     EXECUTE #ListAllUniqueIndexes 
            @TheJsonList=@OurListOfUniqueIndexes OUTPUT
     SELECT * FROM OpenJson( @OurListOfUniqueIndexes) 
     WITH (columncount INT, indexname sysname, 
           thetable sysname, columnlist NVARCHAR(4000)
           ,delimitedlist nvarchar(4000))
Returns: >
  the JSON as an output variable
**/
@TheJSONList NVARCHAR(MAX) OUTPUT
AS 
SELECT @TheJSONList=
 (SELECT Count(*) AS columncount, IX.name AS indexname,
        QuoteName(Object_Schema_Name(IX.object_id)) + '.'
        + QuoteName(Object_Name(IX.object_id)) AS thetable,
        String_Agg(QuoteName(col.name), ',') AS columnlist,
        ''''+String_Agg(Replace(col.name,'''',''''''),''',''')+'''' 
               AS delimitedlist
        FROM sys.tables AS tabs
          INNER JOIN sys.indexes AS IX
            ON IX.object_id = tabs.object_id
          INNER JOIN sys.index_columns AS IC
            ON IC.index_id = IX.index_id AND IC.object_id = IX.object_id
          INNER JOIN sys.columns AS col
            ON col.column_id = IC.column_id 
            AND col.object_id = IC.object_id
        WHERE is_unique = 1 -- we only need the ones that 
        --force uniqueness we've chosen to test both the enabled 
        --ones and the disabled ones
        --AND Is_disabled=0
        GROUP BY IX.index_id, IX.object_id, IX.name FOR JSON AUTO)
GO
We can then execute it like this:
DECLARE @OurListOfUniqueIndexes NVARCHAR(MAX);
EXECUTE #ListAllUniqueIndexes 
       @TheJSONList = @OurListOfUniqueIndexes OUTPUT;
SELECT @OurListOfUniqueIndexes;

Note that we’ve chosen to comment out the line that delivers just the enabled constraints. It is a matter of choice, but if an index is there and disabled, I regard it with a certain suspicion.

This will produce a JSON report like this (I’ve just included a few rows):

[
 {
  "columncount": 1,
  "indexname": "PK_SalesTaxRate_SalesTaxRateID",
  "thetable": "[Sales].[SalesTaxRate]",
  "columnlist": "[SalesTaxRateID]",
  "delimitedlist": "'SalesTaxRateID'"
 },
 {
  "columncount": 2,
  "indexname": "AK_SalesTaxRate_StateProvinceID_TaxType",
  "thetable": "[Sales].[SalesTaxRate]",
  "columnlist": "[StateProvinceID],[TaxType]",
  "delimitedlist": "'StateProvinceID','TaxType'"
 },
 {
  "columncount": 1,
  "indexname": "AK_SalesTaxRate_rowguid",
  "thetable": "[Sales].[SalesTaxRate]",
  "columnlist": "[rowguid]",
  "delimitedlist": "'rowguid'"
 },
 {
  "columncount": 2,
  "indexname": "PK_PersonCreditCard_BusinessEntityID_CreditCardID",
  "thetable": "[Sales].[PersonCreditCard]",
  "columnlist": "[BusinessEntityID],[CreditCardID]",
  "delimitedlist": "'BusinessEntityID','CreditCardID'"
 },
 {
  "columncount": 3,
  "indexname": 
       "PK_PersonPhone_BusinessEntityID_PhoneNumber_PhoneNumberTypeID",
  "thetable": "[Person].[PersonPhone]",
  "columnlist": "[BusinessEntityID],[PhoneNumber],[PhoneNumberTypeID]",
  "delimitedlist": "'BusinessEntityID','PhoneNumber'
        ,'PhoneNumberTypeID'"
 }
]

This is one of the reports that I do routinely after a successful build and before data is loaded. This JSON file will usually become part of the build package during deployment. In a sense, it is part of the documentation of the database.

We need to check the data, and report on all the tables and their duplicate rows. We do this after it is loaded and before constraints are enabled. If we are doing a release by synchronizing with an existing version of the data, it is done by synchronizing with a version of the database that has its constraints disabled, and before a post-deployment script enables them.

We can, of course, generate the report and then use it immediately. We do this if we have built the database, ensured that constraints are disabled and then loaded the data.

Here is a batch that produces a JSON report. The batch not only checks for duplicates in the data but also checks that the table and columns mentioned in the constraint exist. If it can’t run the test because the columns aren’t there, then it reports the fact. It makes as few assumptions as possible.

Note that this script must be checked with your security team because actual data for the relevant columns of duplicate rows is stored in the resulting report. There is no way around this, but the risks of ‘leakage’ are low, and you get to be able to keep almost all sensitive data at arm’s length.

I’ve now got this all wrapped up in a temporary stored procedure TestAllUniqueIndexes.sql which is available on Github.

DECLARE @OurListOfUniqueIndexes NVARCHAR(MAX);
EXECUTE #ListAllUniqueIndexes 
        @TheJSONList = @OurListOfUniqueIndexes OUTPUT;
DECLARE @TheUniqueIndexes TABLE --the list of unique 
    --indexes in the database
  (
  TheOrder INT IDENTITY PRIMARY KEY,--needed to iterate 
         --through the table
  ColumnCount INT, --the number of columns used in the index
  IndexName sysname, --the name of the index
  TheTable sysname, --the quoted name of the table with the schema
  ColumnList NVARCHAR(4000), --the list of columns in the index
  DelimitedList NVARCHAR(4000) --the list of columns in the index
 );
INSERT INTO @TheUniqueIndexes (ColumnCount, IndexName, 
        TheTable, ColumnList, DelimitedList)
  SELECT * FROM OpenJson(@OurListOfUniqueIndexes)
  WITH
    (columncount INT, indexname sysname, 
     thetable sysname, columnlist NVARCHAR(4000)
     ,delimitedlist nvarchar(4000)
  );
DECLARE @Breakers TABLE (TheObject NVARCHAR(MAX));
DECLARE @Errors TABLE ([Description] NVARCHAR(MAX));
DECLARE @Duplicates NVARCHAR(MAX); ---list of duplicate rows 
DECLARE @ExecString NVARCHAR(MAX); --The string for that finds 
                                   --the duplicates
DECLARE @indexName sysname; --to hold the value when iterating 
                            --through the result
DECLARE @tablename sysname; --to hold the value when iterating 
                            --through the result
DECLARE @CheckExecString NVARCHAR(MAX); --The string for that 
                                        --checks the cols exist
DECLARE @columnList NVARCHAR(4000); --to hold the value when iterating 
                                    --through the result
DECLARE @columnDuplicates NVARCHAR(MAX);--the duplicate indexes
DECLARE @AllColumnsAndTableThere int
DECLARE @iiMax INT = @@RowCount;
DECLARE @ii INT = 1;
WHILE (@ii <= @iiMax)
  BEGIN
    SELECT @CheckExecString ='SELECT @AllColumnsThere =
  CASE WHEN '+Convert(varchar(3),ColumnCount)+' =
  (
  SELECT Count(*) FROM sys.columns AS c
    WHERE c.name IN ('+delimitedList+')
      AND Object_Id('''+TheTable+''') = c.object_id
  ) THEN 1 ELSE 0 END;
', @ExecString =
      N'SET @duplicates=(SELECT top 50 Count(*) AS duplicatecount, '
      + ColumnList + N' FROM ' + TheTable + N' GROUP BY ' + ColumnList
      + N' HAVING Count(*) >1 FOR JSON auto)', @indexName = IndexName,
      @tablename = TheTable, @columnList = ColumnList
      FROM @TheUniqueIndexes
      WHERE TheOrder = @ii;
    EXECUTE sp_executesql @CheckExecString, 
              N'@AllColumnsThere int output',
      @AllColumnsThere = @AllColumnsAndTableThere OUTPUT;
    if @AllColumnsAndTableThere=1
      BEGIN
      EXECUTE sp_executesql @ExecString, 
              N'@duplicates NVARCHAR(MAX) output',
        @duplicates = @columnDuplicates OUTPUT;
       IF @columnDuplicates IS NOT NULL
        INSERT INTO @Breakers (TheObject)
          SELECT
            (
            SELECT @indexName AS indexName, 
              @tablename AS tablename,
              @columnList AS columnlist, 
              Json_Query(@columnDuplicates) AS duplicates
            FOR JSON PATH, WITHOUT_ARRAY_WRAPPER
            );
      END
    ELSE
       INSERT INTO @errors(description) 
         SELECT 'Table' + @Tablename
                +'either didn''nt exist or didn''t have the column(s)' 
                +@columnlist+ 'so index '+@Indexname+' was untested'
    SELECT @ii = @ii + 1; --do the next unique index in the list
  END;
SELECT (SELECT Json_Query(TheObject) AS duplicated 
        FROM @Breakers FOR  JSON auto) AS duplicatelist,
       (SELECT description FROM @Errors FOR JSON auto) AS errors 
       FOR JSON path;

Testing it out: finding duplicate rows in AdventureWorks

Well, this is all pretty straightforward, but we need to be able to test it. We’ll take poor old AdventureWorks2016, which has some tables that are very handy for the purpose. The Sales.SalesTaxRate table has two unique indexes on top of its surrogate primary key. One of them, AK_SalesTaxRate_rowguid , ensures that the rowguid is unique: The other one, AK_SalesTaxRate_StateProvinceID_TaxType, ensures that there is only one tax rate for any Sales Tax rate, tax type and location. We can try introducing a duplicate:

--disable all constraints
ALTER TABLE Sales.SalesTaxRate NOCHECK CONSTRAINT ALL;
--disable the unique constraints that aren't used as a primary key
ALTER INDEX AK_SalesTaxRate_StateProvinceID_TaxType 
      ON Sales.SalesTaxRate DISABLE;
ALTER INDEX AK_SalesTaxRate_rowguid ON Sales.SalesTaxRate DISABLE;
--deliberately create a duplicate 
INSERT INTO Sales.SalesTaxRate (StateProvinceID, TaxType, TaxRate, 
      Name, rowguid, ModifiedDate)
  SELECT StateProvinceID, TaxType, TaxRate, Name, rowguid, ModifiedDate 
  FROM Sales.SalesTaxRate
  WHERE SalesTaxRateID = 1;

This works because we’ve deliberately disabled the checks before we introduced a duplicate. We can test this by enabling the indexes:

--enable the unique indexes
ALTER INDEX ALL ON Sales.SalesTaxRate REBUILD;
--at this point there is an error
/*
Msg 1505, Level 16, State 1
The CREATE UNIQUE INDEX statement terminated because a duplicate key 
was found for the object name 'Sales.SalesTaxRate' and the index name 
'AK_SalesTaxRate_StateProvinceID_TaxType'. 
The duplicate key value is (1, 1).
*/

So, we’ve now confirmed that this data will trigger an error in a build if we enable the unique constraints and indexes. We can now run the code to check all the tables in the database. Before we do this, however, here’s the code you can run after your tests to return AdventureWorks to its former state:

--we can do this to recover the table
DELETE FROM [Sales].[SalesTaxRate] WHERE SalesTaXrateID>29
--enable the unique indexes
ALTER INDEX ALL ON Sales.SalesTaxRate REBUILD;
--enable constraints
ALTER TABLE Sales.SalesTaxRate WITH CHECK CHECK CONSTRAINT ALL;

Running TestAllUniqueIndexes.sql produces a JSON report that tells us how to fix the problem.

[
  {
    "duplicatelist": [
      {
        "duplicated": {
          "indexName": "AK_SalesTaxRate_StateProvinceID_TaxType",
          "tablename": "[Sales].[SalesTaxRate]",
          "columnlist": "[StateProvinceID],[TaxType]",
          "duplicates": [
            {
              "duplicatecount": 2,
              "StateProvinceID": 1,
              "TaxType": 1
            }
          ]
        }
      },
      {
        "duplicated": {
          "indexName": "AK_SalesTaxRate_rowguid",
          "tablename": "[Sales].[SalesTaxRate]",
          "columnlist": "[rowguid]",
          "duplicates": [
            {
              "duplicatecount": 2,
              "rowguid": "683DE5DD-521A-47D4-A573-06A3CDB1BC5D"
            }
          ]
        }
      }
    ]
  }
]

This JSON report has two parts, the duplicate list and the errors. We can breathe a sigh of relief that there is no error list, which would mean that the database has changed enough that either columns or tables have changed their name. There are two duplications in the list, because two unique indexes have been compromised by the row we inserted. The report tells you what values were duplicates from the perspective of the unique constraint being checked

This information is intended to give the developer enough information to provide a script that corrects the data, but it will need to be tested on a database that has a good realistic generation of data so you can run tests that ensure that only the duplicate rows are affected by your corrections.

Automating the process

Because we’ve kicked into touch the problem of inputs and outputs from procedures by using JSON, we can simplify the process. I’ve designed a process that does as many setup and tear-down SQL files as you need, and which will do the following three essential processes:

  1. Check the new database after loading the data, but before the constraints and indexes are enabled. This runs a check that will tell you what you need to fix and put these into a report, for every database you specify on every server you specify. I realise that things start with just one database on one server but tend to escalate.
  2. Report on the constraints of a database. Check constraints, unique constraints and foreign key constraints are all reported on separately, in a file. The most important message was whether everything was OK, but all potential breaches of the proposed constraint are reported along with errors in the process
  3. Use the report on the constraints to run checks on the data in the specified database.

Logically speaking, processes 2 and 3 are components of process 1. However, you are not always lucky enough, as a developer, to be in charge of loading and checking the data all in one process. Having them as two different processes gives you more flexibility to fit in with the deployment regime.

What we’ve done is to design stored procedures for testing, or gathering data for, the various constraints. Because they all take JSON input and JSON output, we can radically simplify the PowerShell script we use to do the checks. We must keep with a common convention for alerting the user to the presence of rows that would trigger constraint errors if constraints were enabled, and we need a common way of advising if we can’t even run the test.

Because there are a lot of files and code, I’ve created a GitHub site with all the code in it here.

Summary

There are two points in any build, test or deployment where you can get into difficulties with your data because you have duplicates, bad data or data that has lost its relational integrity. Firstly, when you do a build, disable constraints temporarily and Load (BCP) in the data, and secondly, when you synchronize with a version of the database that does more checking of the data. If you have existing bad data, you need a way of fixing it. To do that, you need to know about the data that would fail the constraint tests that your constraints would use if they were enabled.

We need a slightly different ways of testing Check constraints (bad data checks), Unique Constraints (duplicate checks) and Foreign Key constraints (relational integrity checks). We can store the list of constraints from the source database as a JSON file, and we can take this list as a source and store the result of our tests in a JSON report file

To run all these tests in a flexible way that fits in with a wide range in methods of deployment, I’ve devised a general-purpose data-driven way of running these tests and reports in PowerShell.

In my final article I’ll describe how to check foreign key constraints


The post But the Database Worked in Development! Checking for Duplicates appeared first on Simple Talk.


from Simple Talk https://ift.tt/2upTWKE
via

Tuesday, February 4, 2020

Key Findings from the 2020 Database DevOps Survey

Each year Redgate Software runs a survey to learn more about how organizations practice DevOps, especially when it relates to the database. This year, over 2000 individuals responded, and they are from diverse industries and company sizes.

The key findings in the report are:

  • Frequent database deployments are increasing: 49% of respondents now report they deploy database changes to production weekly or more frequently.
  • Frequent deployers who use version control report lower production defect rates.
  • Respondents who report that it is easy to get a code review for database changes report lower production defect rates and lower lead time for change deployment.
  • Although 38% of responders report the use of Change Approval Boards, we see no evidence that Change Approval Boards lower code defect rates, only that they increase lead time for changes.
  • Respondents who reported that all or nearly all their database deployments take place with the system online also reported lower lead time for changes and lower defect rates.
  • 60% of Enterprise respondents believe the move from traditional database development to a fully automated process for deployment can be achieved in a year or less. 66% in non-Enterprises believe this can be accomplished.

As I read through the report, one thing stood out to me: organizations who deploy more frequently have lower defect rates. In fact, “37% of those who have adopted DevOps across all projects report that 1% or less of their deployments introduce code defects which require hotfixes, compared to 30% for all other groups.”

When there is a defect in software, it’s usually easy to rollback changes. Maybe services must be reconfigured, or files replaced. Deployment issues with databases are much more critical and difficult to resolve. Typically, you can’t just do a restore of production because of data loss, and the database will not be available during the restore.

Instead of massive changes every few weeks or months, small changes are deployed frequently with DevOps. Frequent database changes do sound intimidating, but because these are small changes, there is less of an impact on stability. And that reported decrease in defect rates from 30% to 1% is impressive!

Even if your company is not “all in” yet, there are things you can do. Make sure that you are using source control to keep track of database changes. Begin automating database deployments to dev and other non-production environments. Make an effort to communicate with other teams to break down those silos.

There’s a lot to learn from the report, and I hope you take a look and consider participating in next year’s survey.

Commentary Competition

Enjoyed the topic? Have a relevant anecdote? Disagree with the author? Leave your two cents on this post in the comments below, and our favourite response will win a $50 Amazon gift card. The competition closes two weeks from the date of publication, and the winner will be announced in the next Simple Talk newsletter.


The post Key Findings from the 2020 Database DevOps Survey appeared first on Simple Talk.


from Simple Talk https://ift.tt/393ZKb7
via

Monday, February 3, 2020

Text Mining and Sentiment Analysis: Introduction

Text Mining and Sentiment Analysis can provide interesting insights when used to analyze free form text like social media posts, customer reviews, feedback comments, and survey responses. Key phrases extracted from these text sources are useful to identify trends and popular topics and themes. Sentiment scores provide a way to perform quantitative analysis on text data. Combining these techniques, using visually engaging dashboards will help unlock the value of your text data.

This three-article series about Text Mining and Sentiment Analysis will start with exploring Azure Cognitive Services -Text Analytics APIs. In the second article, I’ll discuss various qualitative and quantitative techniques to analyze the data and create compelling visualizations in Power BI. The third and final article of this series will show how to use R to generate a Word Cloud, sentiment scores and NRC sentiment.

NOTE:These articles assume basic familiarity with Power BI and Azure.

Introduction

Have you looked at social media posts, customer reviews and feedback, survey responses to open-ended questions, or pretty much any free form text and wondered about analyzing that data? Maybe you have tried analyzing this type of data with R or Python and wondered if you are using the right lexicon or library for the task. Have you wondered about how to visualize the outcome of such analysis, create Dashboards and share it with relevant people in your company? You can use Power BI and Azure Cognitive services, to perform these tasks – no advance programming expertise or guru level of technical knowledge needed!

The Text Analytics API is a part of Azure Cognitive Services, a collection of machine learning and AI algorithms in the cloud. It provides advanced natural language processing of raw text, and includes four types of analysis:

Sentiment analysis returns a sentiment score between 0 and 1 for each set of text, where 1 is the most positive and 0 is the most negative score. It is useful to find out what customers think of your brand or topic by analyzing raw text for clues about positive or negative sentiment. The analysis models are pretrained using an extensive body of text and natural language technologies from Microsoft. For selected languages, the API can analyze and score any raw text that you provide, directly returning results to the calling application.

Key phrase extraction – extracts a list of important words and phrases, for each document and is used to identify the main points, themes, and topics in your text. For example, for the input text “I had a wonderful trip to Seattle for a conference”, the API returns the main talking points: “wonderful trip”, “Seattle” and “conference”.

Language detection – can recognize a wide range of languages, variants, dialects, and some regional/cultural languages. It detects the language of the input text and returns a single language code (paired with a score indicating the level of confidence) for every document submitted on the request

Named Entity recognition – identifies and categorized various entities in the input text as places, people, organizations, currencies, date/time, etc. Well-known entities are recognized and linked to more information on the web.

Each of these operations may work with different languages. While the services support English for all operations, you will find a full and updated list of languages supported for various Text Analytics operations here.

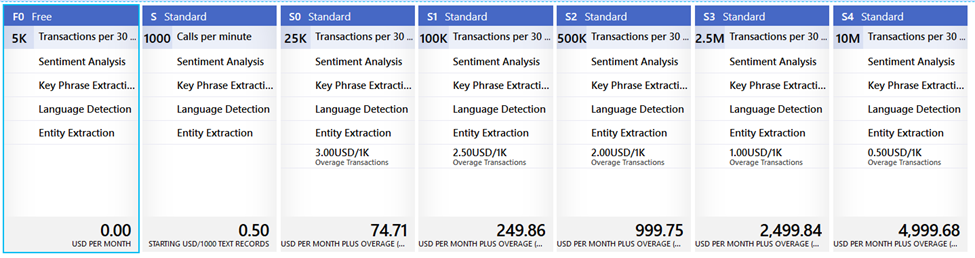
All Text Analytics API Endpoints (operations) accept raw text data, commonly referred to as a document. The current size limit for each document is 5,120 characters, so you must break down any larger documents into smaller chunks for analysis. The number of requests processed per second or minute (rate limit) depends on your pricing tier. These pricing tiers start from the F0 Free tier (which allows five thousand transactions per month at no cost), going up to the S4 Standard tier (which allows ten million transactions per month for about 5,000 USD and charges 0.50 USD per one thousand transactions over that limit).

A picture containing screenshot, wall Description automatically generated

Figure 1. Azure Text Analytics pricing tiers

Please note that your bill will depend on your actual usage, in addition to the selected pricing tier. You can find additional details about Cognitive Services pricing here and details about the data limits for each pricing tier here.

Text Analytics Containers (these are standard Docker containers) allow you to run the Text Analytic APIs in your own environment, to meet your specific security and data governance requirements. These containers will not send any customer data to Microsoft. Only billing information is sent to Azure, using a Text Analytics resource on your Azure account.

Key Phrases and Sentiment Scores

Key Phrases and Sentiment Scores allow performing both qualitative and quantitative analysis on this data. Qualitative data consists of text – words and narratives. Analysis of this data includes extraction of key phrases and counting word frequency, identifying themes and highlighting concepts. While qualitative data analysis can be time-consuming and somewhat subjective, it can help provide a nuanced understanding of the survey participants perspectives. Word Cloud is one of the most popular ways to visualize Key Phrase frequency analysis. The next article in the series will explore the Word Cloud in detail.

Numeric Sentiment Scores are quantitative data points, extracted from the text. Quantitative data is numeric, and the numbers are clear and specific. You can easily aggregate them, apply filters, make charts and graphs and apply statistical techniques to analyze them. You’ll learn how to create several charts using the sentiment scores in the next article of this series. A combination of qualitative and quantitative techniques is quite useful with a well-rounded analysis and visualization of text data coming from Surveys.

Several options are available for using the Text Analytics APIs;

  • Evaluate Azure Cognitive services for free, as a Guest with a 7 Day Trial
  • Use Azure Cognitive Services for non-production workloads, through your free Azure Account
  • Use Azure Cognitive Services for Production workloads, through your existing enterprise Azure account

You can always give it a try from your browser, using this link.

The following four easy steps will help you get set up for using the Text Analytics APIs to generate key Phrases and Sentiment Scores. The data from the Team Health Survey Results from a fictional company will be analyzed in this article

Step One – Set up an Azure Cognitive Services Resource

Assuming you have an Azure subscription/Account, set up Cognitive Services resource using the Azure Portal.

  1. Sign in to the Azure portal, click +Create a resource. Use the search bar to find text analytics.
  2. Select Text Analytics from the search results and hit the Create button.
  3. On the Create screen, enter the required details (please review the pricing details to choose a pricing tier that best fits your needs) and hit the Create button.
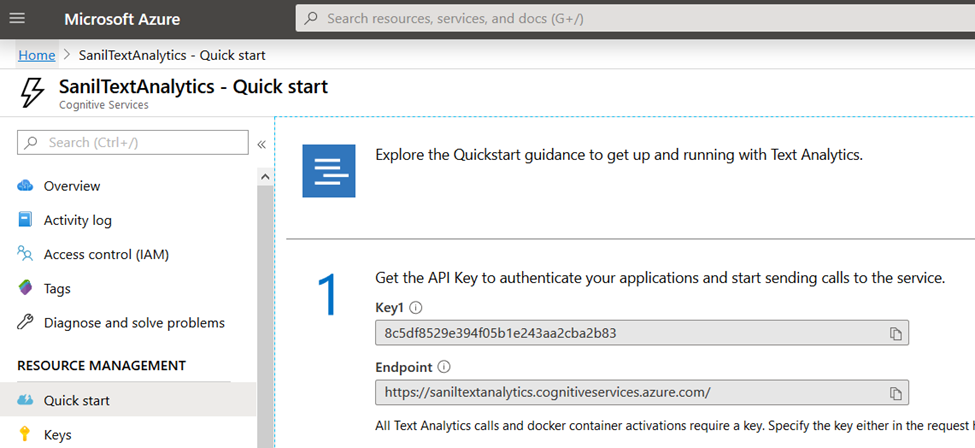
  4. Your deployment will begin and may take a few seconds to complete. Once it’s ready, click to open it and make a note of the Endpoint as well as the Access Keys. You will need them to Integrate Power BI with the Text Analytics Cognitive Service.

Please note that the subscriptions keys are used to access your Azure Cognitive service API and should be treated with the same precautions as you would take for your passwords. Store them securely and do not share them. Azure recommends regenerating these keys regularly for security (like changing your passwords at regular intervals).

A screenshot of a social media post Description automatically generated

Figure 2. Endpoint and Text Analytics API

Step Two – Loading Data into Power BI Desktop

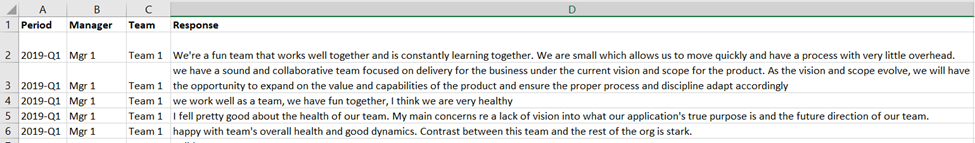
The Team Health Survey data is in an Excel spreadsheet and has four fields:

  • Period (Year & Quarter number)
  • Manager (Name)
  • Team (Name)
  • Response (the free form text responses from the Survey, to the question – How do you feel about your team’s health in this recent quarter)

Here’s a sample of the first few rows:

Figure 3. Raw data sample

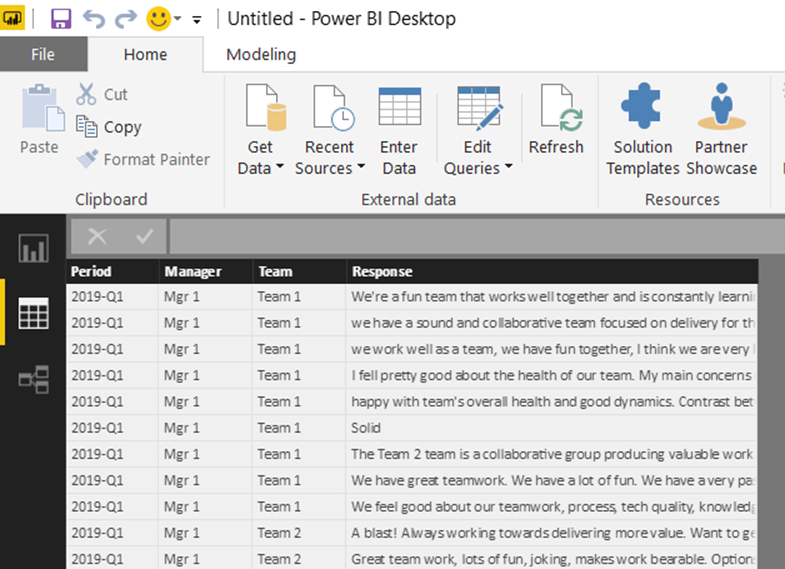
Launch Power BI Desktop and navigate to the Get Data menu to load the Excel spreadsheet. At this time, you can also perform transformations like changing data types, lengths, precisions, etc. Power BI gives you a preview, using a small sample of the data set. Once loading is complete, you can see the loaded data by clicking on the Data View button on the left edge of the Power BI workspace. If you would like to remove all the extraneous columns, select the four with data, right-click and choose Remove Other Columns.

Figure 4. The loaded data

Step Three – Creating Custom Functions in Power BI

In this scenario, no other data preparation/transformation is needed, so the next step is creating the custom functions that will integrate Power BI and Text Analytics. The function receives the text to be processed as a parameter. It converts data to and from the required JSON format and makes the HTTP request to the Text Analytics API. The function then parses the response from the API and returns a response. Power BI Desktop custom functions are written in the Power Query M formula language, “M” for short. You can learn more about it here.

The solution required two functions:

  1. Key Phrases – which returns a string that contains a comma-separated list of the extracted key phrases.
  2. Sentiment Score – which returns a numeric score ranging from 0 to 1.

In Power BI Desktop, open the Power Query Editor window by clicking Edit Queries on the Home ribbon. Then click New Source Blank Query found on the Home ribbon. A new query will appear in the list – rename it KeyPhrases.

Open the Advanced Editor found in the Query group of the Home ribbon and replace any existing text with the following code. Remember to use your own API Key and Endpoint.

// Returns key phrases from the text in a comma-separated list
(text) => let
    apikey      = "YOUR_API_KEY_HERE",
    endpoint    = "YOUR_ENDPOINT_HERE/text/analytics/v2.1/keyPhrases",
    jsontext    = Text.FromBinary(Json.FromValue(Text.Start(Text.Trim(text), 5000))),
    jsonbody    = "{ documents: [ { language: ""en"", id: ""0"", text: " & jsontext & " } ] }",
    bytesbody   = Text.ToBinary(jsonbody),
    headers     = [#"Ocp-Apim-Subscription-Key" = apikey],
    bytesresp   = Web.Contents(endpoint, [Headers=headers, Content=bytesbody]),
    jsonresp    = Json.Document(bytesresp),
    keyphrases  = Text.Lower(Text.Combine(jsonresp[documents]{0}[keyPhrases], ", "))
in  keyphrases

After saving the KeyPhrases function, follow the same steps and create a SentimentScore function, using the following code in the Advanced Editor window

// Returns the sentiment score of the text, from 0.0 (least favorable) to 1.0 (most favorable)
(text) => let
    apikey      = "YOUR_API_KEY_HERE",
    endpoint    = " YOUR_ENDPOINT_HERE/text/analytics/v2.1/sentiment",
    jsontext    = Text.FromBinary(Json.FromValue(Text.Start(Text.Trim(text), 5000))),
    jsonbody    = "{ documents: [ { language: ""en"", id: ""0"", text: " & jsontext & " } ] }",
    bytesbody   = Text.ToBinary(jsonbody),
    headers     = [#"Ocp-Apim-Subscription-Key" = apikey],
    bytesresp   = Web.Contents(endpoint, [Headers=headers, Content=bytesbody]),
    jsonresp    = Json.Document(bytesresp),
    sentiment   = jsonresp[documents]{0}[score]
in  sentiment

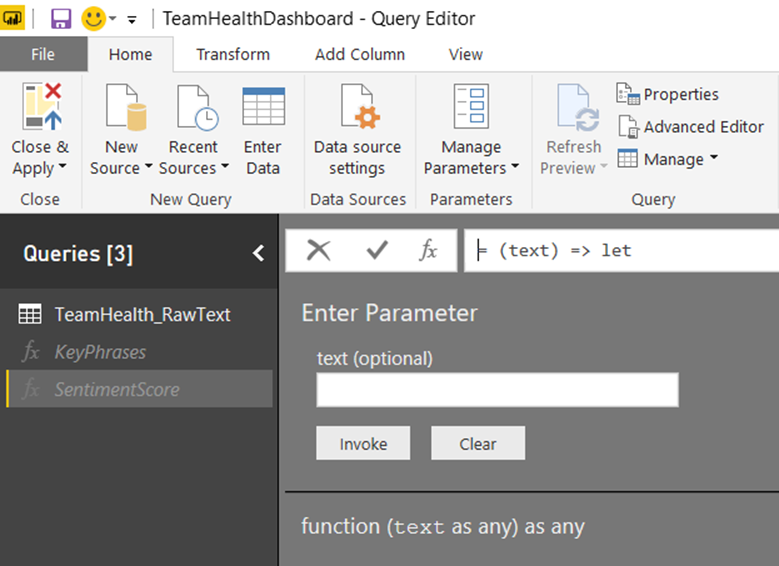
You should now see both custom functions, under Queries on the left-hand side.

Figure 5. Custom Functions in Query Editor Window

Step Four – Invoking the Newly Created Custom Functions

You can now use these custom functions to extract key Phrases and generate a Sentiment Score for each of the text responses and store them as new columns in the Table.

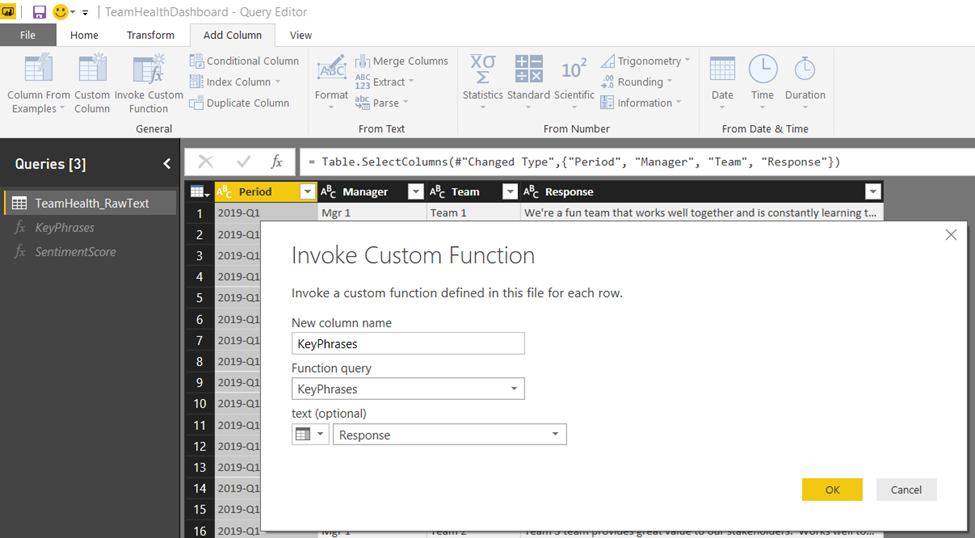
In Power BI Desktop Query Editor window, switch to the TeamHealth_RawText Query and select the Add Column ribbon, then click Invoke Custom Function. The Invoke Custom Function dialog appears. For New column name, enter KeyPhrases. For Function query, select the custom function you created, KeyPhrases. A new field appears in the dialog, text (optional), asking which column to provide as input values for the text parameter of the API. Select Responses from the drop-down menu and click OK.

Figure 6. Invoking the KeyPhrases custom function

After you close the Invoke Custom Function dialog, a banner may appear asking you to specify how to connect to the Key Phrases API. Click Edit Credentials, make sure Anonymous is selected in the dialog, then click Connect. Another banner may appear asking you to provide information about your data sources’ privacy. Click Continue and choose Public for each of the data sources in the dialog and Save. Now Repeat these Invoke Custom Function steps for loading another new column: SentimentScore.

You may want to limit the SentimentScore field to two decimal places. Right-click the column and choose Change Type Decimal Number. Then right-click the column and select Transform Round Round… Specify 2 decimal places.

After closing all the dialog boxes, go to the Home ribbon and click Close & Apply. Power BI will need a few minutes to process these queries.

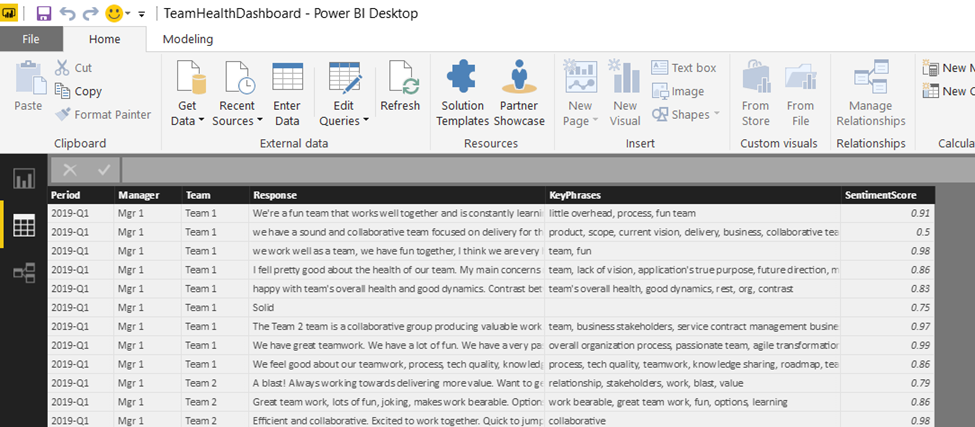
Once all the processing is complete, your Data View will now show the table has been updated with two new fields, that are loaded with KeyPhrases and SentimentScore for each Response text.

Figure 7. Power PI Data View with KeyPhrases and SentimentScore fields loaded

The data table now updated with KeyPhrases and Sentiment scores is ready for use in further analysis and create impactful visualizations in Power BI.

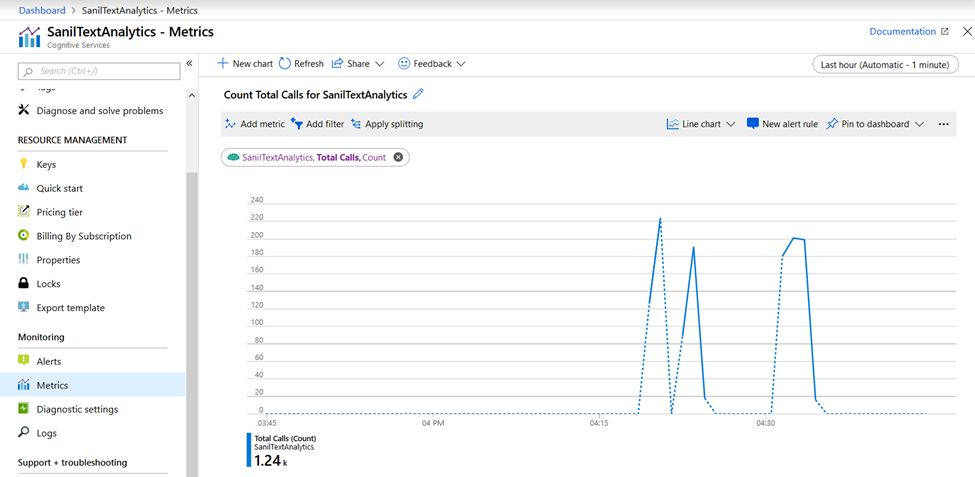
At this time, you can log into the Azure Portal and review the utilization metrics of your Text Analytics Service. You should see a spike in the chart for Total Calls, around the time Power BI was processing your data by invoking the Text Analytics API.

Figure 8. Azure Portal – Utilization Metrics for your Text Analytics Service

Conclusion

This article demonstrated how to do a sentiment analysis using Power BI and Azure Text Analytics. The next article of this three-part series looks at qualitative and quantitative analysis techniques for this data in Power BI. It demonstrates how to create a word cloud, and several statistical charts to help with analyzing this data, extract business value and use Power BI visualizations to narrate a meaningful story about this data.

References:

  • Qualitative or Quantitative Data – https://ift.tt/2GRqOOY
  • Quantitative Data Analysis – https://ift.tt/2UmXVSO
  • Azure Cognitive Services Text Analytics – https://ift.tt/2SdzcNT
  • Power BI Desktop – https://ift.tt/1T1D80M
  • Text Analytics with Power BI – https://ift.tt/2OppRkS


The post Text Mining and Sentiment Analysis: Introduction appeared first on Simple Talk.


from Simple Talk https://ift.tt/2UjXvMT
via

Saving Game Data with Unity

Back in the day, many games had little need for saving data since you could finish a game in about an hour. At best, a game would save a high score and leave it at that. But it didn’t take long for technology to improve, and thus games got longer and more complex. The need for saving all kinds of data, ranging from how much progress the player made in-game or their character’s statistics, became universal whether the game be a simple, linear adventure from beginning to end or it consists of a huge open world. Many games require multiple play sessions to see to the end, and it’s now expected that developers include ways to save the game and come back later. Only when a game is short enough that it can be completed in a single session does the need for saving data diminish, but even in those scenarios, the feature can be very handy.

Unity provides two ways to save a game’s data. They can be quickly described as “the easy way” and “the not so easy way.” The easy way involves Unity’s built-in PlayerPrefs system. Give a value to a key, call Save, and you’re done. On the other hand, the not so easy way involves serializing data and writing to a file for later use. Both methods have their pros and cons, which will be covered as the practices are explored.

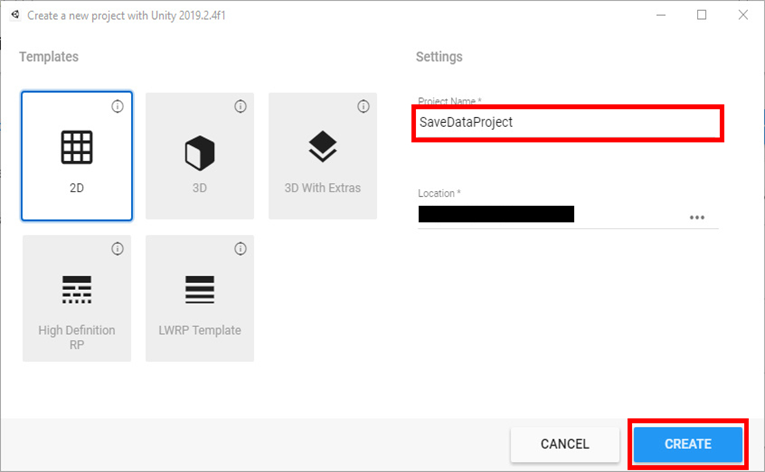
There’s minimal setup involved in testing these out. You just need a project and a couple of scripts. For this project, you will want to use the 2D template for the easiest setup as shown in Figure 1.

Figure 1: Project creation

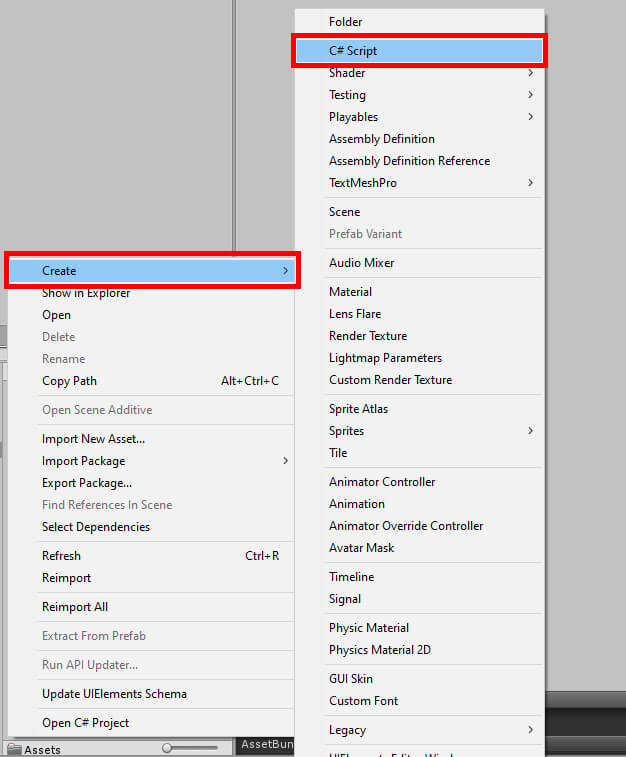
Once you create the project, you’ll need two scripts. You create scripts by right-clicking in the Assets window and selecting Create->C# Script as shown in Figure 2. Call these scripts SavePrefs and SaveSerial.

Figure 2: Script creation

To see what saving a game entails, start with the SavePrefs script. Double-click the script to open Visual Studio.

PlayerPrefs – The Easy Way

To begin, the Start and Update methods can be commented out or deleted as they will not be used to demonstrate the save functionality. Next, some variables to hold the values to save will be needed.

int intToSave;
float floatToSave;
string stringToSave = "";

Next, the OnGui method will create a Graphical User Interface (GUI) from code to manipulate these values. Two buttons created in the method will increase intToSave and floatToSave, and a text field will be made for stringToSave. The code will also create a few labels made to show the current values of these variables. Finally, three more buttons will be made that save, load, and reset data.

void OnGUI()
{
        if (GUI.Button(new Rect(0, 0, 125, 50), "Raise Integer"))
                intToSave++;
        if (GUI.Button(new Rect(0, 100, 125, 50), "Raise Float"))
                floatToSave += 0.1f;
        stringToSave = GUI.TextField(new Rect(0, 200, 125, 25), 
               stringToSave, 15);
        GUI.Label(new Rect(375, 0, 125, 50), "Integer value is " 
               + intToSave);
        GUI.Label(new Rect(375, 100, 125, 50), "Float value is " 
               + floatToSave.ToString("F1"));
        GUI.Label(new Rect(375, 200, 125, 50), "String value is " 
              + stringToSave);
        if (GUI.Button(new Rect(750, 0, 125, 50), "Save Your Game"))
                SaveGame();
        if (GUI.Button(new Rect(750, 100, 125, 50), 
                "Load Your Game"))
                LoadGame();
        if (GUI.Button(new Rect(750, 200, 125, 50), 
                "Reset Save Data"))
                ResetData();
}

The last three buttons all call methods whenever they are clicked, but those methods have not been defined yet. This will be fixed now, starting with the SaveGame method.

void SaveGame()
{
        PlayerPrefs.SetInt("SavedInteger", intToSave);
        PlayerPrefs.SetFloat("SavedFloat", floatToSave);
        PlayerPrefs.SetString("SavedString", stringToSave);
        PlayerPrefs.Save();
        Debug.Log("Game data saved!");
}

No, your eyes do not deceive you. The actual act of saving your game takes only a few lines of code. So, what’s happening? Well, as promised, PlayerPrefs saves the player’s game. First, you must set some variables for PlayerPrefs to save. As seen above, three variables were set, all of them given a name, or key, followed by the variable to save. Once PlayerPrefs is given all its information, Save is called and, as you may have guessed, saves the data. A message is also printed to Unity’s debug console as a little note to the developer saying the save was successful.

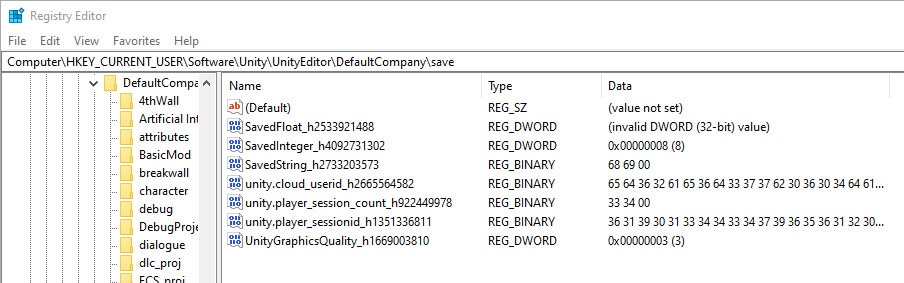
You may be wondering where this save data is on the computer. On Windows, PlayerPrefs can be found in the Registry under HKEY_CURRENT_USER\Software\Unity\UnityEditor\[company name]\[project name] (Figure 3), where company name and project name are names set up in the project settings. Bear in mind this is the location for when the game was run from the editor. In an exe they can be found at HKEY_CURRENT_USER\Software\[company name]\[project name]. On Mac OS, according to the Unity documentation, the PlayerPrefs is found at ~/Library/Preferences folder, in a file named unity.[company name].[product name].plist.

Figure 3: PlayerPrefs variables in the Windows Registry
Loading data is essentially saving data done in reverse. You set your variables of choice to whatever is in PlayerPrefs, and you’re good to go. A good practice is to make sure that the PlayerPrefs for your game has at least one of the keys you’re looking for. In other words, you’re checking that there’s any save data to be found. The code sample below uses HasKey to search for one of the keys declared in the SaveGame method, those keys being SavedInteger, SavedFloat, and SavedString. Looking for just one will be sufficient. So long as PlayerPrefs has one of those, it’s safe to assume it will have the remaining data. Otherwise, it will print an error to the Unity console.

void LoadGame()
{
        if (PlayerPrefs.HasKey("SavedInteger"))
        {
                intToSave = PlayerPrefs.GetInt("SavedInteger");
                floatToSave = PlayerPrefs.GetFloat("SavedFloat");
                stringToSave = PlayerPrefs.GetString("SavedString");
                Debug.Log("Game data loaded!");
        }
        else
                Debug.LogError("There is no save data!");
}

Finally, if you wish to remove the save data stored in PlayerPrefs, all you need to call is PlayerPrefs.DeleteAll and the work is complete. In the following method, DeleteAll is put to use along with resetting the variables and ending by printing a message to the debug console.

void ResetData()
{
        PlayerPrefs.DeleteAll();
        intToSave = 0;
        floatToSave = 0.0f;
        stringToSave = "";
        Debug.Log("Data reset complete");
}

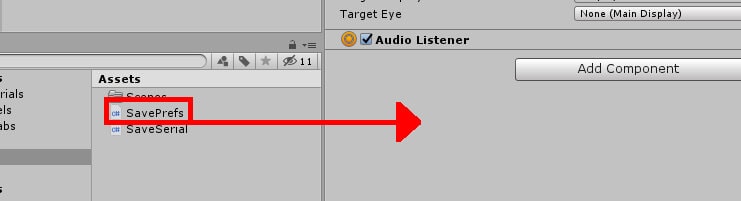
To try it out in-game, save your code and return to the Unity editor. Attach the SavePrefs script to an object, such as Main Camera as shown in Figure 4.

Figure 4: Attaching the SavePrefs script.
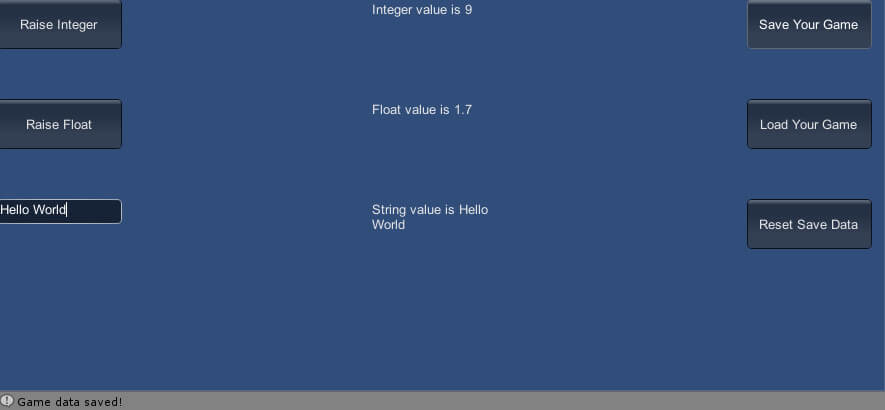
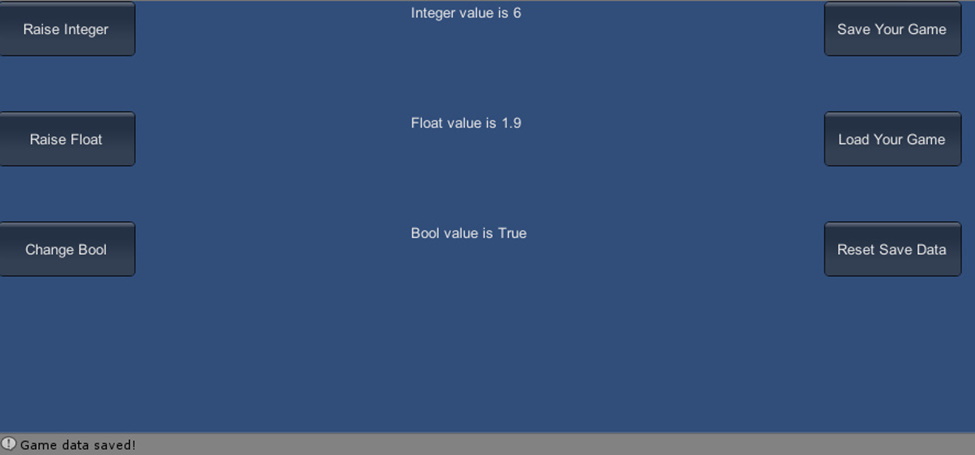
Begin playing the game and tinkering with the GUI on-screen, changing variables to whatever you wish. When ready, save your game. Then try stopping and replaying the game, this time clicking the Load Your Game button. Provided everything works correctly, you should see the variables immediately change to whatever was saved to PlayerPrefs. In addition, you can wipe PlayerPrefs clean by clicking the Reset Save Data button. Figure 5 shows the game in action.

Figure 5: The project in action, using PlayerPrefs
This method seems simple and effective, so why wouldn’t you use PlayerPrefs all the time? Well, PlayerPrefs is one of the least secure ways to save your data, and thus you wouldn’t want to save anything in PlayerPrefs that you absolutely do not want a potential player tampering with. This could be things like how much in-game currency the player currently possesses or stats in a role-playing game. As the name implies, best practices for PlayerPrefs is typically storing a player’s preferences and other trivial data. For example, if you’re letting the user customize the look and size of the game’s UI, PlayerPrefs would be an excellent way to store those preferences.

There’s also the issue of flexibility. The project’s SaveGame method saves an int, float, and string. These are all the data types you can save to PlayerPrefs, so if you wish to save variables of other types, you may be out of luck. Fortunately, there is the “not so easy way” of doing things that allows more flexibility in what you can save, not to mention a little extra security.

Serialization – The Not So Easy Way

Open up the SaveSerial script to begin trying out the next method. Much of the code will be the same as the last script with some minor differences to prove certain points. Here’s the variables and OnGUI method that will be used. All remaining methods will be different.

int intToSave;
float floatToSave;
bool boolToSave;
void OnGUI()
{
        if (GUI.Button(new Rect(0, 0, 125, 50), "Raise Integer"))
                intToSave++;
        if (GUI.Button(new Rect(0, 100, 125, 50), "Raise Float"))
                floatToSave += 0.1f;
        if (GUI.Button(new Rect(0, 200, 125, 50), "Change Bool"))
                boolToSave = boolToSave ? boolToSave 
                       = false : boolToSave = true;
        GUI.Label(new Rect(375, 0, 125, 50), "Integer value is " 
                + intToSave);
        GUI.Label(new Rect(375, 100, 125, 50), "Float value is " 
                + floatToSave.ToString("F1"));
        GUI.Label(new Rect(375, 200, 125, 50), "Bool value is " 
                + boolToSave);
        if (GUI.Button(new Rect(750, 0, 125, 50), "Save Your Game"))
                SaveGame();
        if (GUI.Button(new Rect(750, 100, 125, 50), 
                "Load Your Game"))
                LoadGame();
        if (GUI.Button(new Rect(750, 200, 125, 50), 
                "Reset Save Data"))
                ResetData();
}

To start, a few using statements will be needed to save data using serialization.

using System;
using System.Runtime.Serialization.Formatters.Binary;
using System.IO;

Next, in order to save data, a new class within this script will be created. This class will be made serializable and will consist of the data to be saved.

[Serializable]
class SaveData
{
    public int savedInt;
    public float savedFloat;
    public bool savedBool;
}

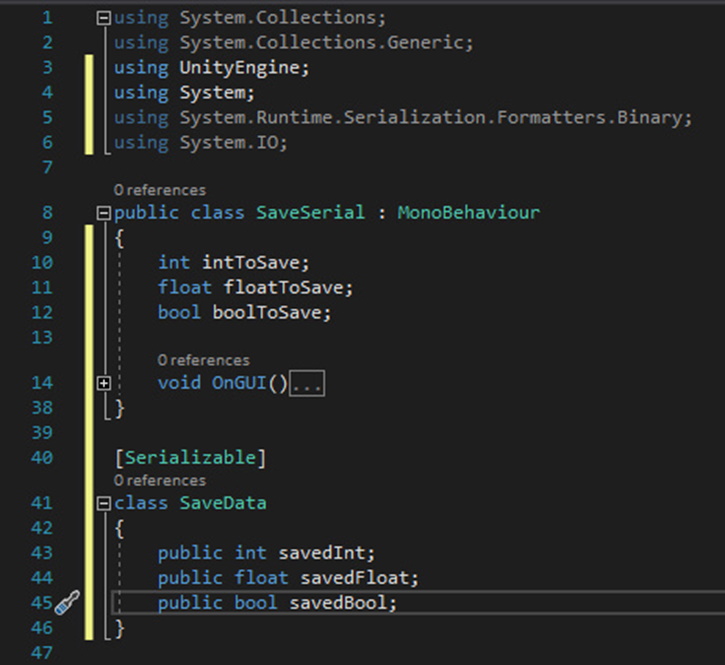
I’ve included a screenshot (Figure 6) here to make it easier to understand where this code will go:

Figure 6: SaveSerial script

The goal now is to create the remaining methods that will allow you to save, load, and reset save data. You might notice that the three variables in the SaveData class correspond with the three variables in SaveSerial. Saving data will work by passing SaveSerial's variable values into SaveData and then serializing the SaveData class itself. Returning to the SaveSerial class, create the following method under the OnGUI method.

void SaveGame()
{
        BinaryFormatter bf = new BinaryFormatter(); 
        FileStream file = File.Create(Application.persistentDataPath 
                 + "/MySaveData.dat"); 
        SaveData data = new SaveData();
        data.savedInt = intToSave;
        data.savedFloat = floatToSave;
        data.savedBool = boolToSave;
        bf.Serialize(file, data);
        file.Close();
        Debug.Log("Game data saved!");
}

The BinaryFormatter is used to perform the act of serialization and deserialization. When serializing the data, BinaryFormatter is responsible for converting the information to a stream of 1s and 0s. FileStream and File are used to create a save file with the dat extension under the application’s “persistent data path” followed by any remaining path you wish to make. The persistent data path is C:\Users\[user]\AppData\LocalLow\[company name].

A new instance of SaveData is created, and the variables within SaveData are given the variables in SaveSerial. The BinaryFormatter serializes that data to the file defined in the FileStream. The file is then closed, and a message is printed to the debug console saying the data was saved. Like before, the LoadGame method is very much the same but in reverse.

void LoadGame()
{
        if (File.Exists(Application.persistentDataPath 
                   + "/MySaveData.dat"))
        {
                BinaryFormatter bf = new BinaryFormatter();
                FileStream file = 
                   File.Open(Application.persistentDataPath 
                   + "/MySaveData.dat", FileMode.Open);
                SaveData data = (SaveData)bf.Deserialize(file);
                file.Close();
                intToSave = data.savedInt;
                floatToSave = data.savedFloat;
                boolToSave = data.savedBool;
                Debug.Log("Game data loaded!");
        }
        else
                Debug.LogError("There is no save data!");
}

Your save file by the name of MySaveData.dat is searched for in the same path given in the SaveGame method. Assuming it’s found, it will open the file and deserialize it using BinaryFormatter. Then the variables found in the save file will be fed into SaveSerial's variables. At the end, a message is printed to the debug console saying the load was performed successfully. If there is no file found at the file path, an error message will display instead.

Finally, there’s the act of deleting and resetting save data. This is extremely similar to the PlayerPrefs method but with a couple of extra steps. Unity will first check to make sure there’s a file at the save location before attempting any deleting of files. Assuming there is a file to delete, the variables in this script will also be reset to some default values and a message printed to the console. Like within the LoadGame method, an error message will be printed to the console if there is no file to be found.

void ResetData()
{
        if (File.Exists(Application.persistentDataPath 
                  + "/MySaveData.dat"))
        {
                File.Delete(Application.persistentDataPath 
                          + "/MySaveData.dat");
                intToSave = 0;
                floatToSave = 0.0f;
                boolToSave = false;
                Debug.Log("Data reset complete!");
        }
        else
                Debug.LogError("No save data to delete.");
}

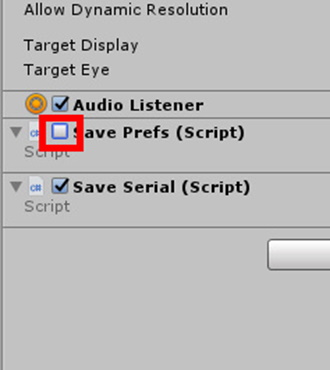
This concludes this script showcasing saving via serialization. Once again, save the code and go back to Unity. Attach SaveSerial to the same object as before and disable the SavePrefs script component.

Figure 7: Disabling the Save Prefs component.

When you run the game, the same UI from earlier appears with some alterations. Tinker with the variables like last time and try saving the game. This time a file is saved to the “persistent data path” of the game, which can be found at C:\Users\username\AppData\LocalLow\project name on Windows and ~/Library/Application Support/companyname/productname on Mac, according to the Unity documentation. Close and reopen the game, then click the load button to bring those values back into the game. And of course, you can delete the saved data entirely if you so desire.

Figure 8: The project in action, using serialization

Conclusion

Barring some very specific exceptions, such as games designed around short play sessions or “perma-death” (perma-death is a game mechanic where once the player loses the game they have to start completely over and everything resets), saving data will be crucial for user retention. Even in those aforementioned examples, most games will at least save a high score or an achievement. What data is saved and how you save that data is down to you and your project’s needs.

Though less secure and limited in what it can save, PlayerPrefs can be helpful for saving a player’s in-game preferences or for games where it doesn’t matter much if the user tinkers with the variables outside the game. In addition, it’s very simple to use which can help save some development time. Meanwhile, serializing data to a file is more complicated but in return, you can save many other types of data and have more security. Like many things in game development, the tools available to you can be utilized in a variety of ways. However, you choose to save your game’s data, there will be options available to you. In the end, the best method is the one that helps you and your project the most.


The post Saving Game Data with Unity appeared first on Simple Talk.


from Simple Talk https://ift.tt/2Ongmmp
via

Saturday, February 1, 2020

Copying of all data between SQL Server databases and servers

This script will copy out all the tables from one version of a database as native BCP format, and  place them in a directory of your choice, (defaulting to your user area in a  directory called BCPFiles). They are placed in sub directories based on your server name and database name, just to keep things neat. It will then if you wish, copy it out to a target server.  On first glance, this routine may seem over-complicated but it is designed to be able to perform this task for a list of these pairs of source & target databases for multi-database  applications if you feel bold. it will allow you to copy the files out just once, and then copy them out to a number of target databases on different servers subsequently. (you determine whether a source or target server is used simply by assigning a $null to $DataSource or $DataTarget when you don’t want the operation to happen).

The script then will transfer this data to an empty version of the same database (same meaning with the same table schema) with no data in it.  If the two versions have a different table structure you’ll get an error. If you use this system and you change the table structure, or constraints, you run your migration code on the source until it is the same as the target.

BCP needs to be installed to run this. This comes with SSMS so you probably have it already. Sometimes you need to create an alias for BCP but I think that problem has gone away

To get started, fill in the connection string for your source of data $datasource and $dataTarget. You also need to fill in an array of objects, each of which define your source and target databases, so you can do a whole list of databases. If you have to use credentials rather than integrated windows security, you add the userID but not the password. You will be asked the first  time you run the routine for your password and this is then stored as an encrypted string in a file in your user area protected by NTFS security. Be warned, though, that you shouldn’t allow anyone else to run this using  your PC, logged in with your credentials. If you don’t want to copy data out of the database into the directory, then set $datasource to $null. Likewise, If you don’t want to copy data in to the target , then set $datatarget to $null. 

This script uses SMO in order to get the list of tables from the database and command-line BCP to do the copying of the data. I’ve published other ways of doing this over the years.

$Filepath = "$env:USERPROFILE\BCPFiles" # local directory to save build-scripts to
$DataSource = @{ 'ConnectionString' = 'Server=MySourceServer;Persist Security Info=False' }; # server name and instance
$DataTarget = @{ 'ConnectionString' = 'Server=MyTargetServer;User Id=sa;Persist Security Info=False' }; # server name and instance

$FileSourceDirectory = 'MyServer'<#if you are reading files in only, the script
needs to know the subdirectory of your root directory to use to get the right files#>

if ($DataSource -eq $null -and $FileSourceDirectory -eq $null)
{ write-error 'the script needs to know the subdirectory of your root directory to use' break; }


$Databases = @(@{ 'source' = 'MyDatabase'; 'target' = 'MyNewDatabase' })
$slash = '+' #the string that you want to replace for the 'slash' in an instance name for files etc

# set "Option Explicit" to catch subtle errors
set-psdebug -strict
$ErrorActionPreference = "stop" # you can opt to stagger on, bleeding, if an error occurs
#load the sqlserver module
$popVerbosity = $VerbosePreference
$VerbosePreference = "Silentlycontinue"
# the import process can be very noisy if you are in verbose mode
Import-Module sqlserver -DisableNameChecking #load the SQLPS functionality
$VerbosePreference = $popVerbosity

if (!(Test-Path -path $Filepath -PathType Container))
{ $null = New-Item -ItemType directory -Path $Filepath }


@($DataSource, $DataTarget) | where { $_ -ne $null } | foreach {
        $csb = New-Object System.Data.Common.DbConnectionStringBuilder
        $csb.set_ConnectionString($_.ConnectionString)
        if ($csb.'user id' -ne '') #then it is using SQL Server Credentials
        { <# Oh dear, we need to get the password, if we don't already know it #>
                $SqlEncryptedPasswordFile = `
                "$env:USERPROFILE\$($csb.'user id')-$($csb.server.Replace('\', $slash)).xml"
                # test to see if we know about the password in a secure string stored in the user area
                if (Test-Path -path $SqlEncryptedPasswordFile -PathType leaf)
                {
                        #has already got this set for this login so fetch it
                        $SqlCredentials = Import-CliXml $SqlEncryptedPasswordFile
                        
                }
                else #then we have to ask the user for it (once only)
                {
                        #hasn't got this set for this login
                        $SqlCredentials = get-credential -Credential $csb.'user id'
                        $SqlCredentials | Export-CliXml -Path $SqlEncryptedPasswordFile
                }
                $_.ServerConnection =
                new-object `
                                   "Microsoft.SqlServer.Management.Common.ServerConnection"`
                ($csb.server, $SqlCredentials.UserName, $SqlCredentials.GetNetworkCredential().password)
                $csb.Add('password', $SqlCredentials.GetNetworkCredential().password)
        }
        else
        {
                $_.ServerConnection =
                new-object `
                                   "Microsoft.SqlServer.Management.Common.ServerConnection" `
                ($csb.server)
        }
        $_.csb = $csb
        try # now we make an SMO connection to the server, using the connection string
        {
                $_.srv = new-object ("Microsoft.SqlServer.Management.Smo.Server") $_.ServerConnection
        }
        catch
        {
                Write-error "Could not connect to SQL Server instance $($DataSource.csb.server) $($error[0]). Script is aborted"
                exit -1
        }
} <# all this work just to maintain passwords ! #>
if ($DataSource -ne $null)
{
        $DirectoryToSaveTo = $DataSource.csb.server.Replace('\', $slash)
        if ($DataSource.srv.Version -eq $null) { Throw "Can't find the instance $($DataSource.csb.server)" }
        Write-verbose "writing data out to $directoryToSaveTo"
        $DataSource.srv.Databases[$Databases.source].Tables | Select Name, Schema |
        foreach{
    <# calculate where it should be saved #>
                $directory = "$($FilePath)\$($DirectoryToSaveTo)\$($Databases.Source)\Data"
    <# check that the directory exists #>
                if (-not (Test-Path -PathType Container $directory))
                {
      <# we create the  directory if it doesn't already exist #>
                        $null = New-Item -ItemType Directory -Force -Path $directory;
                }
                $filename = "$($_.Schema)_$($_.Name)" -replace '[\\\/\:\.]', '-'
                Write-Verbose "Writing out $($_.Schema).$($_.Name) t0 $($directory)\$filename.bcp"
                If ($DataSource.csb.'user id' -eq '')<# OK. Easy, a trusted connection #>
                {
                        #native format -n, Trusted connection -T
                        $Progress = BCP "$($_.Schema).$($_.Name)"  out  "$($directory)\$filename.bcp"   `
                                                        -n -T "-d$($Databases.source)"  "-S$($DataSource.csb.server)"
                }
                else <# if not a trusted connection we need to provide a userid and password #>
                {
                        
                        $Progress = BCP "$($_.Schema).$($_.Name)"  out  "$($directory)\$($_.Schema)_$($_.Name).bcp"  `
                                                        -n "-d$($Databases.source)"  "-S$($DataSource.csb.server)"  `
                                                        "-U$($DataSource.csb.'user id')" "-P$($DataSource.csb.password)"
                }
                
                if (-not ($?) -or $Progress -like '*Error*') # if there was an error
                {
                        throw ("Error with data export of $($directory)\$($_.Schema)_$($_.Name).bcp - $Progress");
                }
        }
}
if ($DataTarget -ne $null)
{
        if ($DataSource -ne $null) { $DirectoryToLoadFrom = $DataSource.csb.server.Replace('\', $slash) }
        else { $DirectoryToLoadFrom = $FileSourceDirectory }
        if ($DataTarget.srv.Version -eq $null) { Throw "Can't find the instance $($DataTarget.csb.server)" }
        If ($DataTarget.srv.Databases[$Databases.target] -eq $null)
        { Throw "Can't find the database $($Databases.target) on instance $($DataTarget.csb.server)" }
        Write-verbose "Reading data in from $DirectoryToLoadFrom"
        
        $DataTarget.srv.Databases[$Databases.target].Tables | Select Name, Schema |
        foreach {
                # calculate where it gotten from #
                $directory = "$($FilePath)\$($DirectoryToLoadFrom)\$($Databases.Source)\Data"
                $filename = "$($_.Schema)_$($_.Name)" -replace '[\\\/\:\.]', '-'
                $progress = '';
                Write-Verbose "Reading in $($_.Schema).$($_.Name) from $($directory)\$filename.bcp"
                if ($DataTarget.csb.'user id' -ne '')
                {
                        $Progress = BCP "$($Databases.target).$($_.Schema).$($_.Name)" in "$($directory)\$filename.bcp" -q -N -E `
                                                        "-U$($DataTarget.csb.'user id')"  "-P$($DataTarget.csb.password)" "-S$($DataTarget.csb.server)"
                }
                else
                {
                        $Progress = BCP "$($Databases.target).$($_.Schema).$($_.Name)" in `
                                                        "$($directory)\$filename.bcp" -q -N -T -E `
                                                        "-S$($DataTarget.csb.server)"
                }
                if (-not ($?) -or $Progress -like '*Error*') # if there was an error
                {
                        throw ("Error with data import  of $($directory)\$($_.Schema)_$($_.Name).bcp - $Progress ");
                }
        }
        try # now we make an SMO connection to the server, using the connection string
        {
                $DataTarget.srv.ConnectionContext.ExecuteNonQuery(" use [$($Databases.target)]   EXEC sp_msforeachtable 'ALTER TABLE ? WITH CHECK CHECK CONSTRAINT all'")
        }
        catch
        {
                Write-error "there was a constraint error!  Script is aborted"
                exit -1
        }
}


The post Copying of all data between SQL Server databases and servers appeared first on Simple Talk.


from Simple Talk https://ift.tt/38UdCES
via