Wednesday, February 3, 2021

Deploying a NodeJS application from GitHub to AWS Elastic Beanstalk and creating a CI/CD AWS CodePipeline.

Goals

In this article I will assist you to deploy a NodeJS application from GitHub into AWS Elastic Beanstalk and Building a CI/CD pipeline.

What is Elastic Beanstalk ?

Using Elastic Beanstalk you will be able to deploy and manage applications within the AWS Cloud without having knowledge about the infrastructure that execute those applications. Elastic Beanstalk reduces management complexness without proscribing selection or control. You just transfer your application and Elastic Beanstalk mechanically handles the main points of capability provisioning, load equalization, scaling and application health observance.

Elastic Beanstalk support applications developed in java, Go, PHP, NodeJS, Python and Ruby. Once you deploy your application, Elastic Beanstalk build the chosen supported platform version and provisions one or additional AWS resources like AmazonEC2 instances, to run your application. Elastic Beanstalk has a default security group, this security group acts as a firewall for the instances.

Elastic Beanstalk console is used to interact with Elastic Beanstalk. You can also use AWS Command line interface or high-level designed interface.

Once you create and deploy application, information about your application can be available on Elastic Beanstalk console.

Why Elastic Beanstalk ?

AWS Elastic Beanstalk makes it easy for developers to share their application across different devices within less amount of time.

Pre-Requisities

We will need pre-built sample of NodeJS application , you can download using this URL from GitHub https://github.com/jspruance/musician-app. You should also have GitHub account and AWS account , you can create a free AWS account from https://aws.amazon.com/.

Click here, to Create AWS Account and enter AWS User name and Password and it will open AWS Management Console page. Click on All services and choose AWS Elastic Beanstalk.
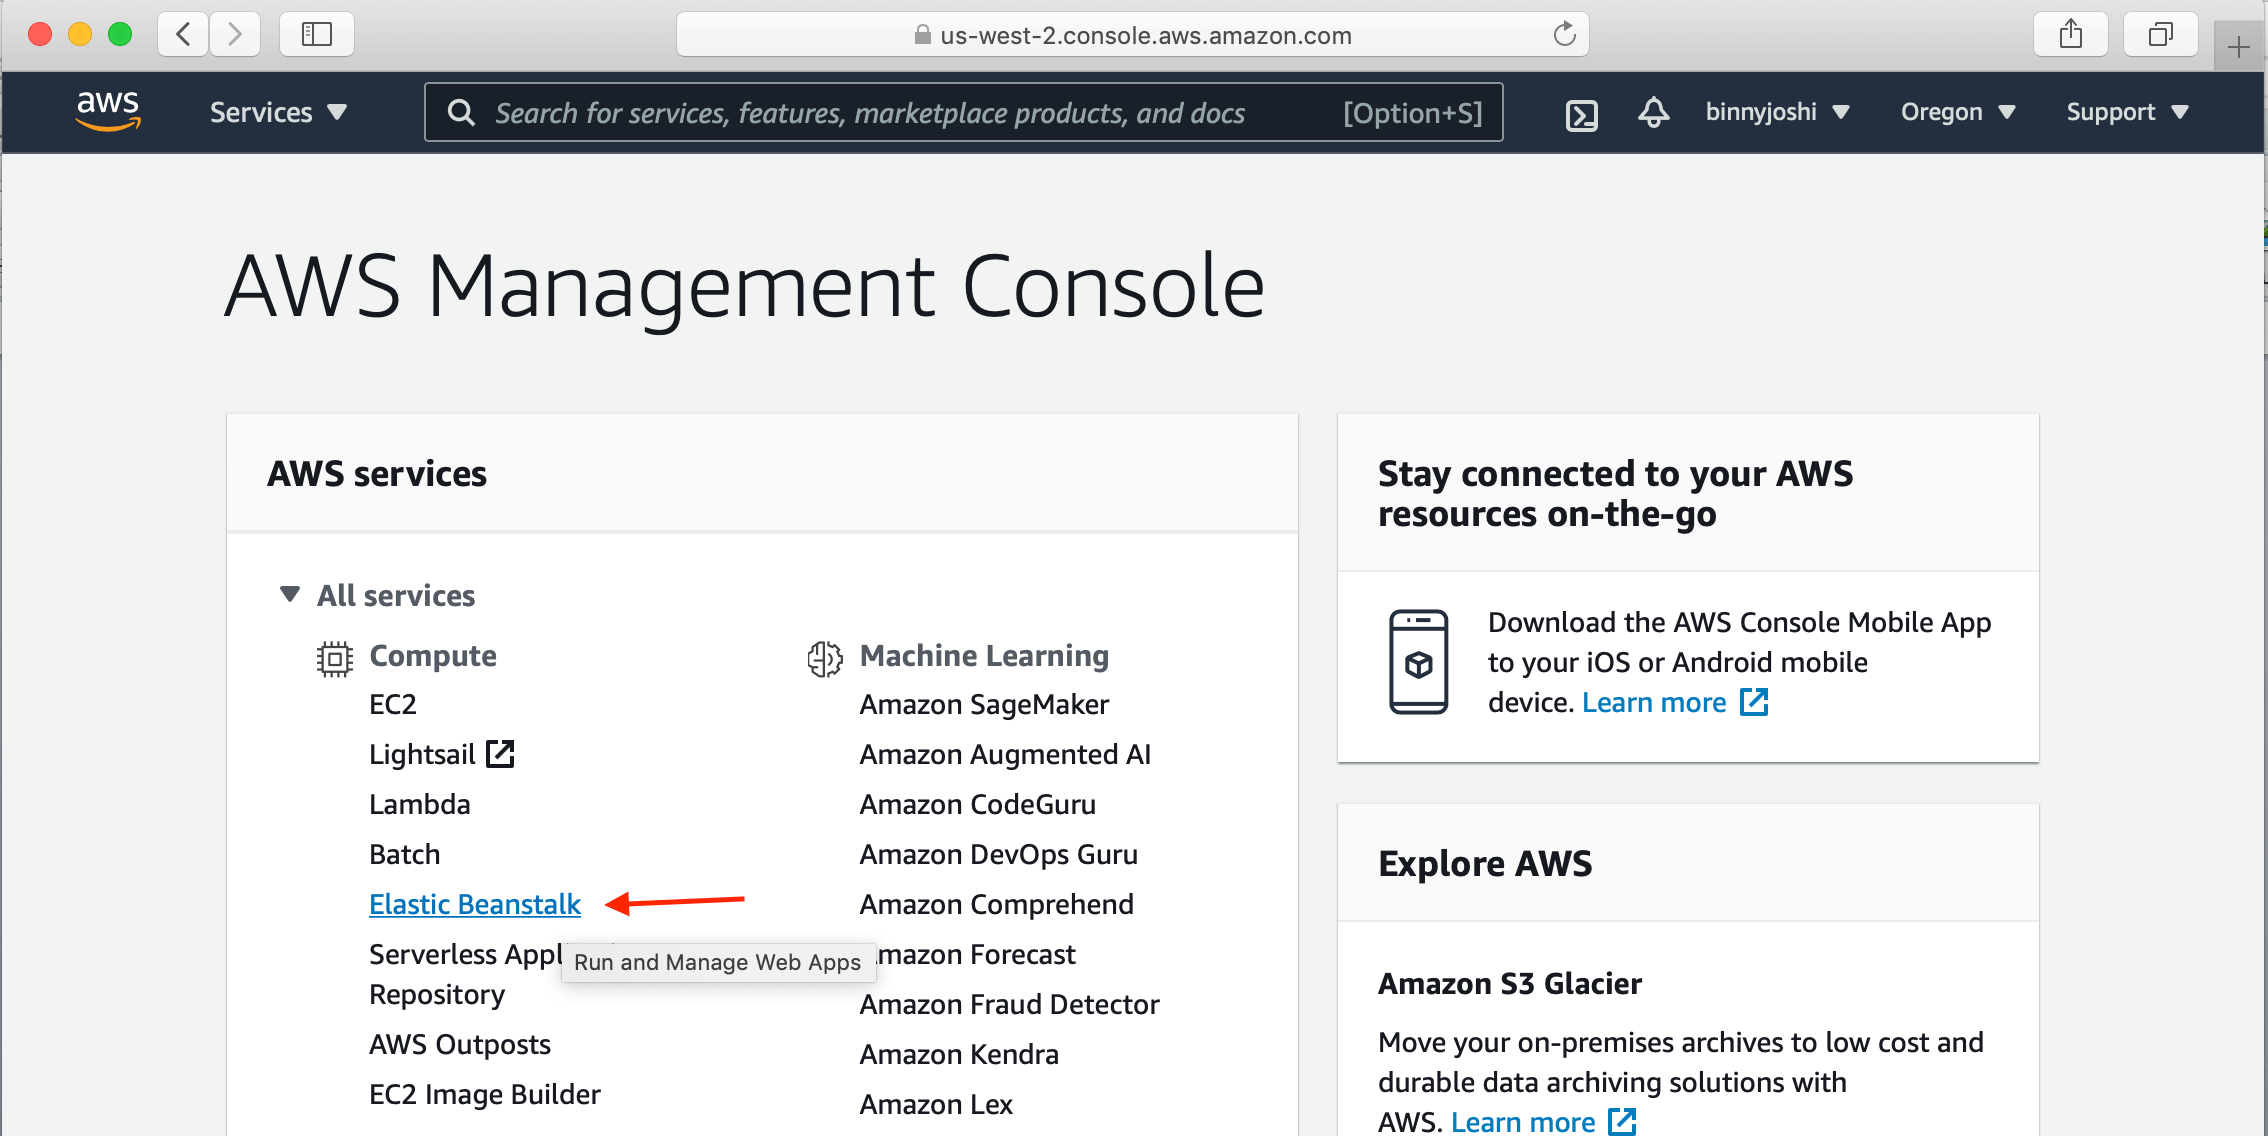
Figure 1: AWS Management console

When you click on Elastic Beanstalk , you will be directed to AWS Elastic Beanstalk Dashboard page and click “Create Application” button and configure your NodeJS application.
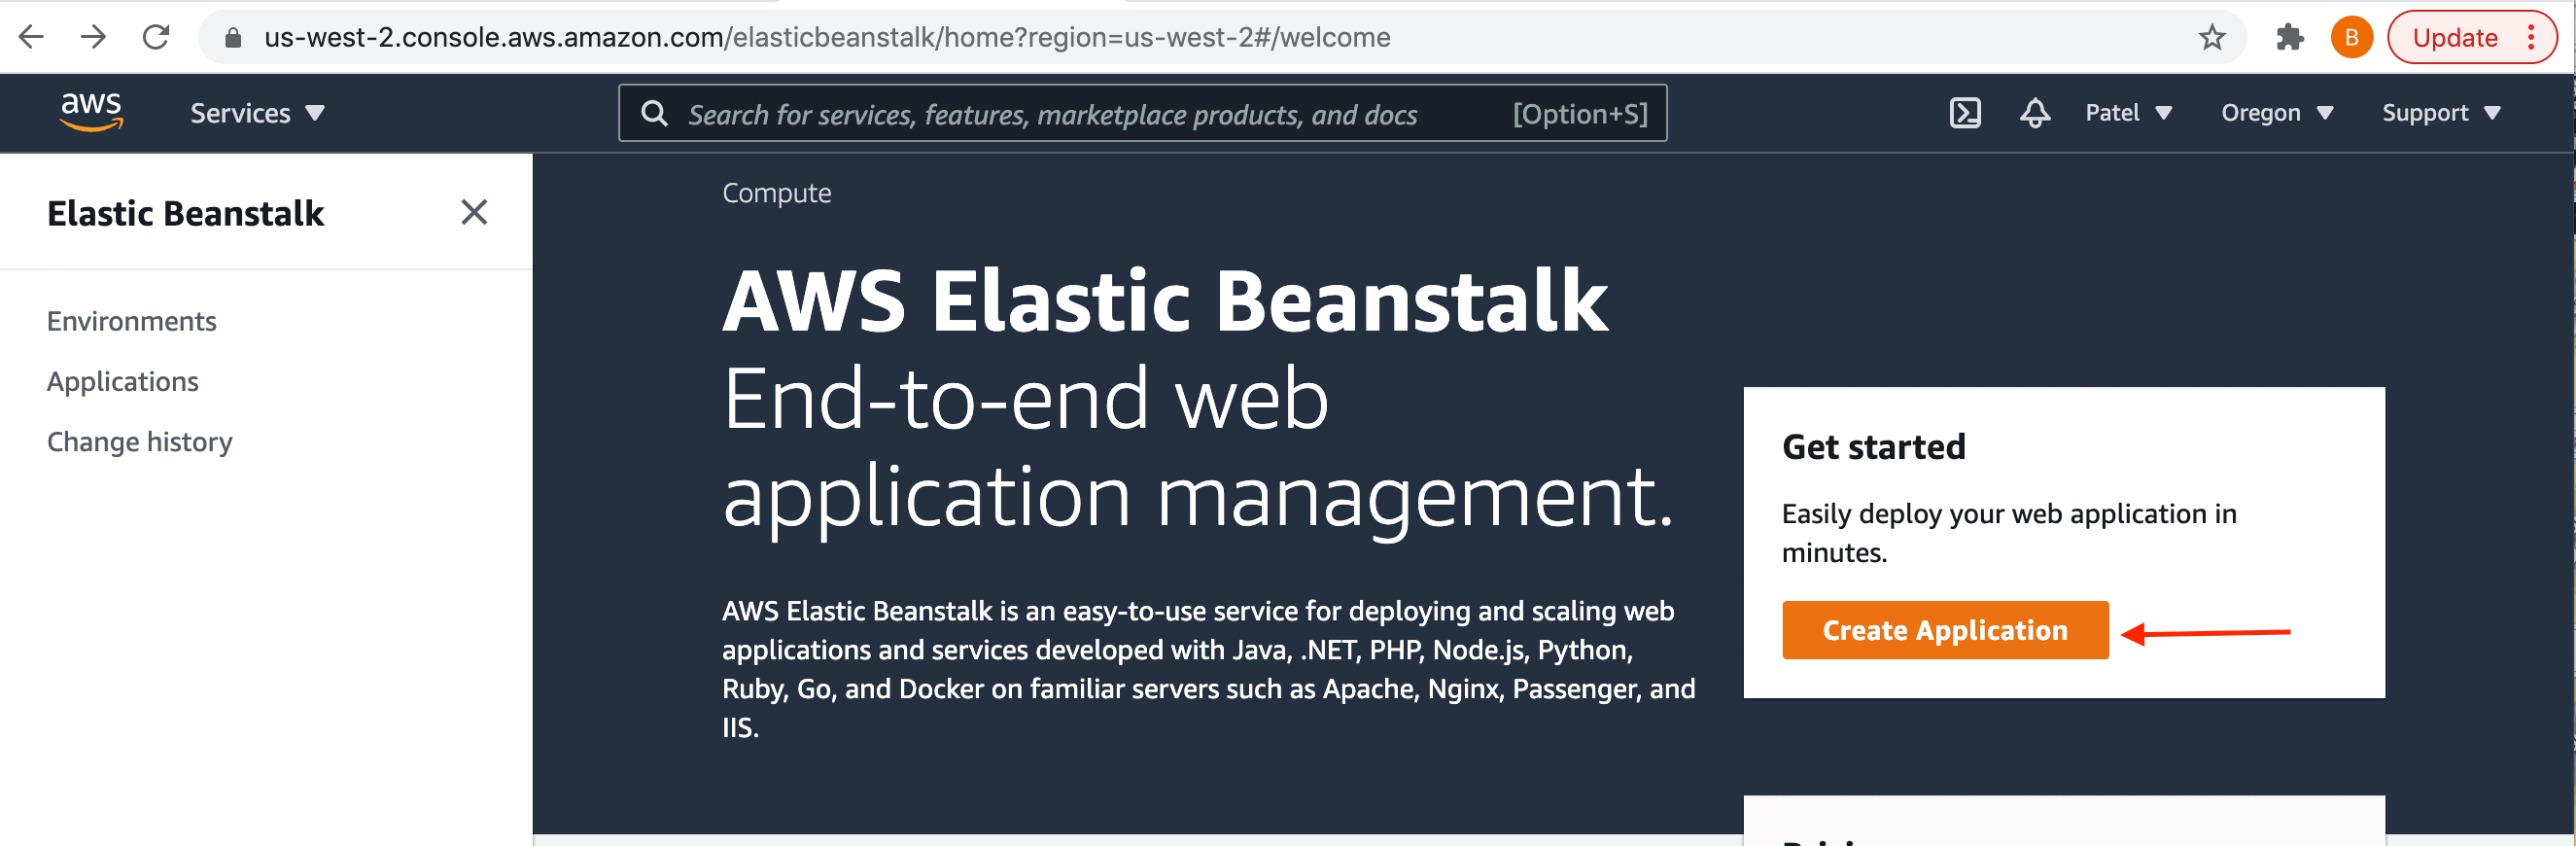
Figure 2: AWS Elastic Beanstalk Dashboard page

To create an Application

You can use “Create Web app” console wizard to create your sample application.

  1. Specify your Elastic Beanstalk application name information e.g: musician-sample
  2. Click on Platform drop-down and select your platform e.g: node.js. Platform branch and platform version will be auto populated.
  3. Select the Sample Application as application code and click on “Create Application “ button. It will take few minutes to launch your application.
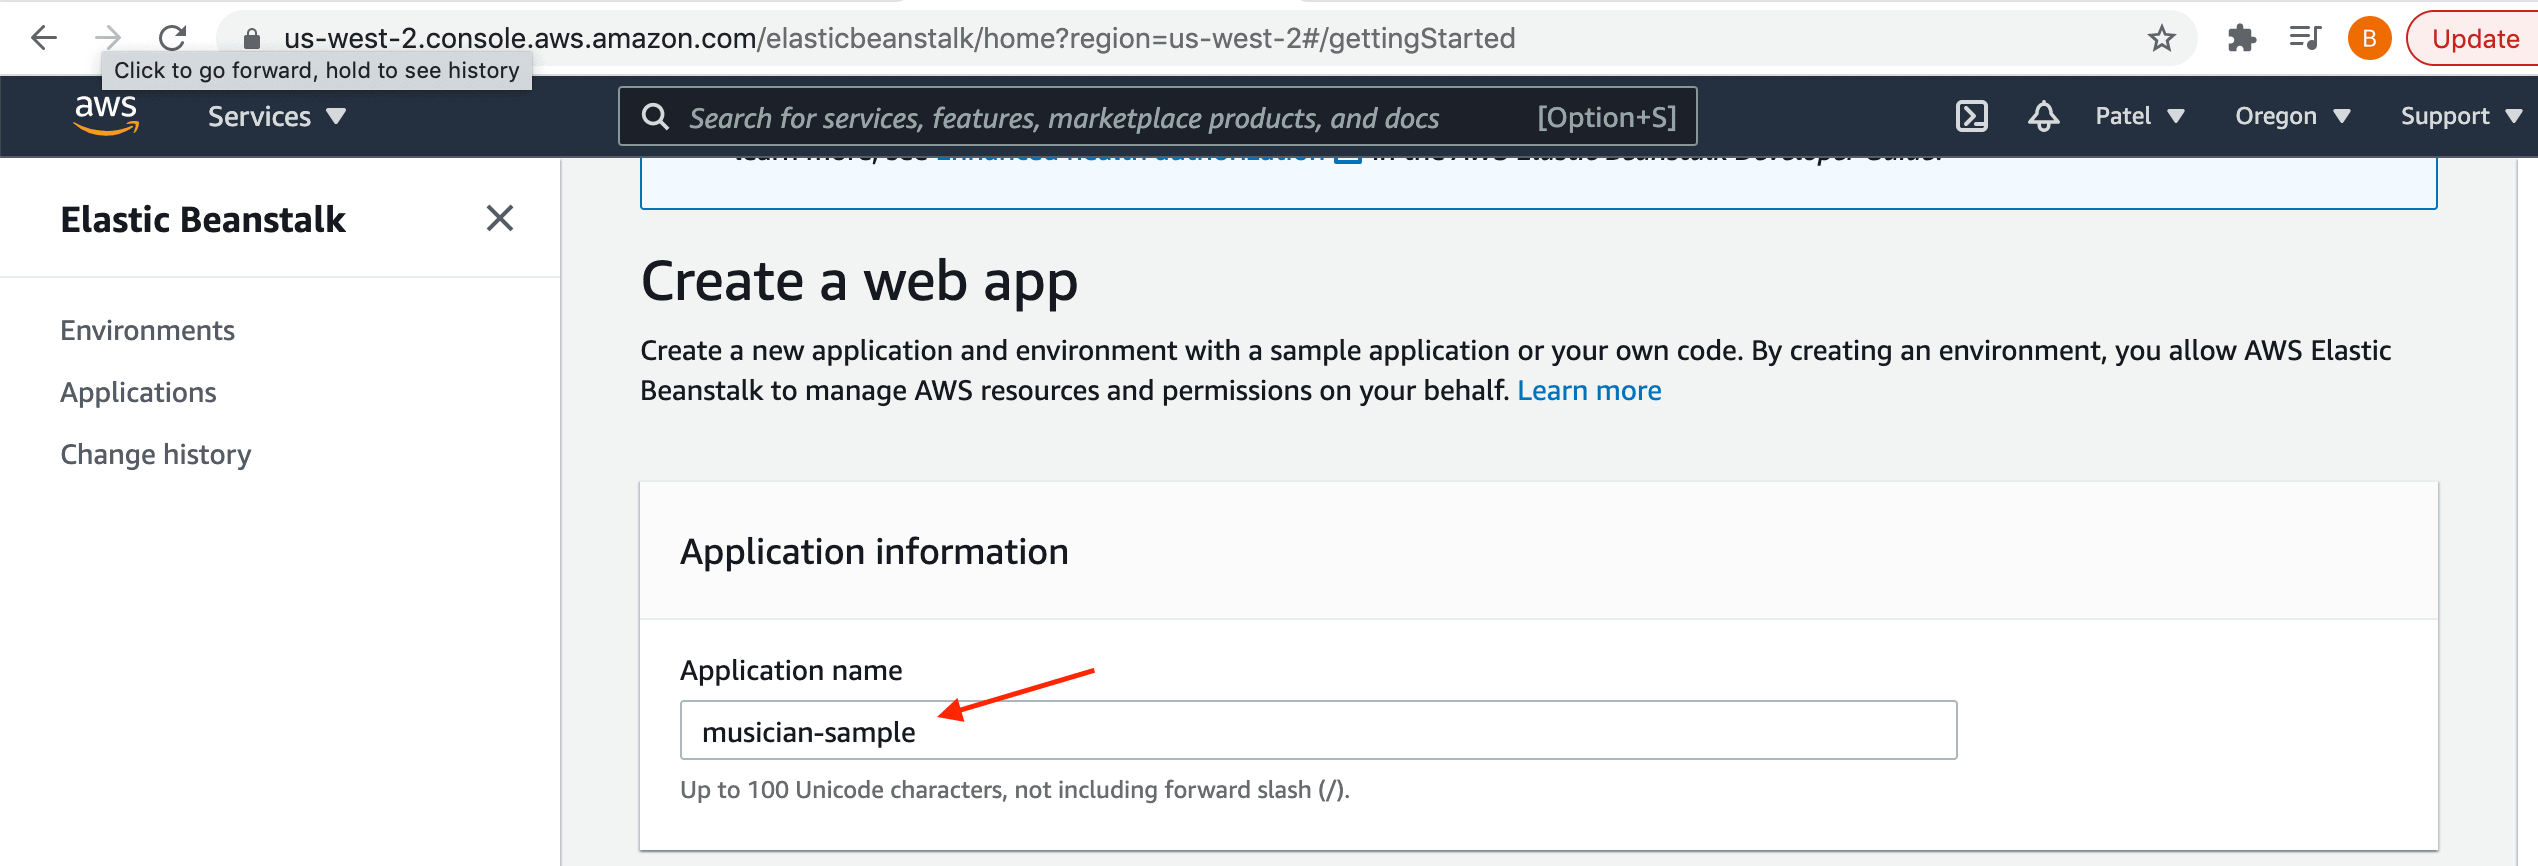
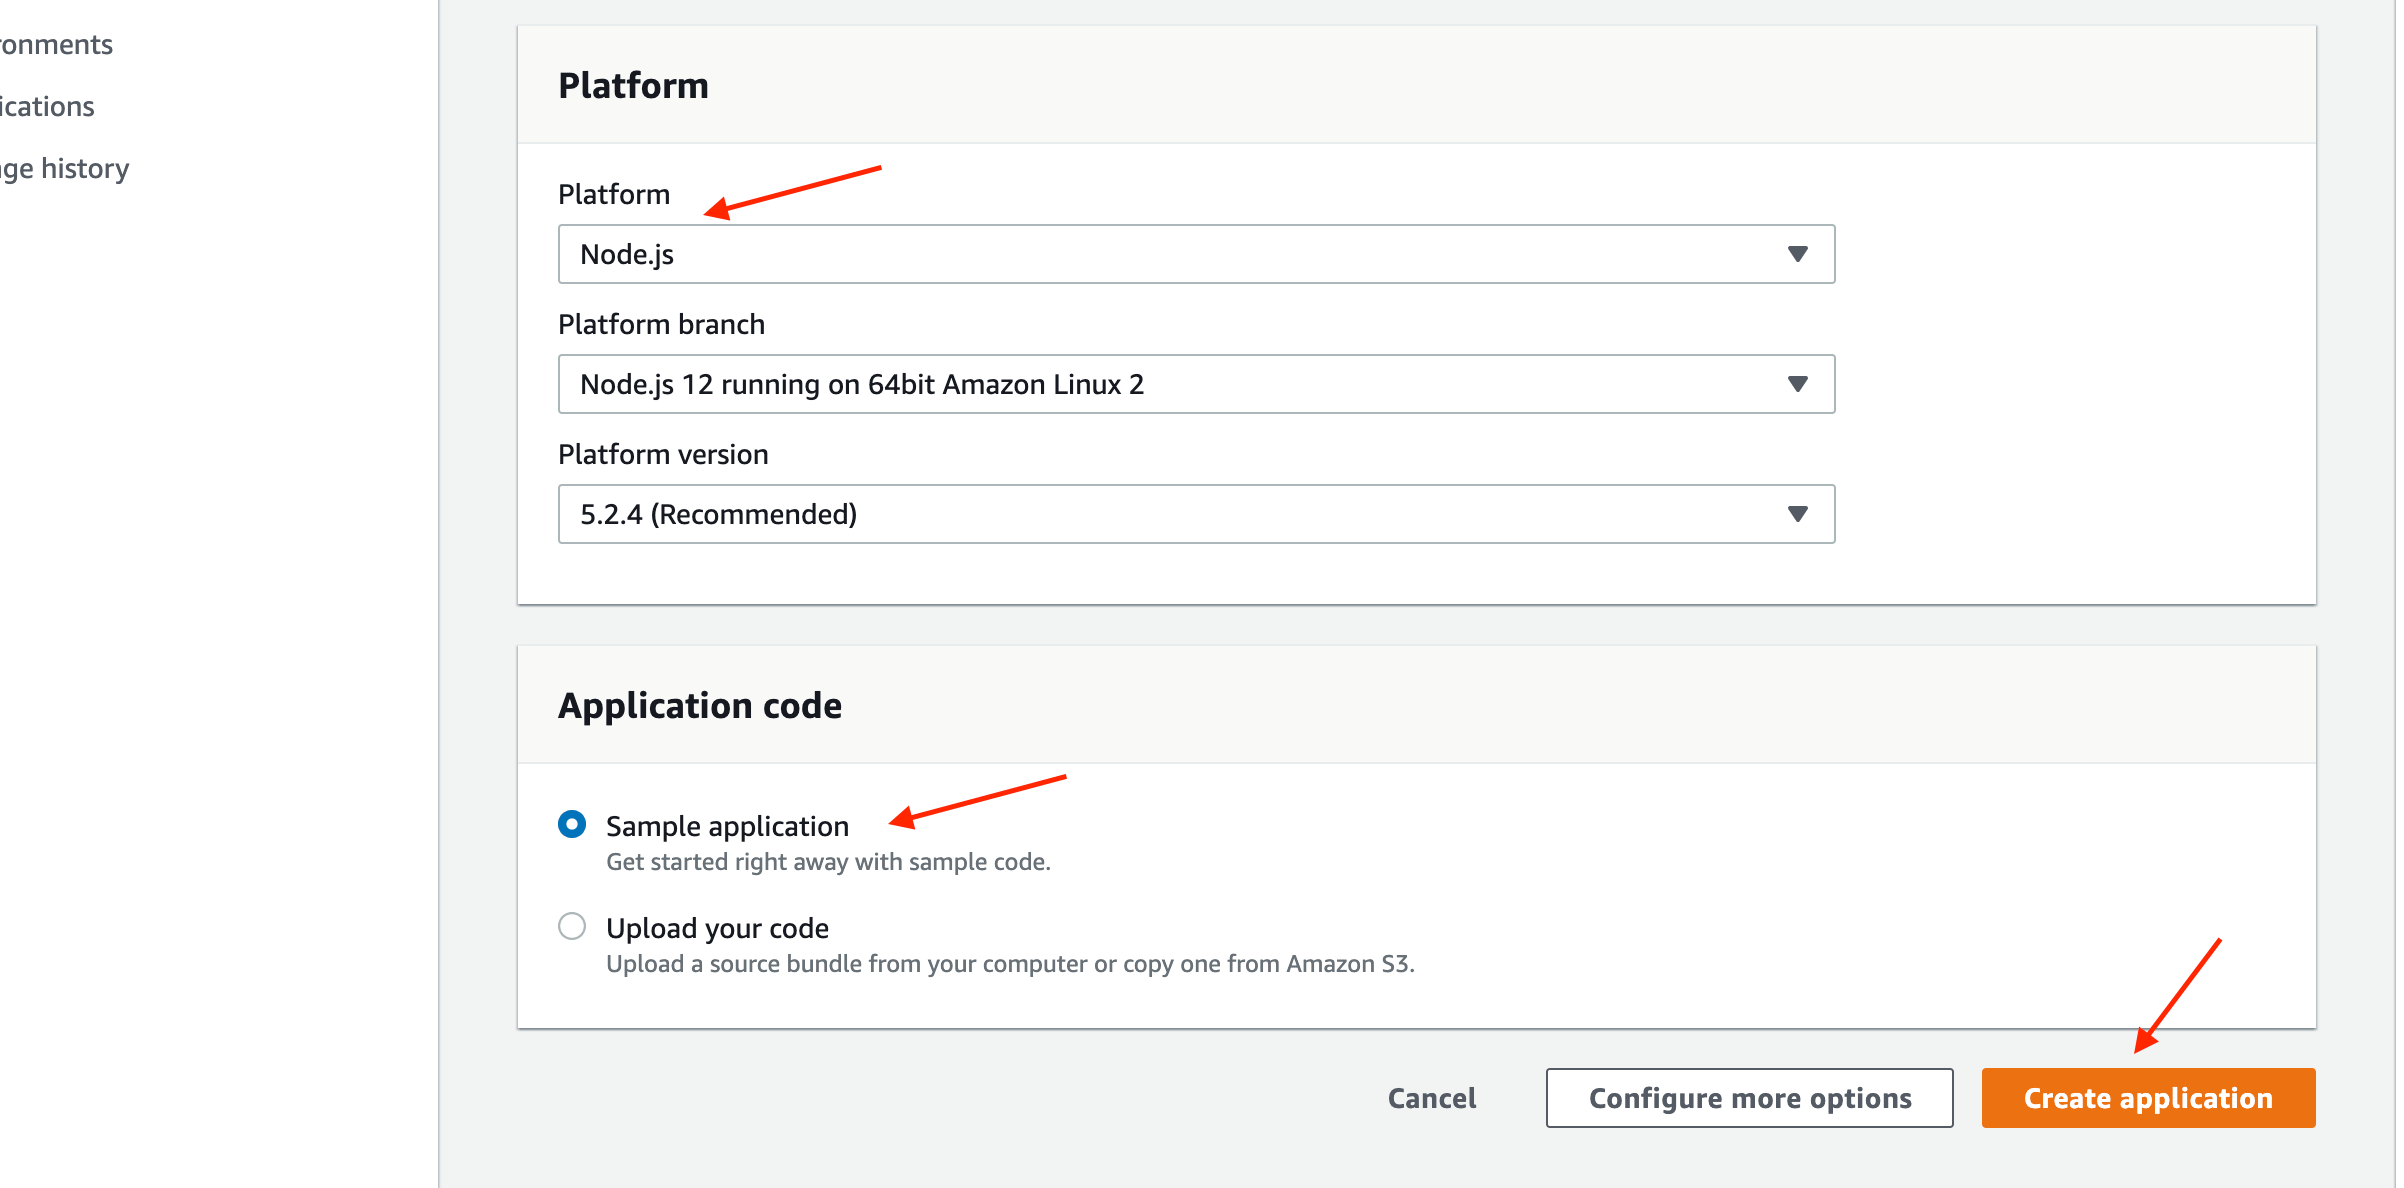
Figure 3: Creating a Web App Information page

This will deploy your application in specific environment and tracks the progress and display events.
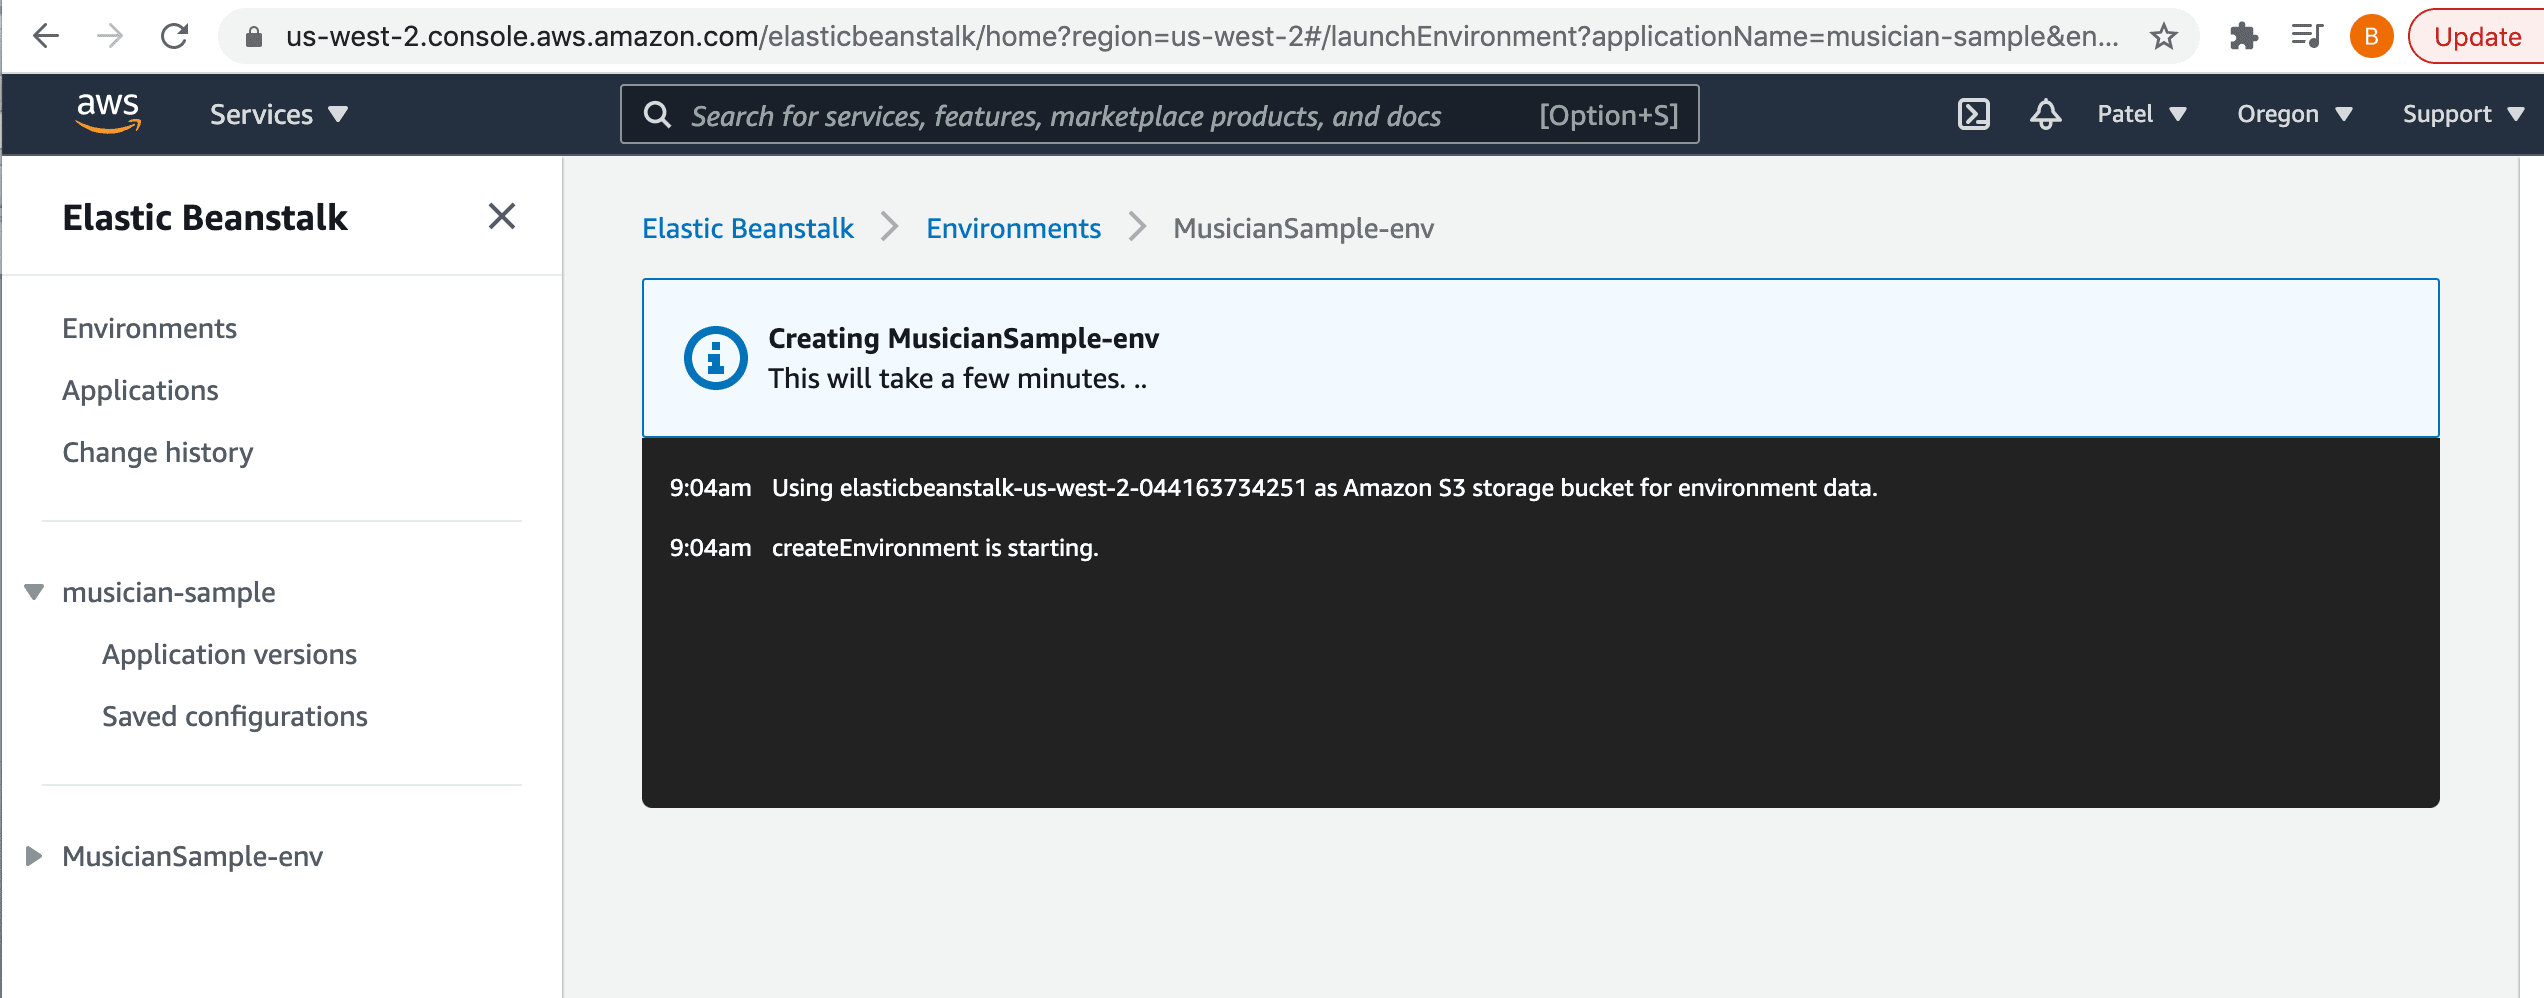
Once your Application is successfully launched , you will see Green check mark.

The environment Overview page will display high level of environment information such as Environment Health, Application running version and Application platform version where application is running on.
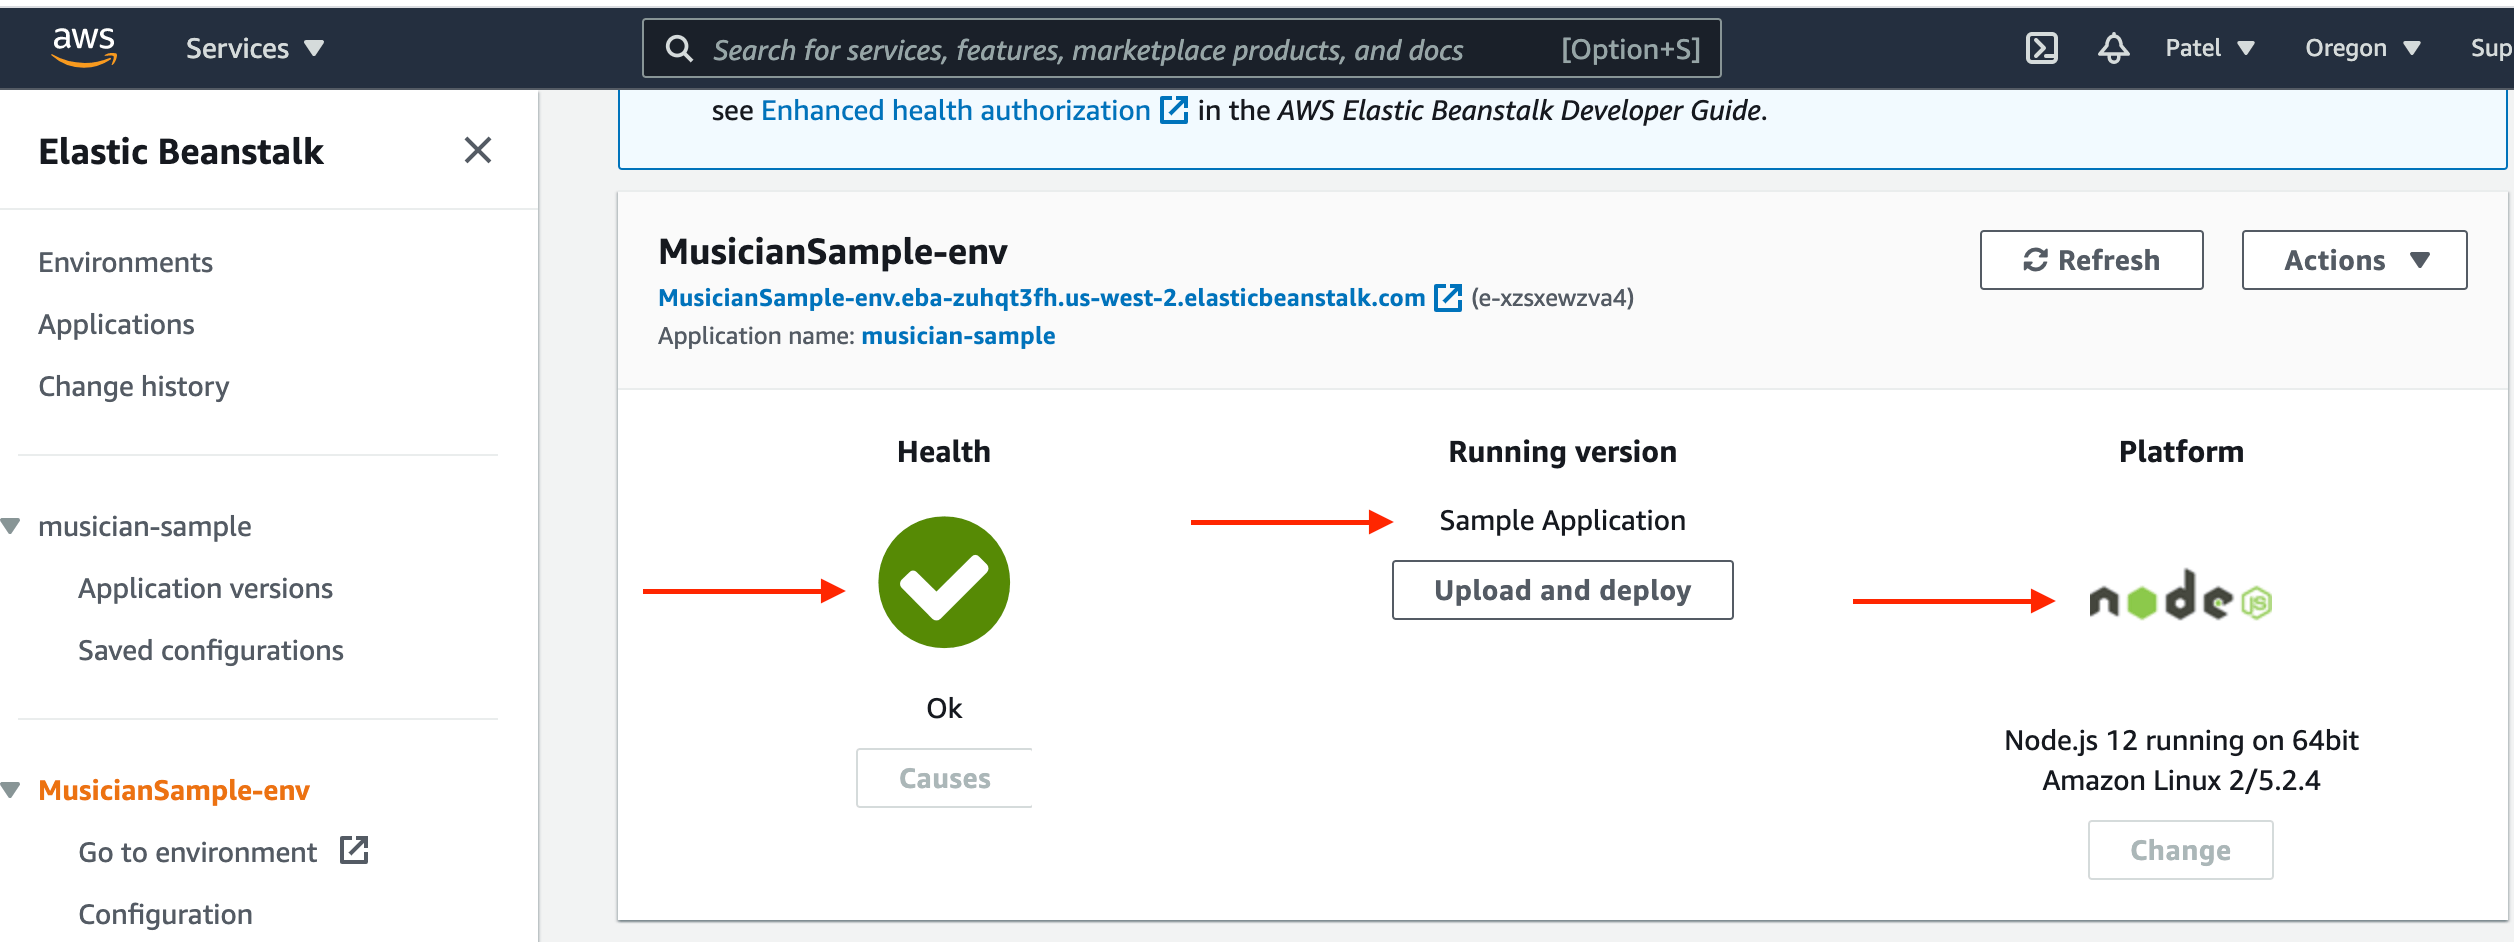
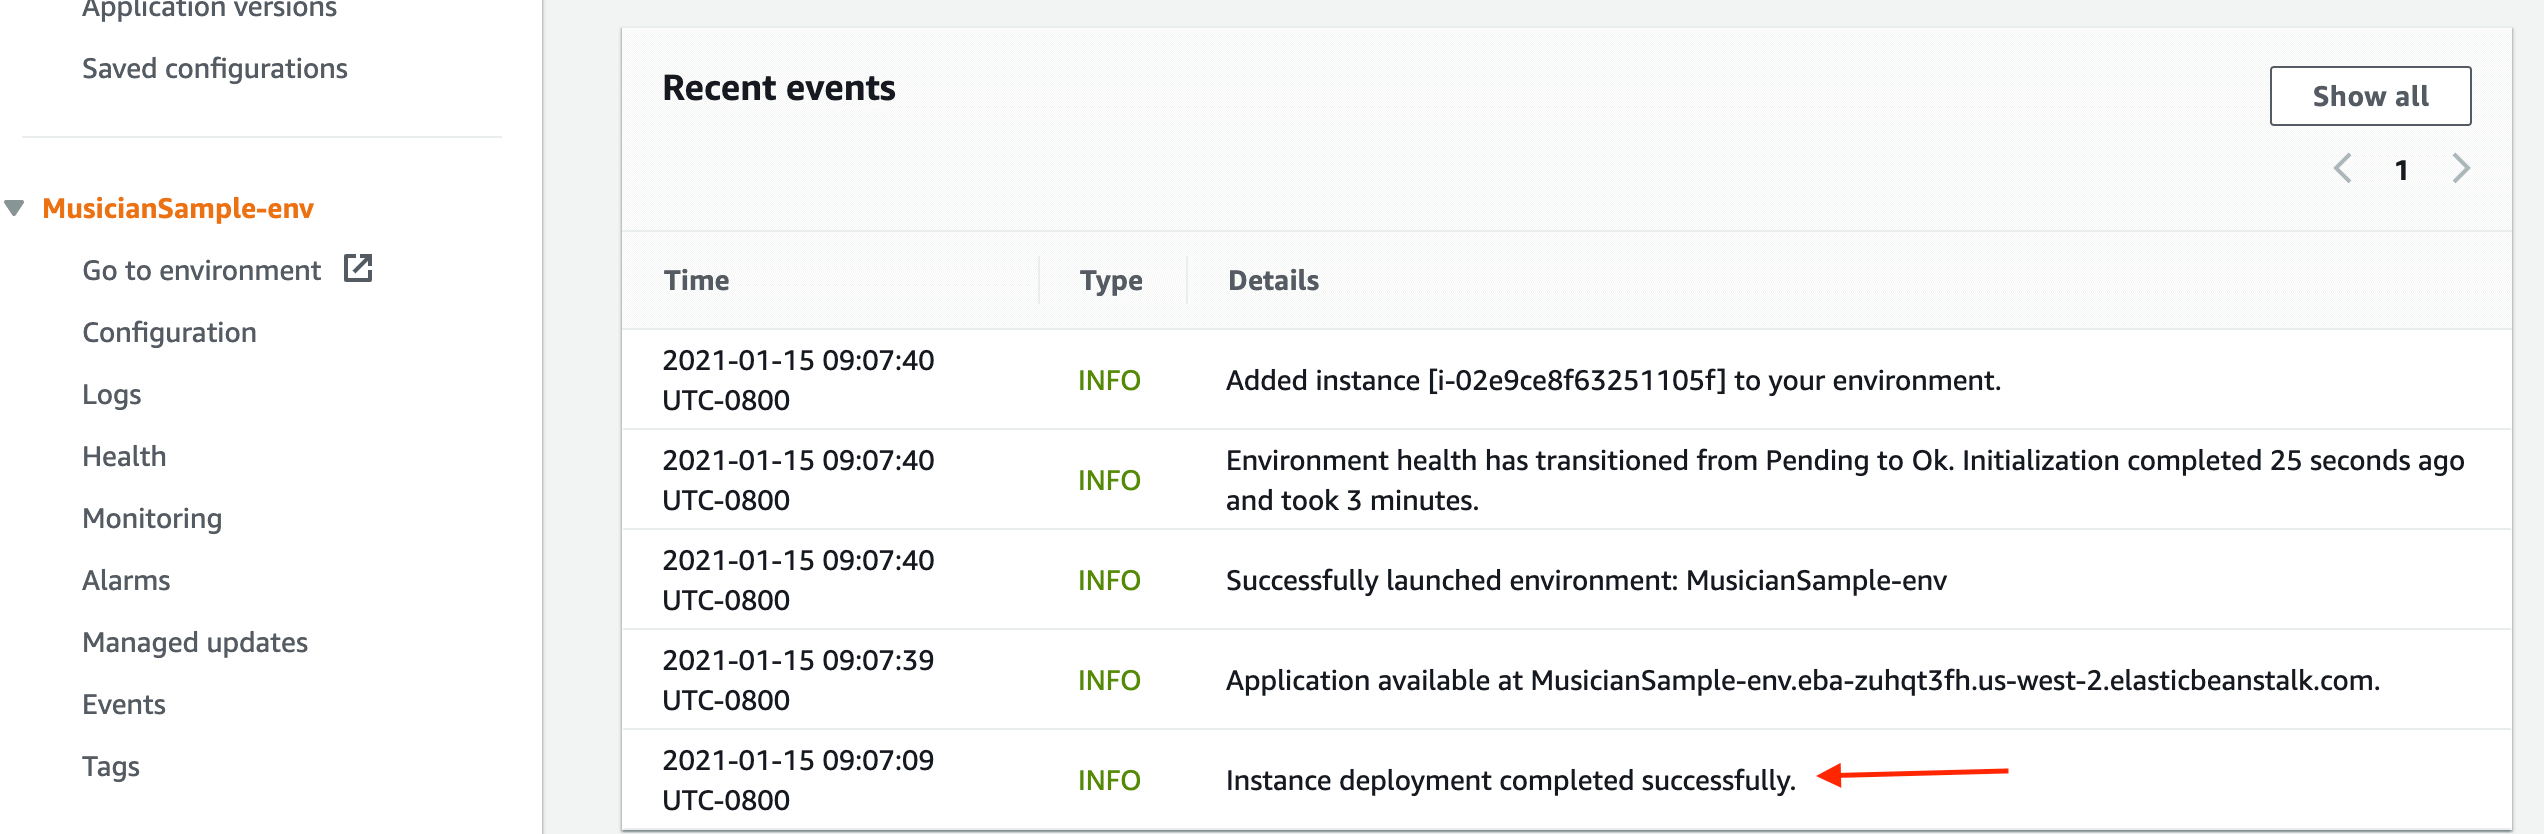
Figure 4: Environment overview page

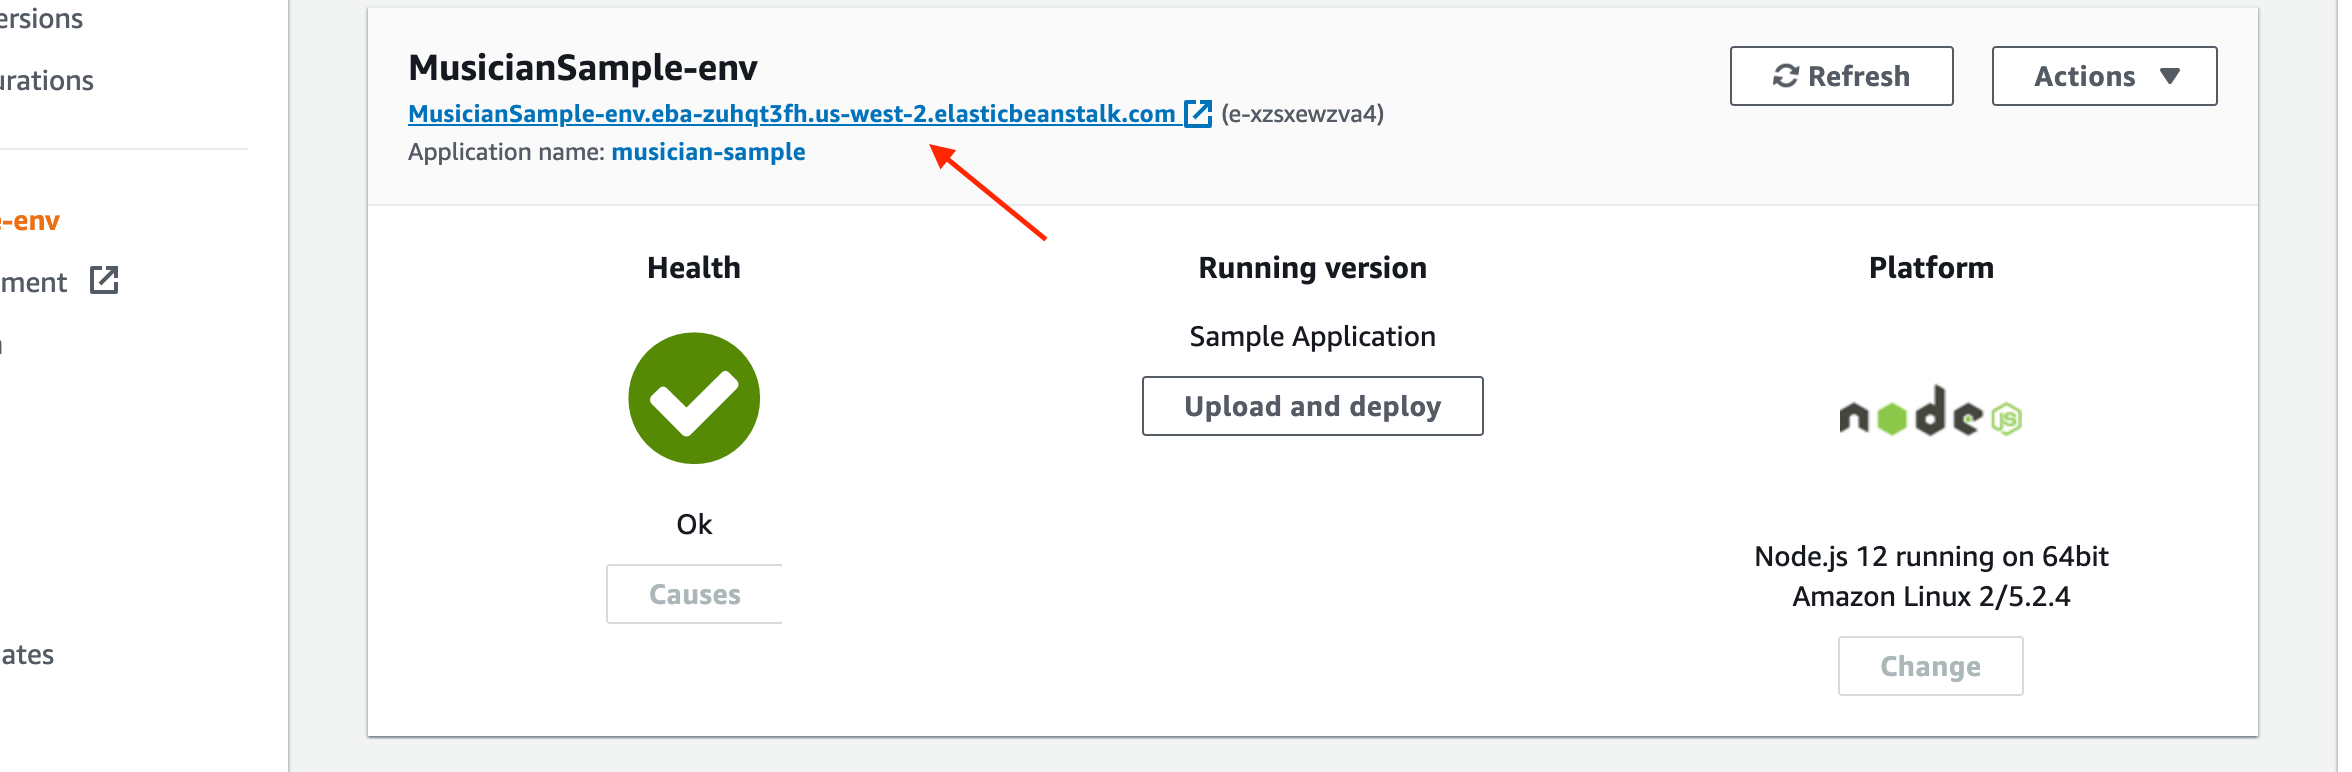
On top of the Overview Page you will see the environment’s URL below the environment name, click on this URL to get to the sample application’s Congratulations Page.
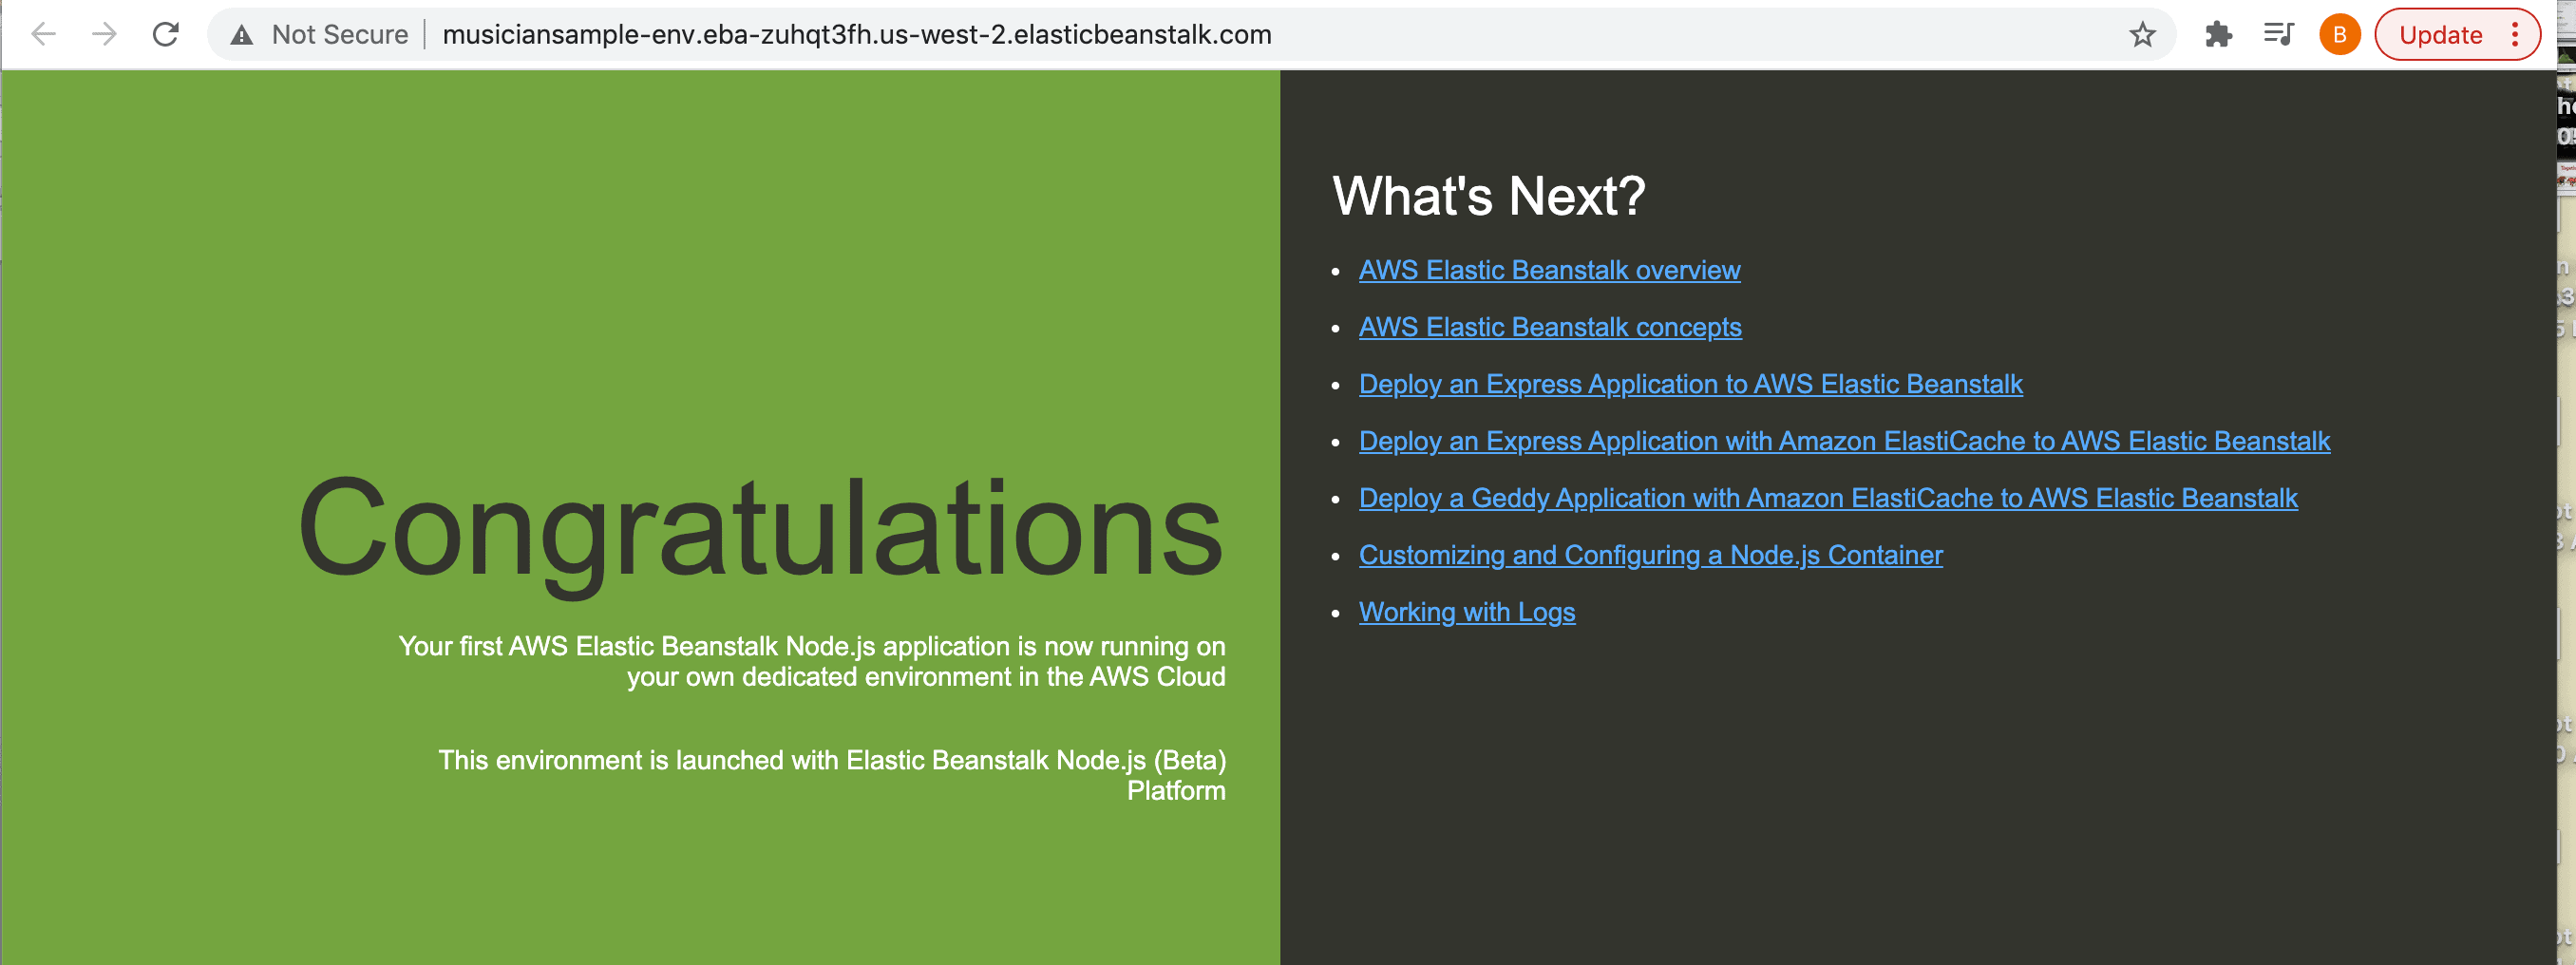
Once your application is successfully deploy, we will set up a Continuous Integration and Continuous Delivery (CI/CD) AWS pipeline using AWS Code Pipeline Service. AWS Code pipeline services helps you to Build, Tests and Deploy code when there is any code changes in your source code.

We will learn how to create a simple pipeline that pulls code from GitHub repository and automatically deploy to AWS EC2 instances.

Click on “Service” dropdown and Select “CodePipeline” as shown in below picture OR you can also search “CodePipeline” in search bar.
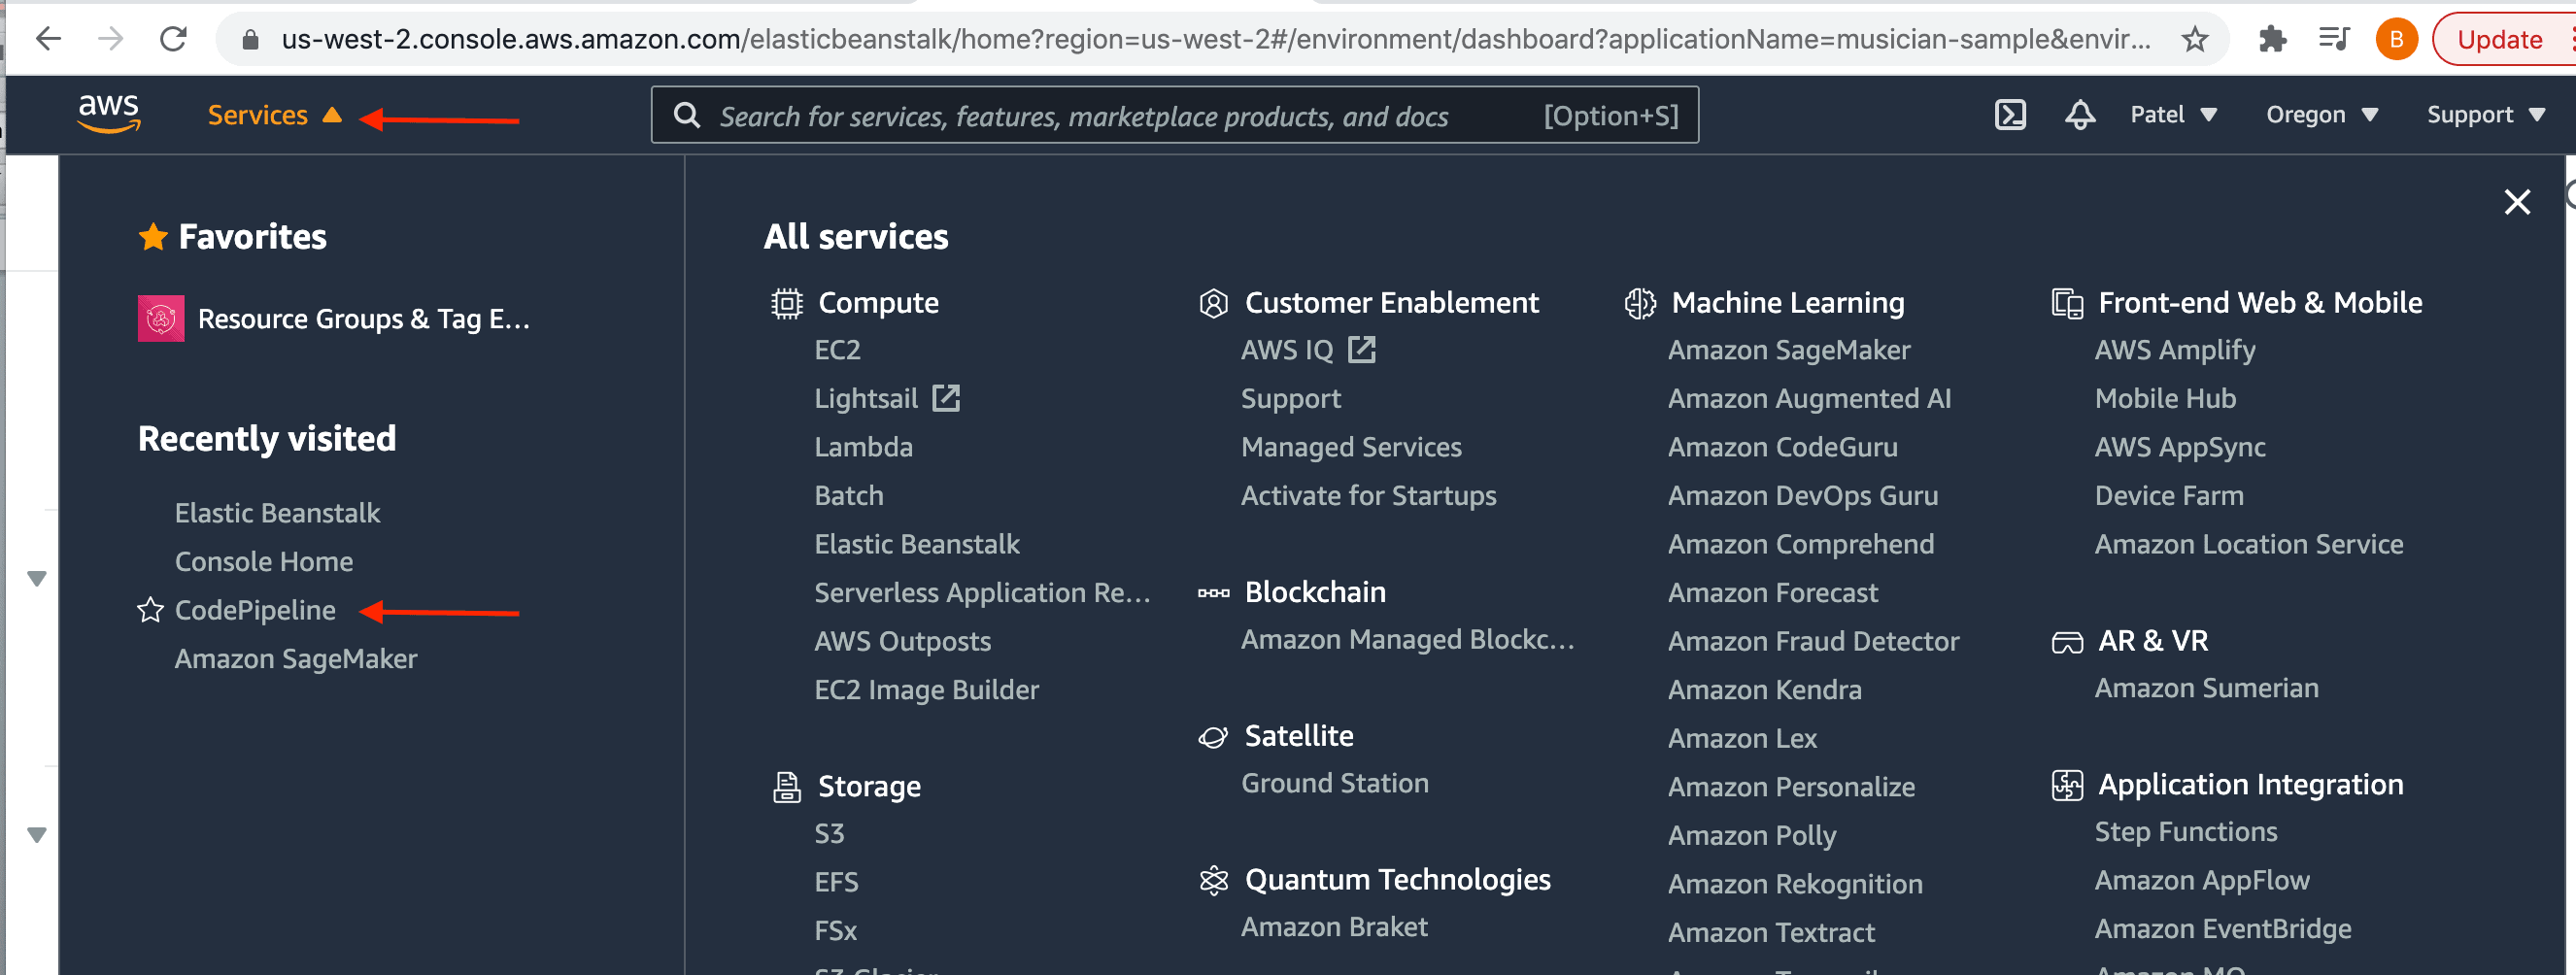
Figure 5: AWS Service page

On CodePipeline Dashboard page choose “Create Pipeline”. Click on Get started for the first time user.
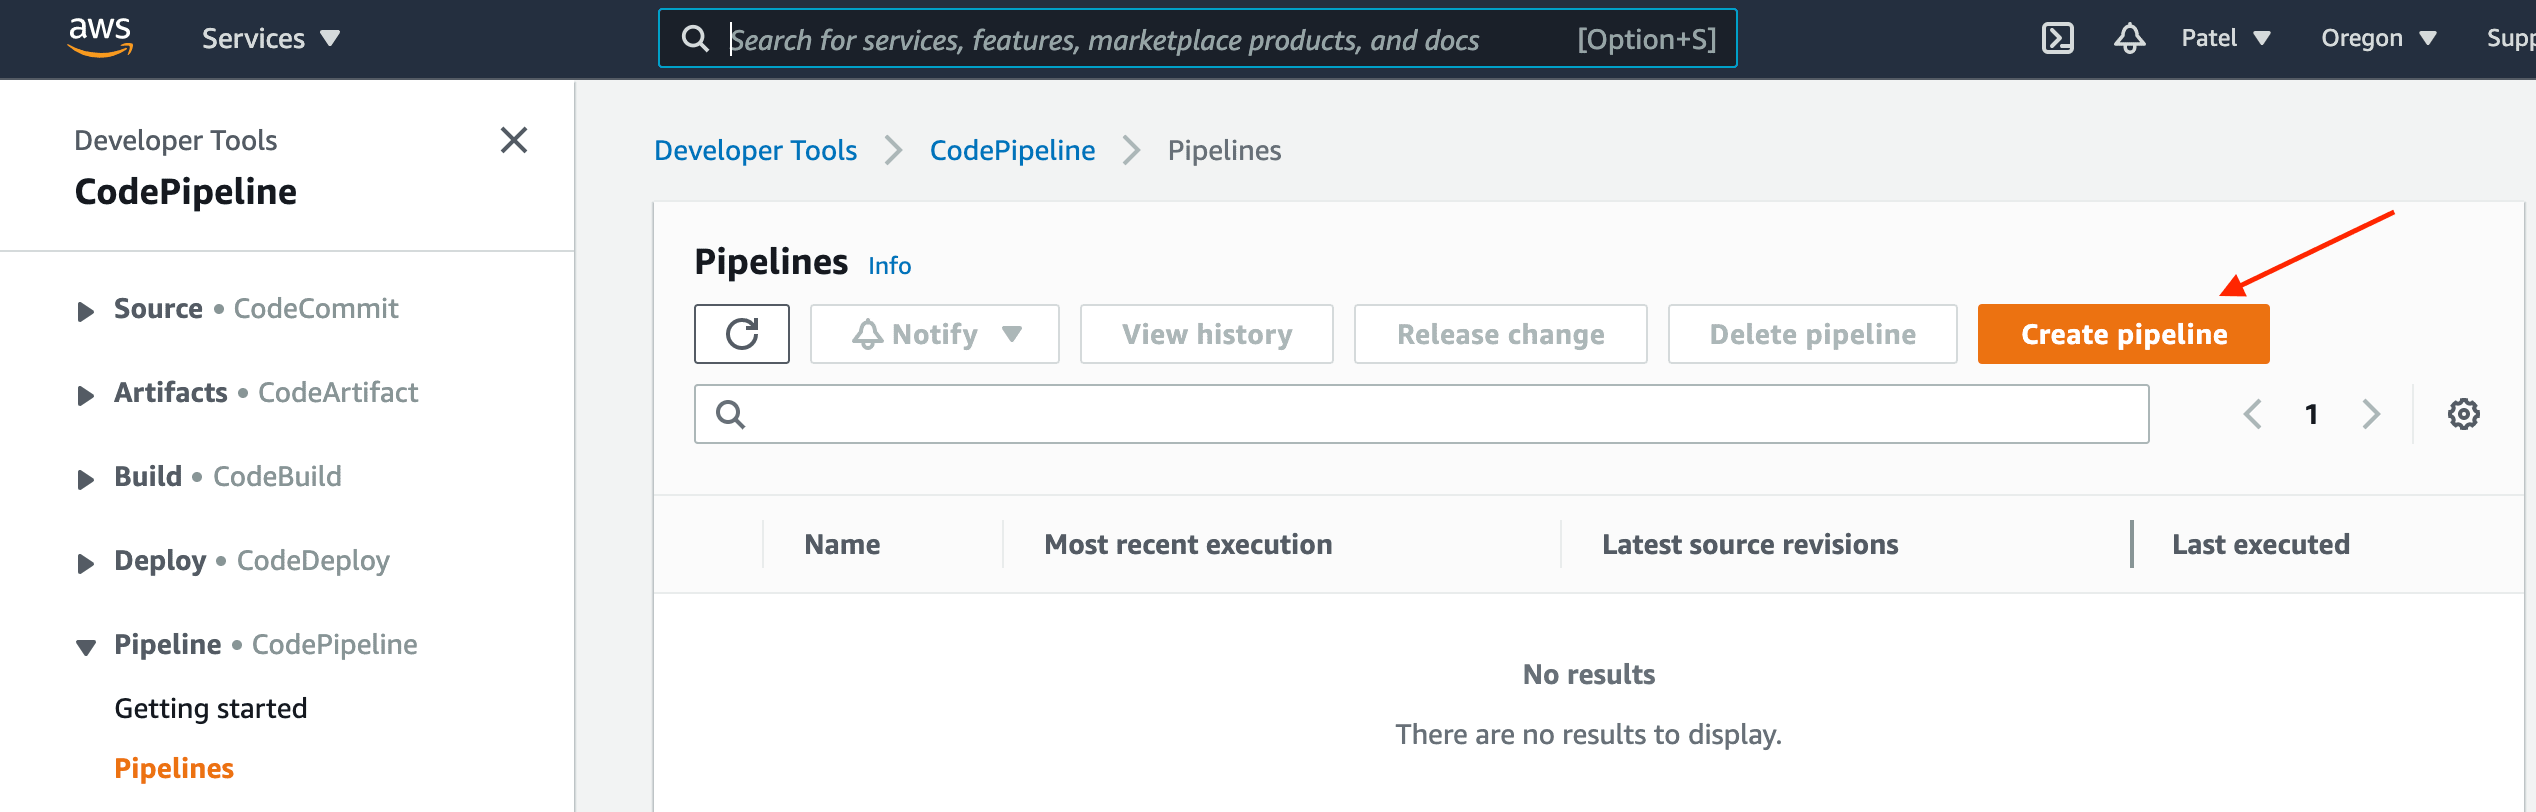
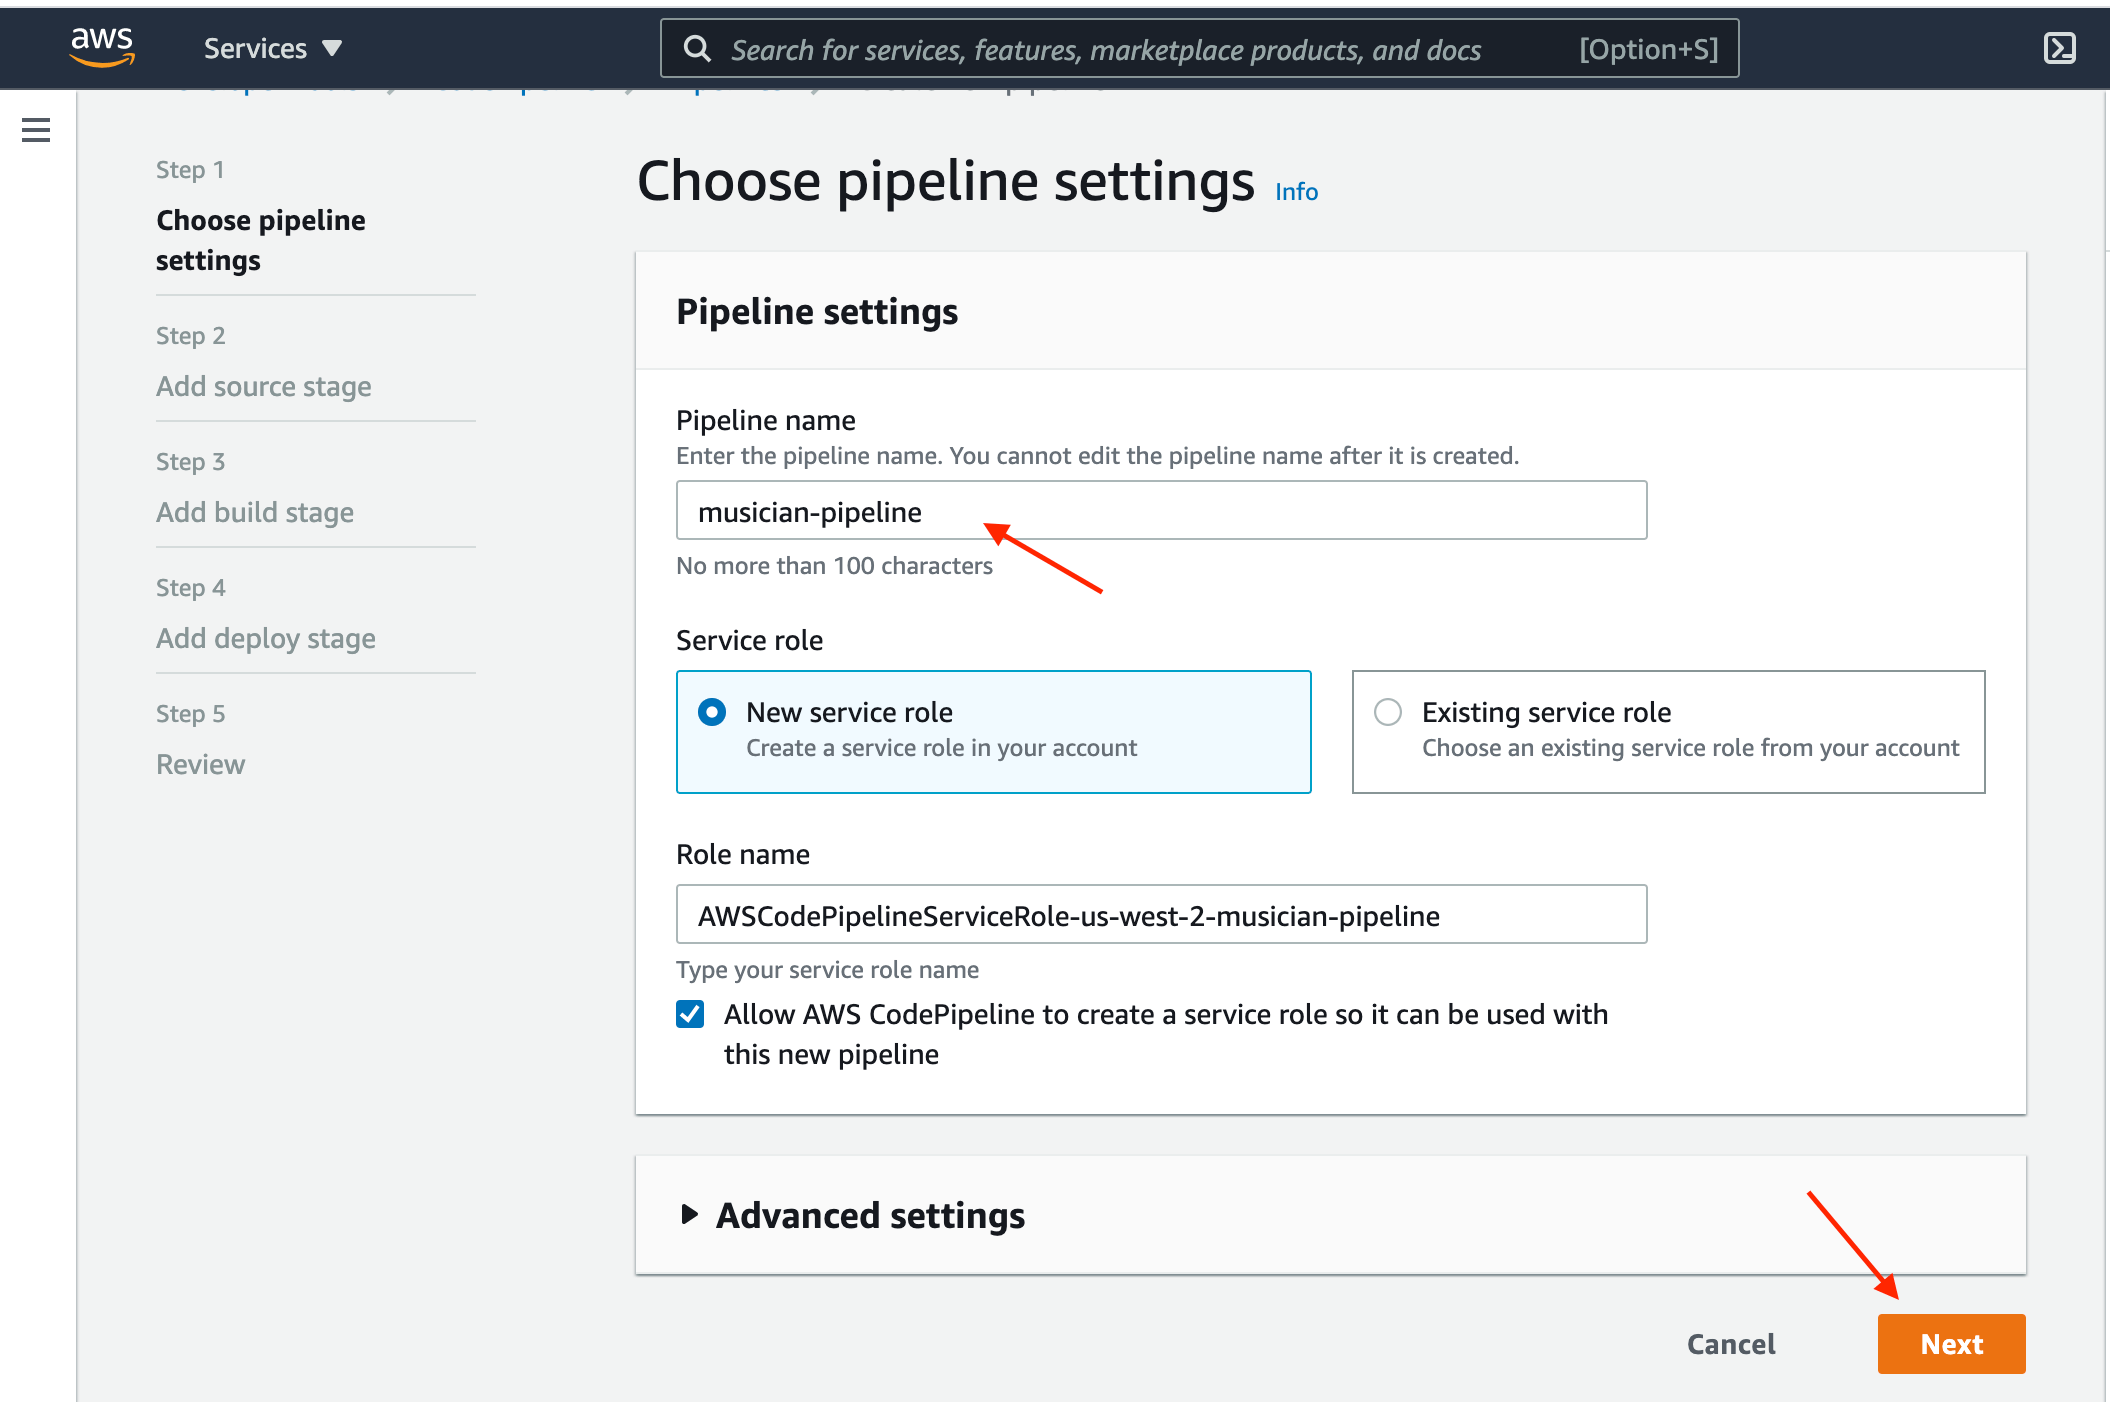
Figure 6: Create pipeline page

Choose Pipeline settings

AWS source resources you created must be in same region as your pipeline.

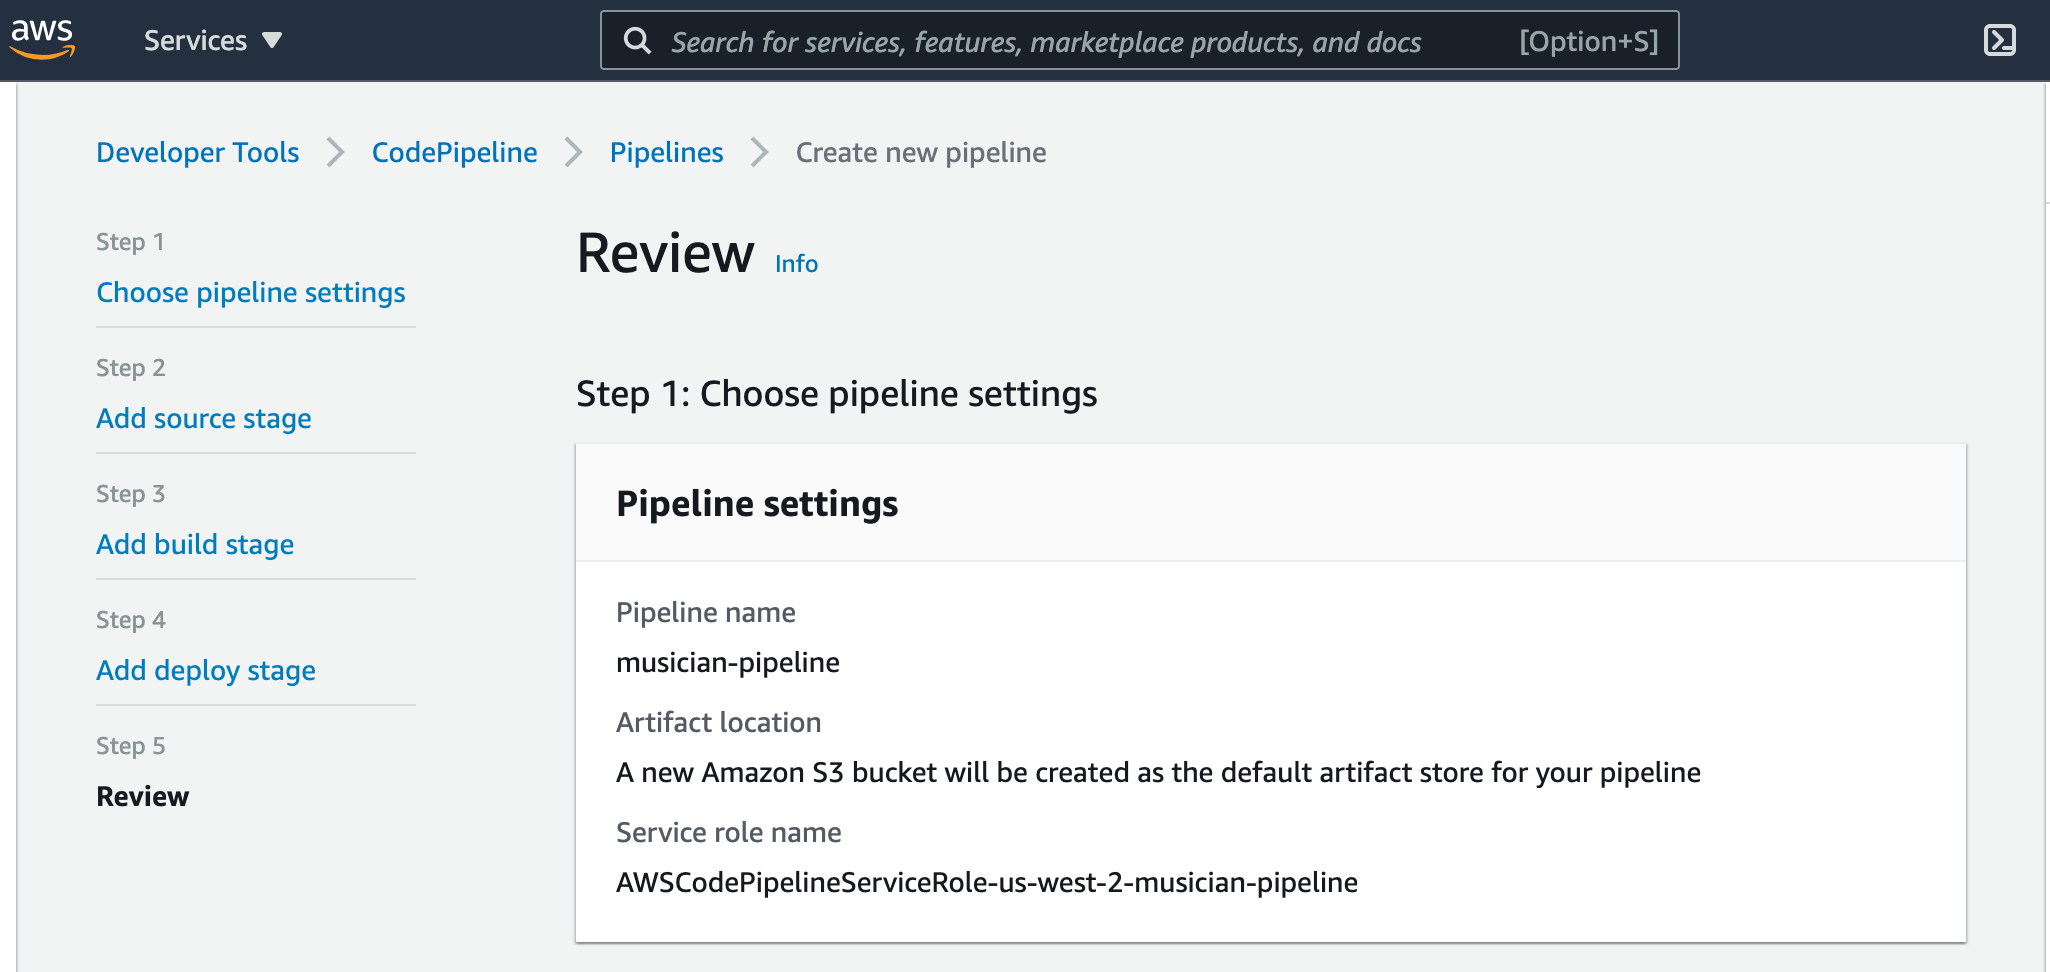
  1. In Pipeline Name enter name of the pipeline. e.g: “musician-pipeline”. You cannot edit pipeline name once it is created.
  2. In Service Role default to ‘New Service Role’, it will help CodePipeline to create a new service role in IAM.
  3. In Role Name default to ‘AWSCodePipelineServiceRole-Region-pipeline name’ .Example,this is the service role created for a pipeline named AWSCodePipelineServiceRole-us-west-2-musician-pipeline.
  4. Click on Next Button as shown in figure.

Step 1: Add Source Stage

  1. On Source page, under Source Provider ,choose GitHub(Version 1).
  2. If you have not created GitHub connection , click on “Connect to GitHub” button to grant permission to AWS Code pipeline to access your GitHub repository. This will help AWS Code Pipeline to upload your committed changes from GitHub to AWS Code Pipeline.
  3. GitHub connection page will appear as shown below.
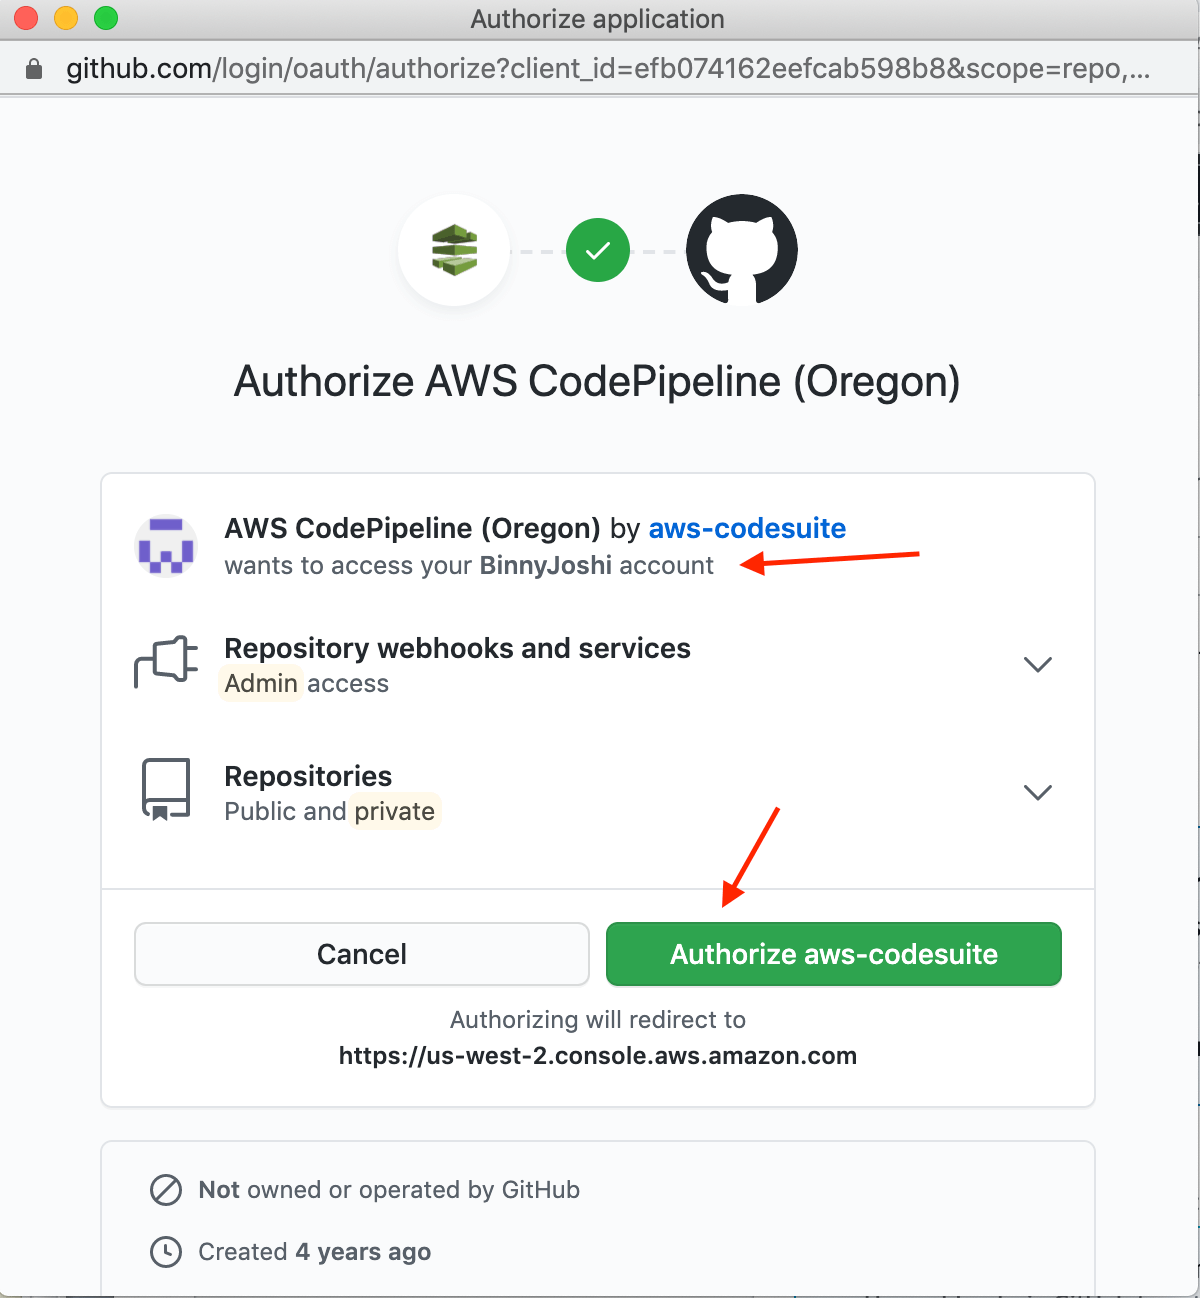
  1. Click on “Authorize aws-codesuite” . It will grant permission to connect to GitHub
  2. To connect to GitHub you need to click on “ Authorize AWS code-suite” green button. Once you are successfully connected you will see the successful message in green box.
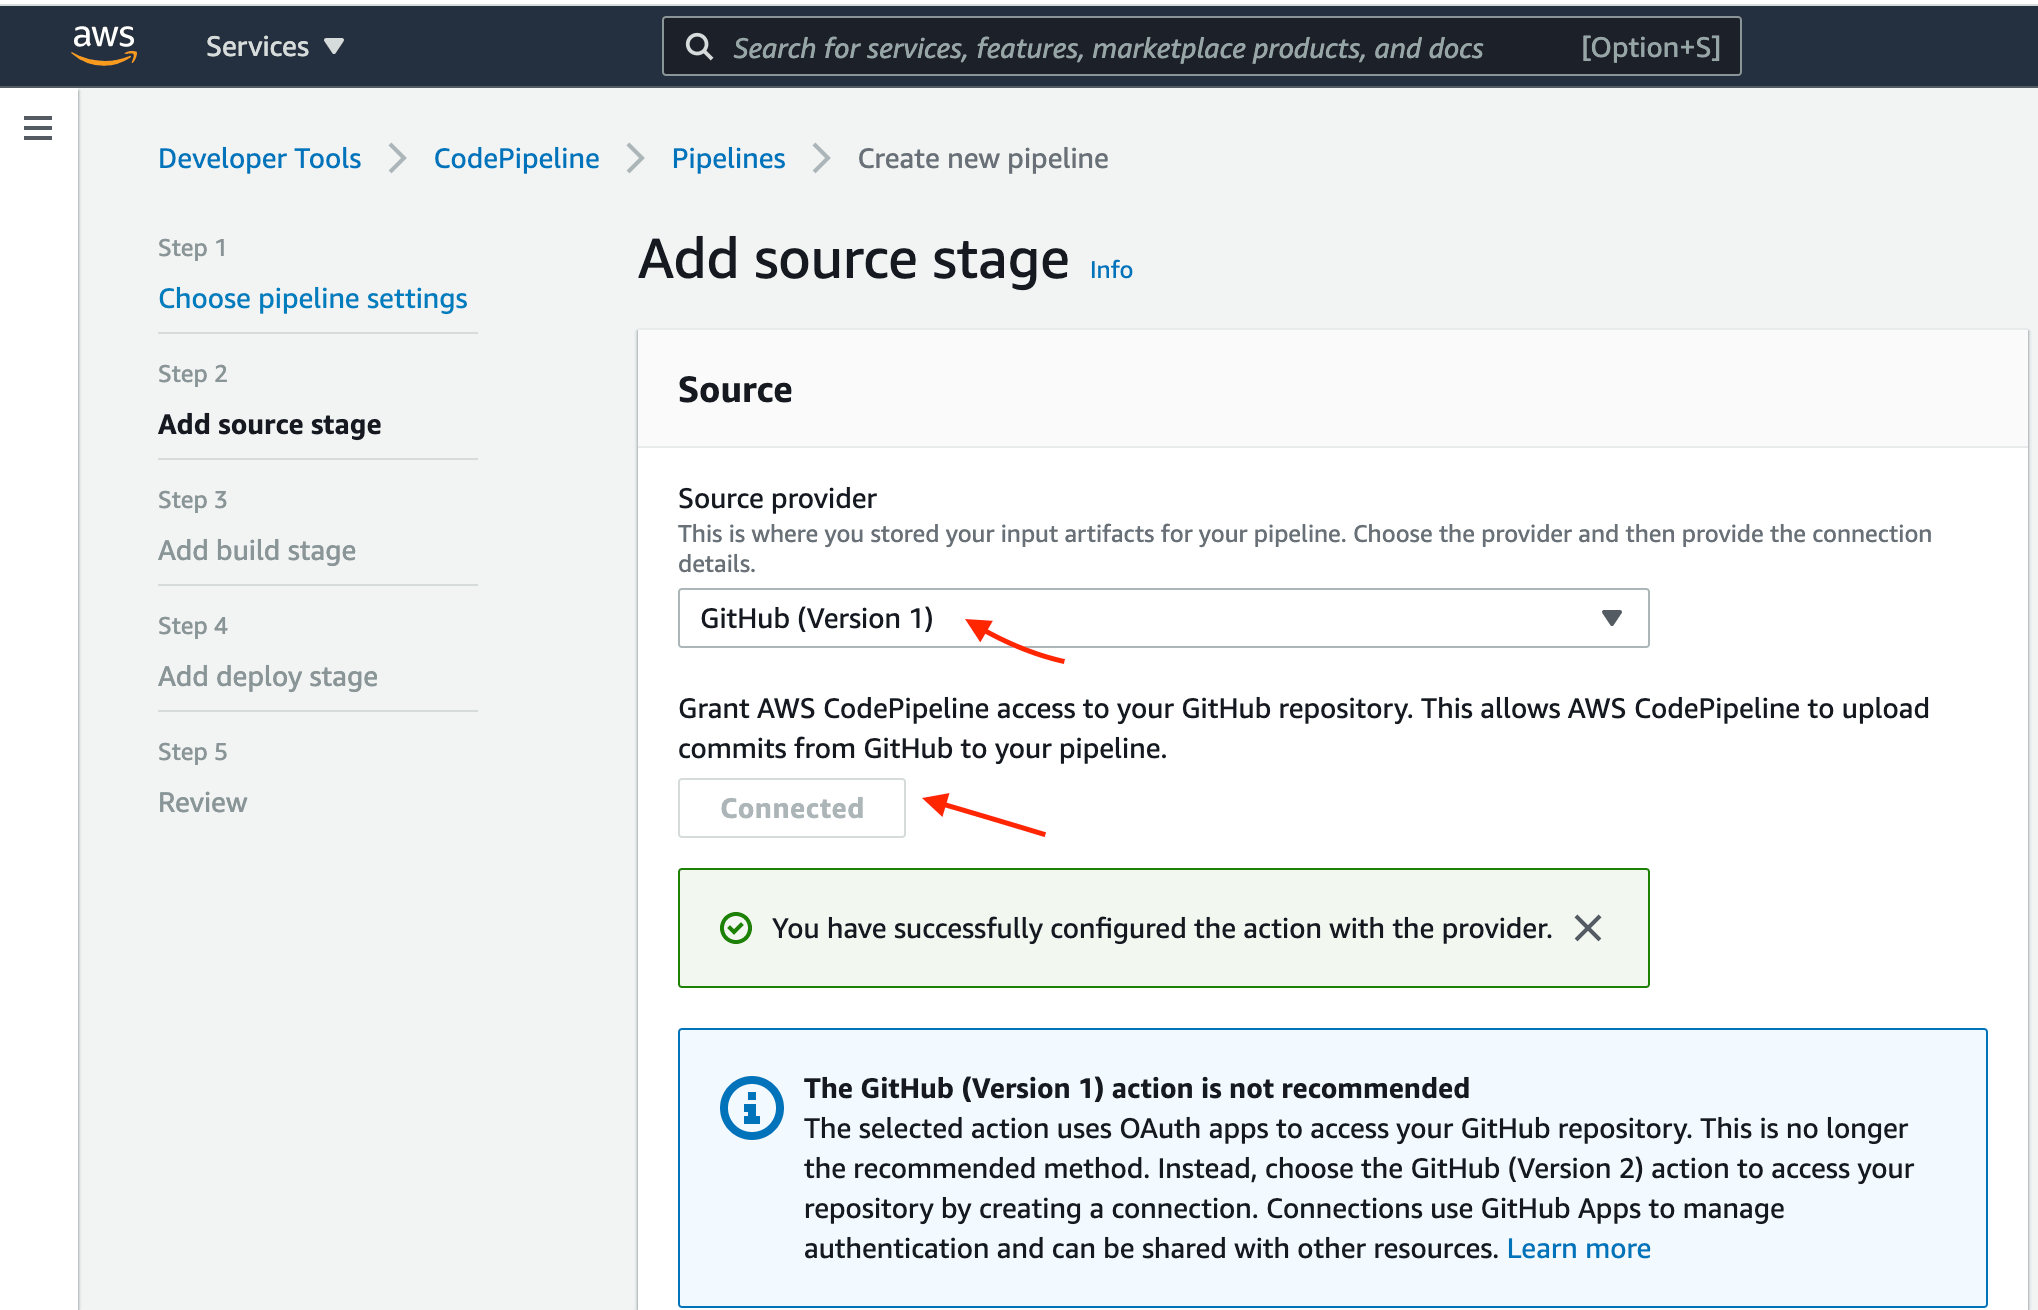
Figure 7: Add source stage
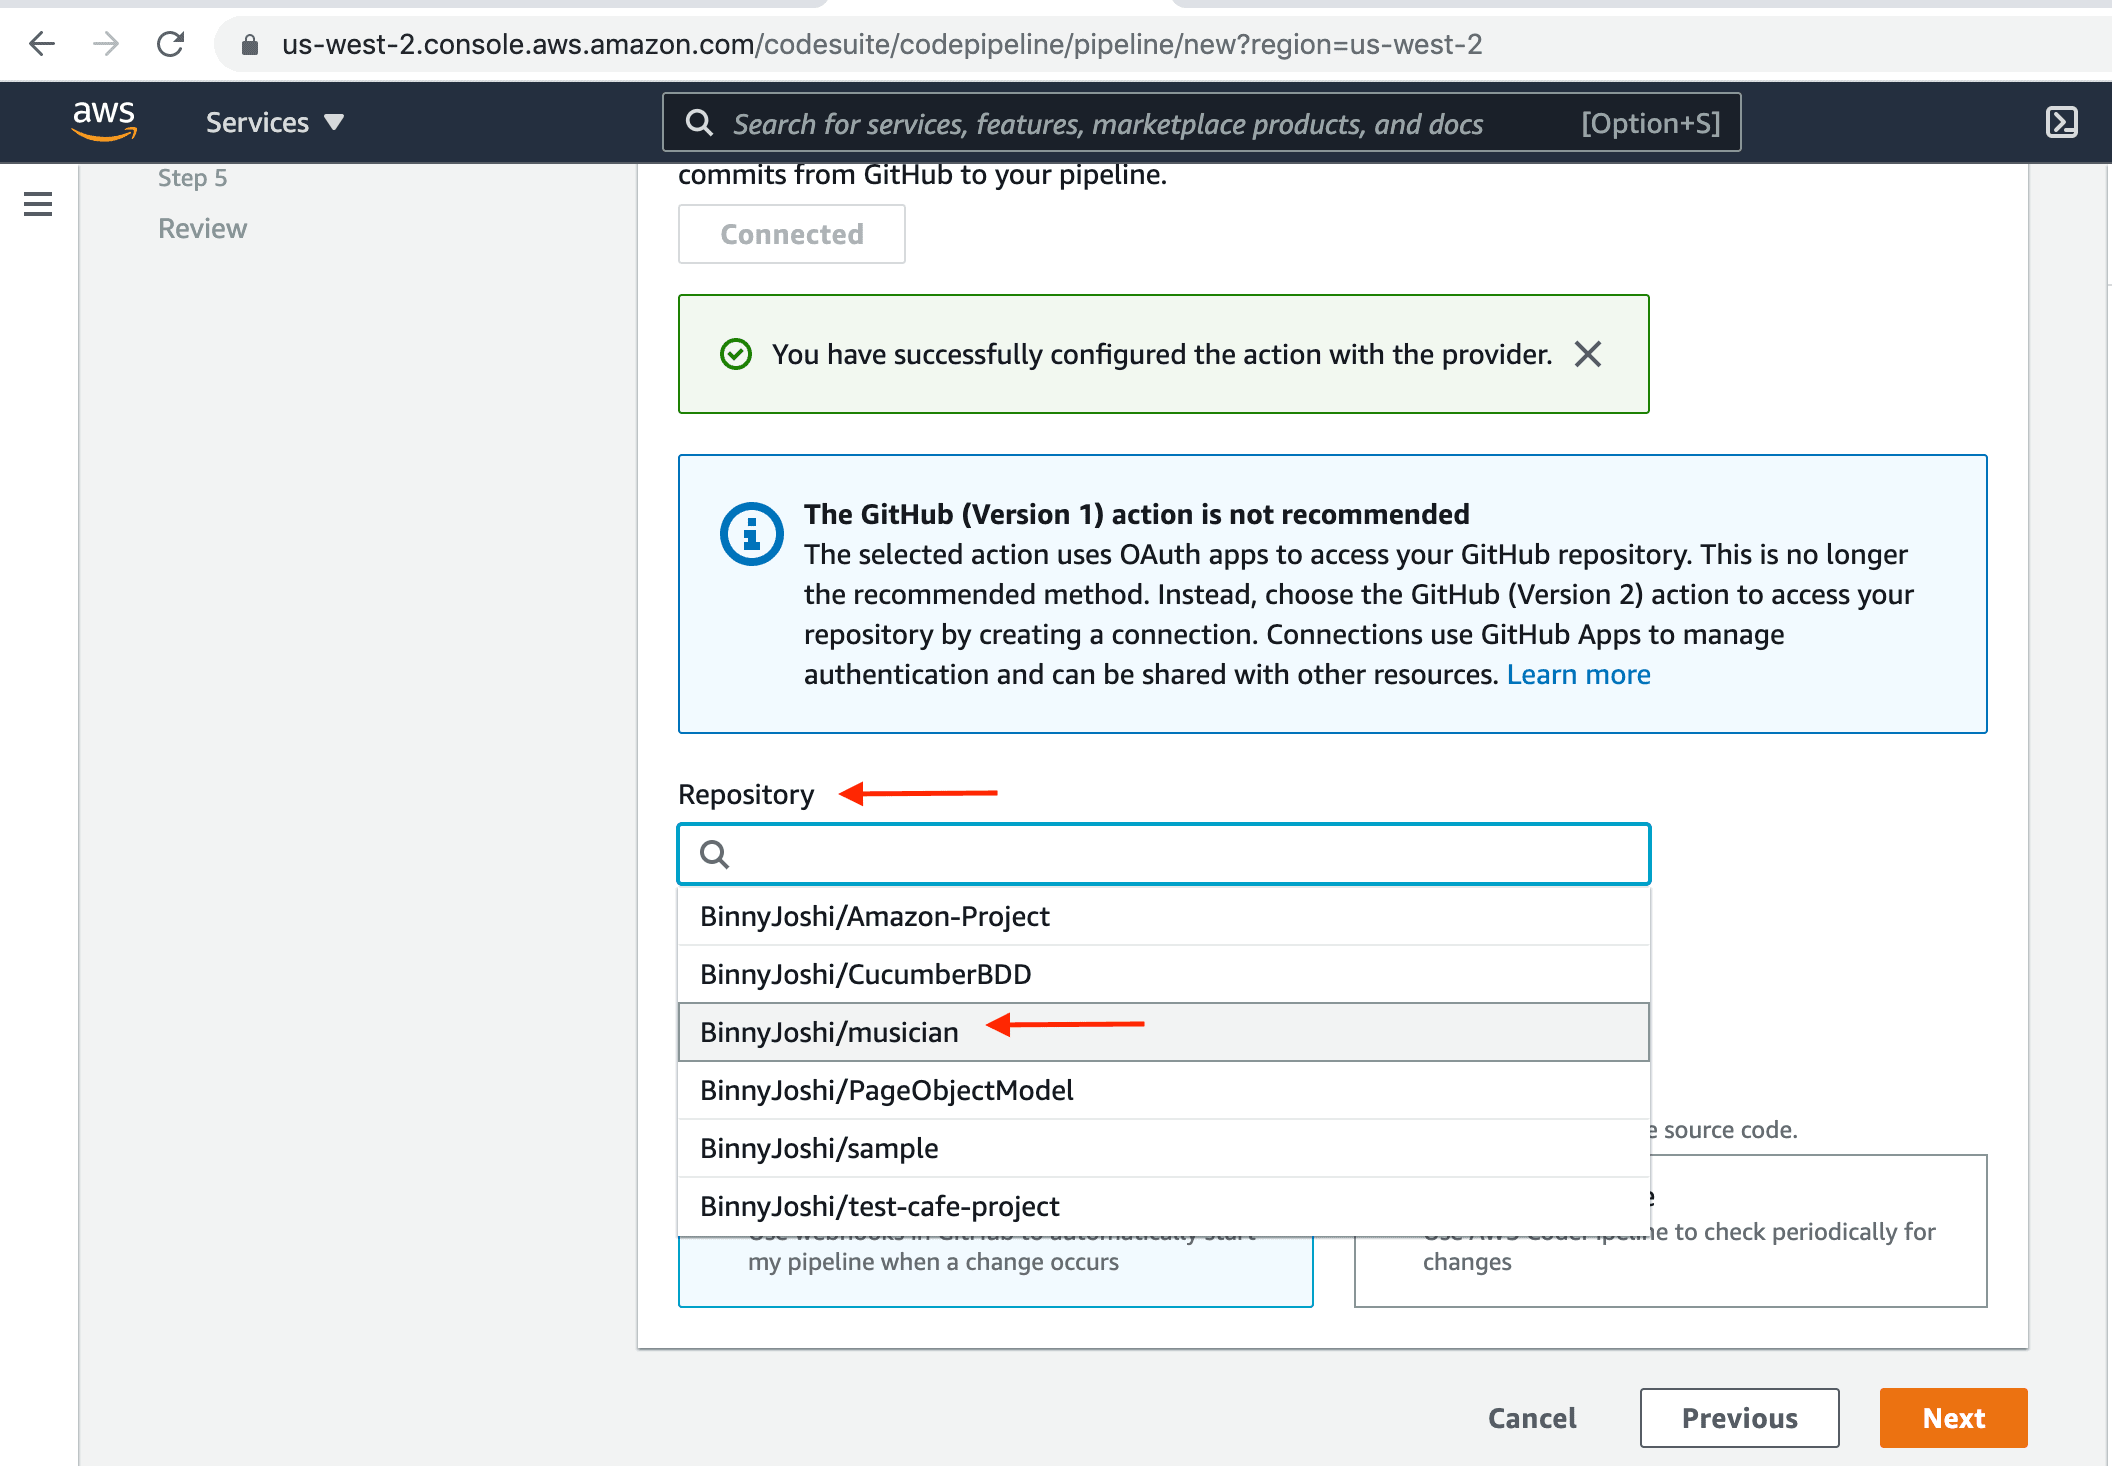
Figure 7.1 : Add source stage

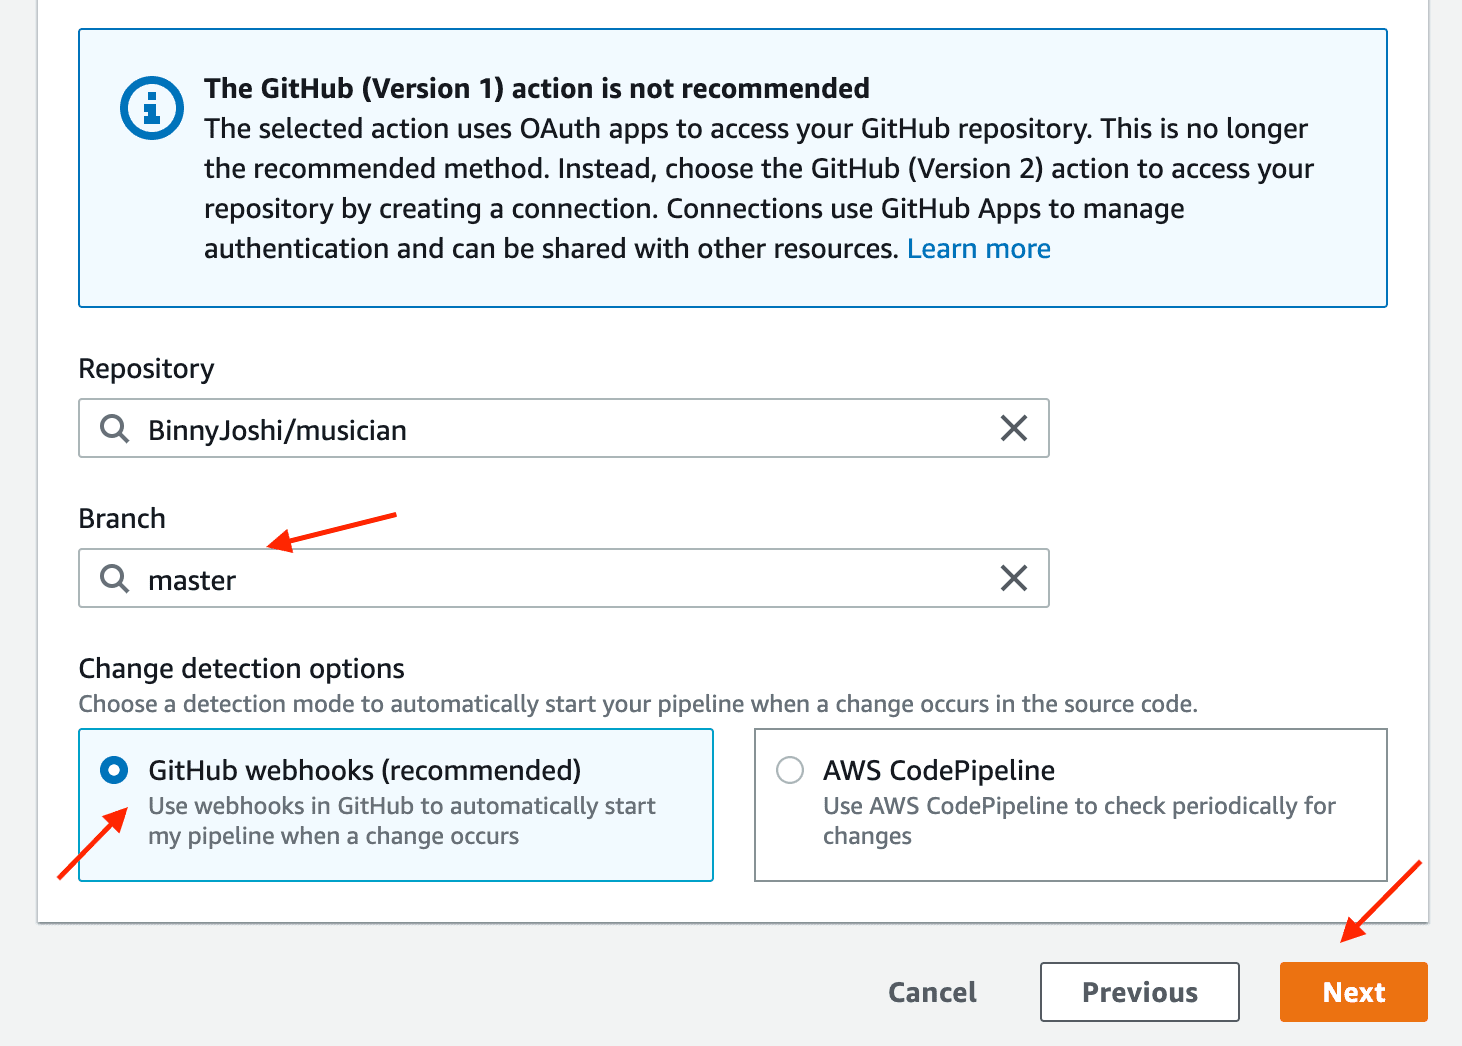
  1. In repository choose the name of your repository where you committed your code ,example : BinnyJoshi/musician
  2. In Branch select the branch name where you want your pipeline to detect source code. Example: Master
  3. Choose GitHub webhooks, this will allow to trigger pipeline whenever there is any code changes to repository.
  4. Click on NEXT button.

Step 2 : Add Build stage

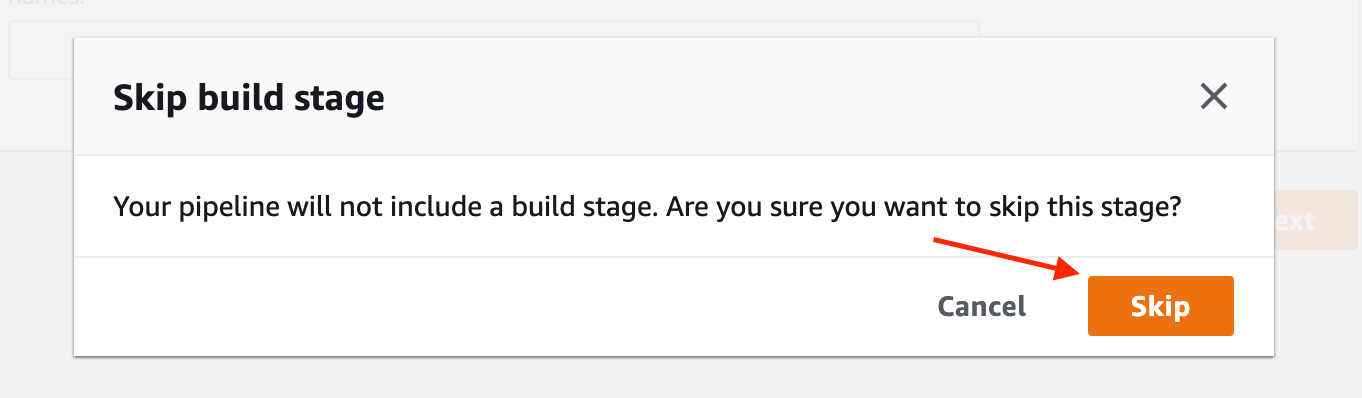
1 ) Skip Build Stage, click on “Skip” button.
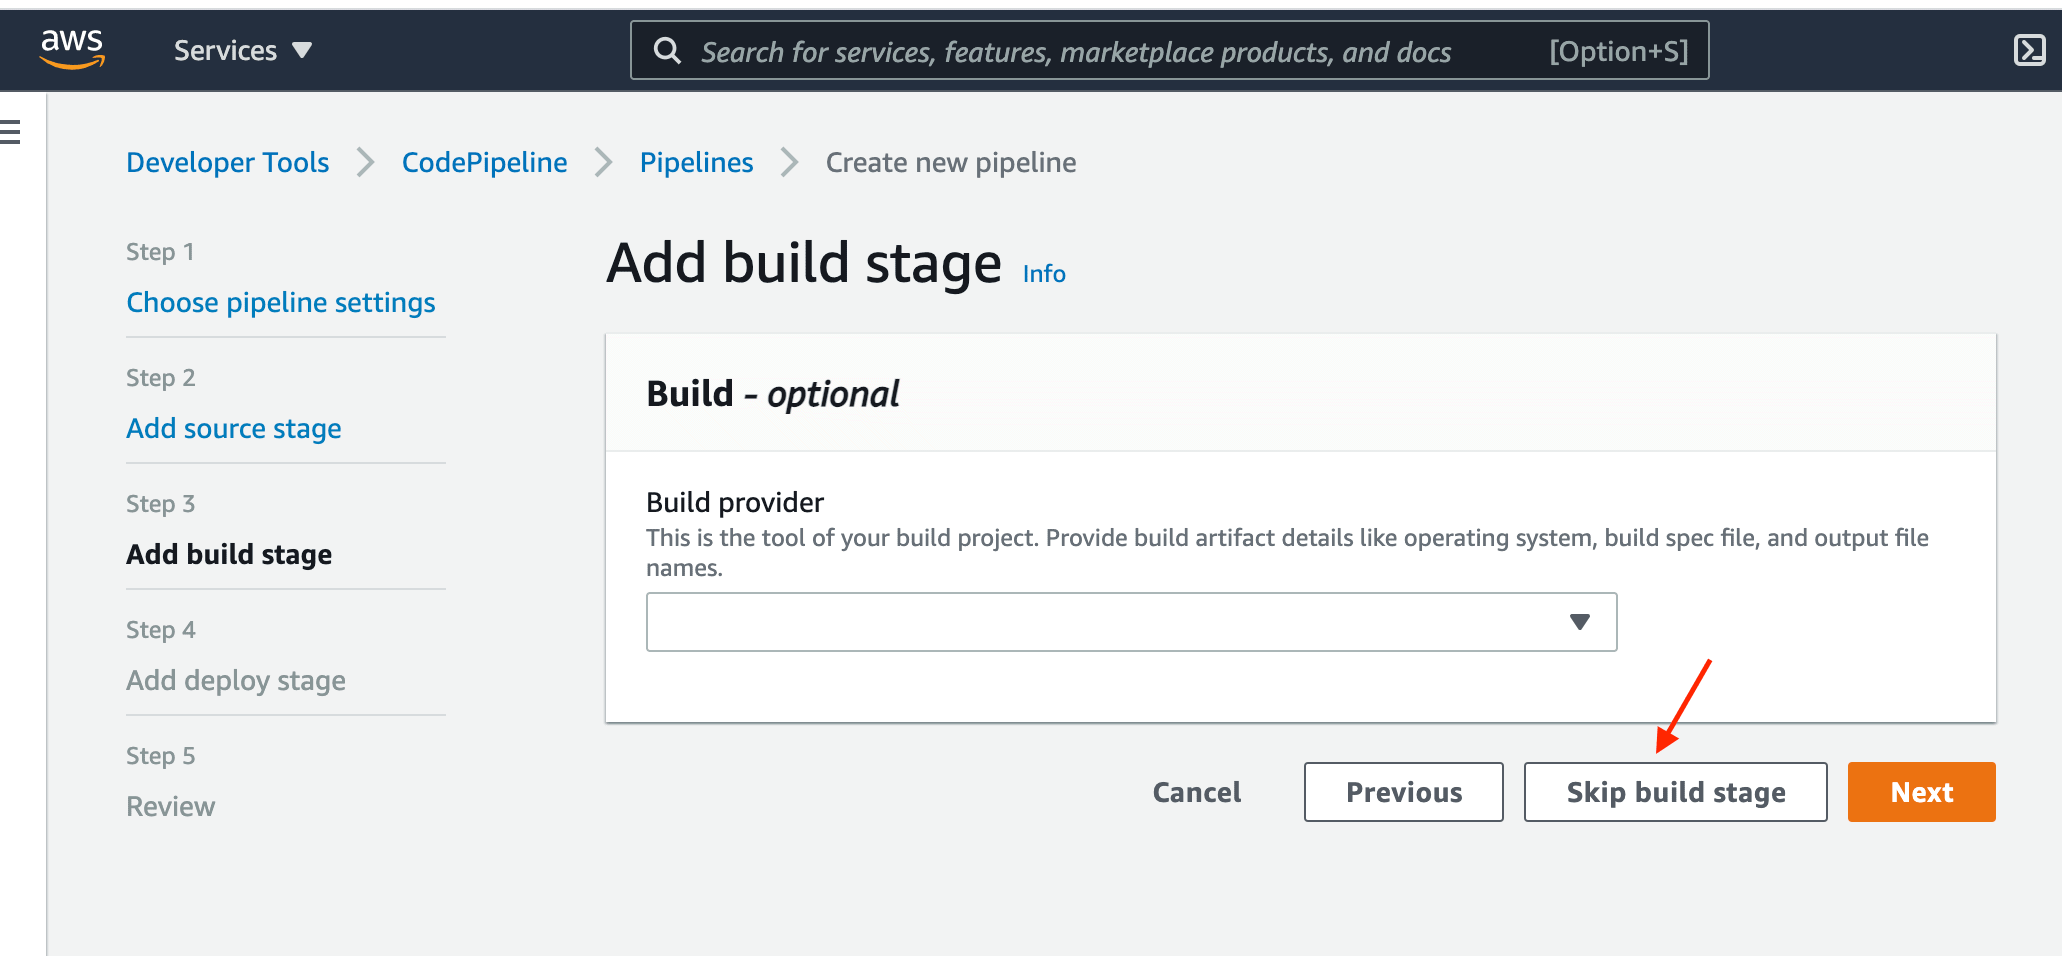
Figure 9: Add Build stage

Step 3 : Add Deploy Stage details

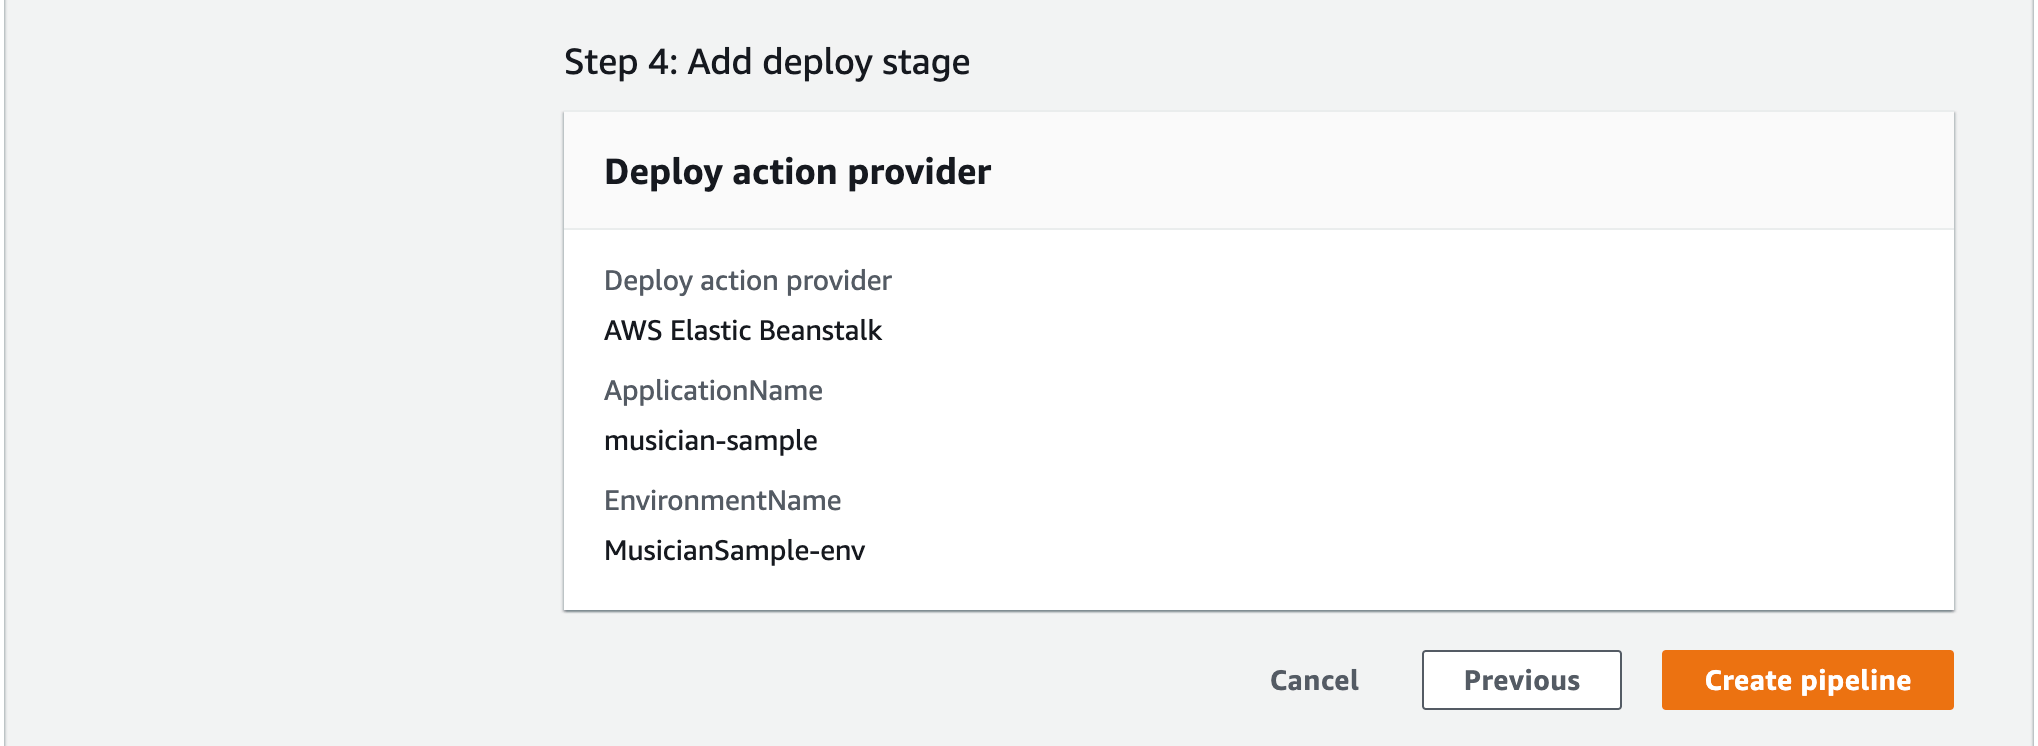
  1. In Deploy provider , choose AWS Elastic Beanstalk.
  2. In Region select the region where you have created your source code.
  3. In Application name enter or choose the name that you have already created on AWS Elastic Beanstalk console.
  4. In Environment name enter or choose the name that you already created on AWS Elastic Beanstalk console.
  5. Click “Next” button
  6. You will be directed to pipeline “Review page”.
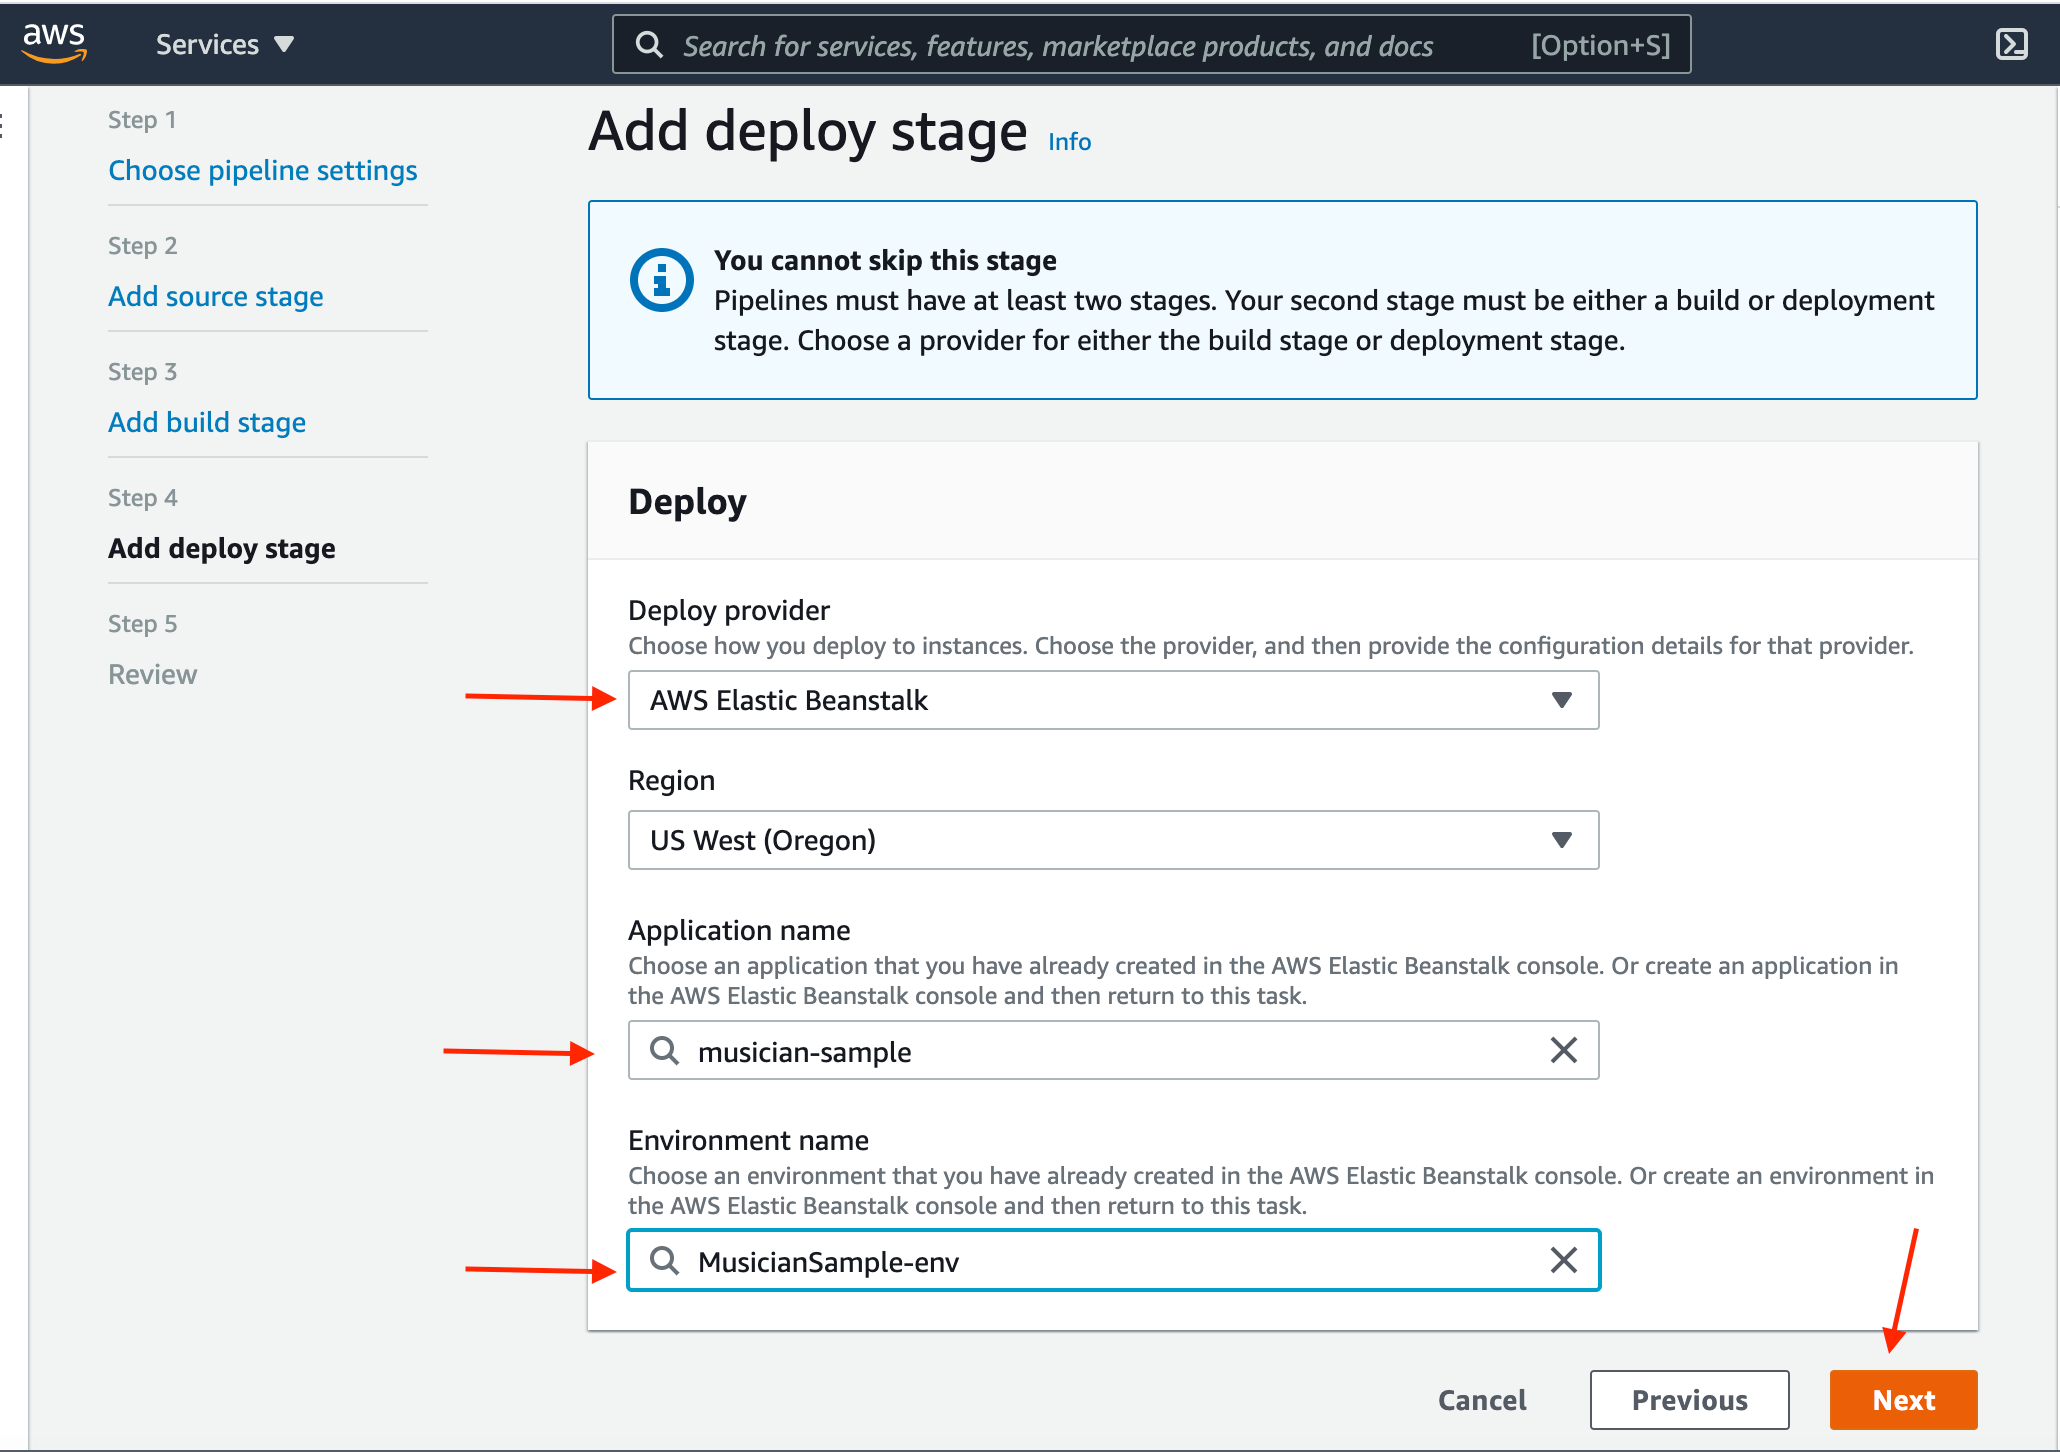
Figure 10: Add deploy stage

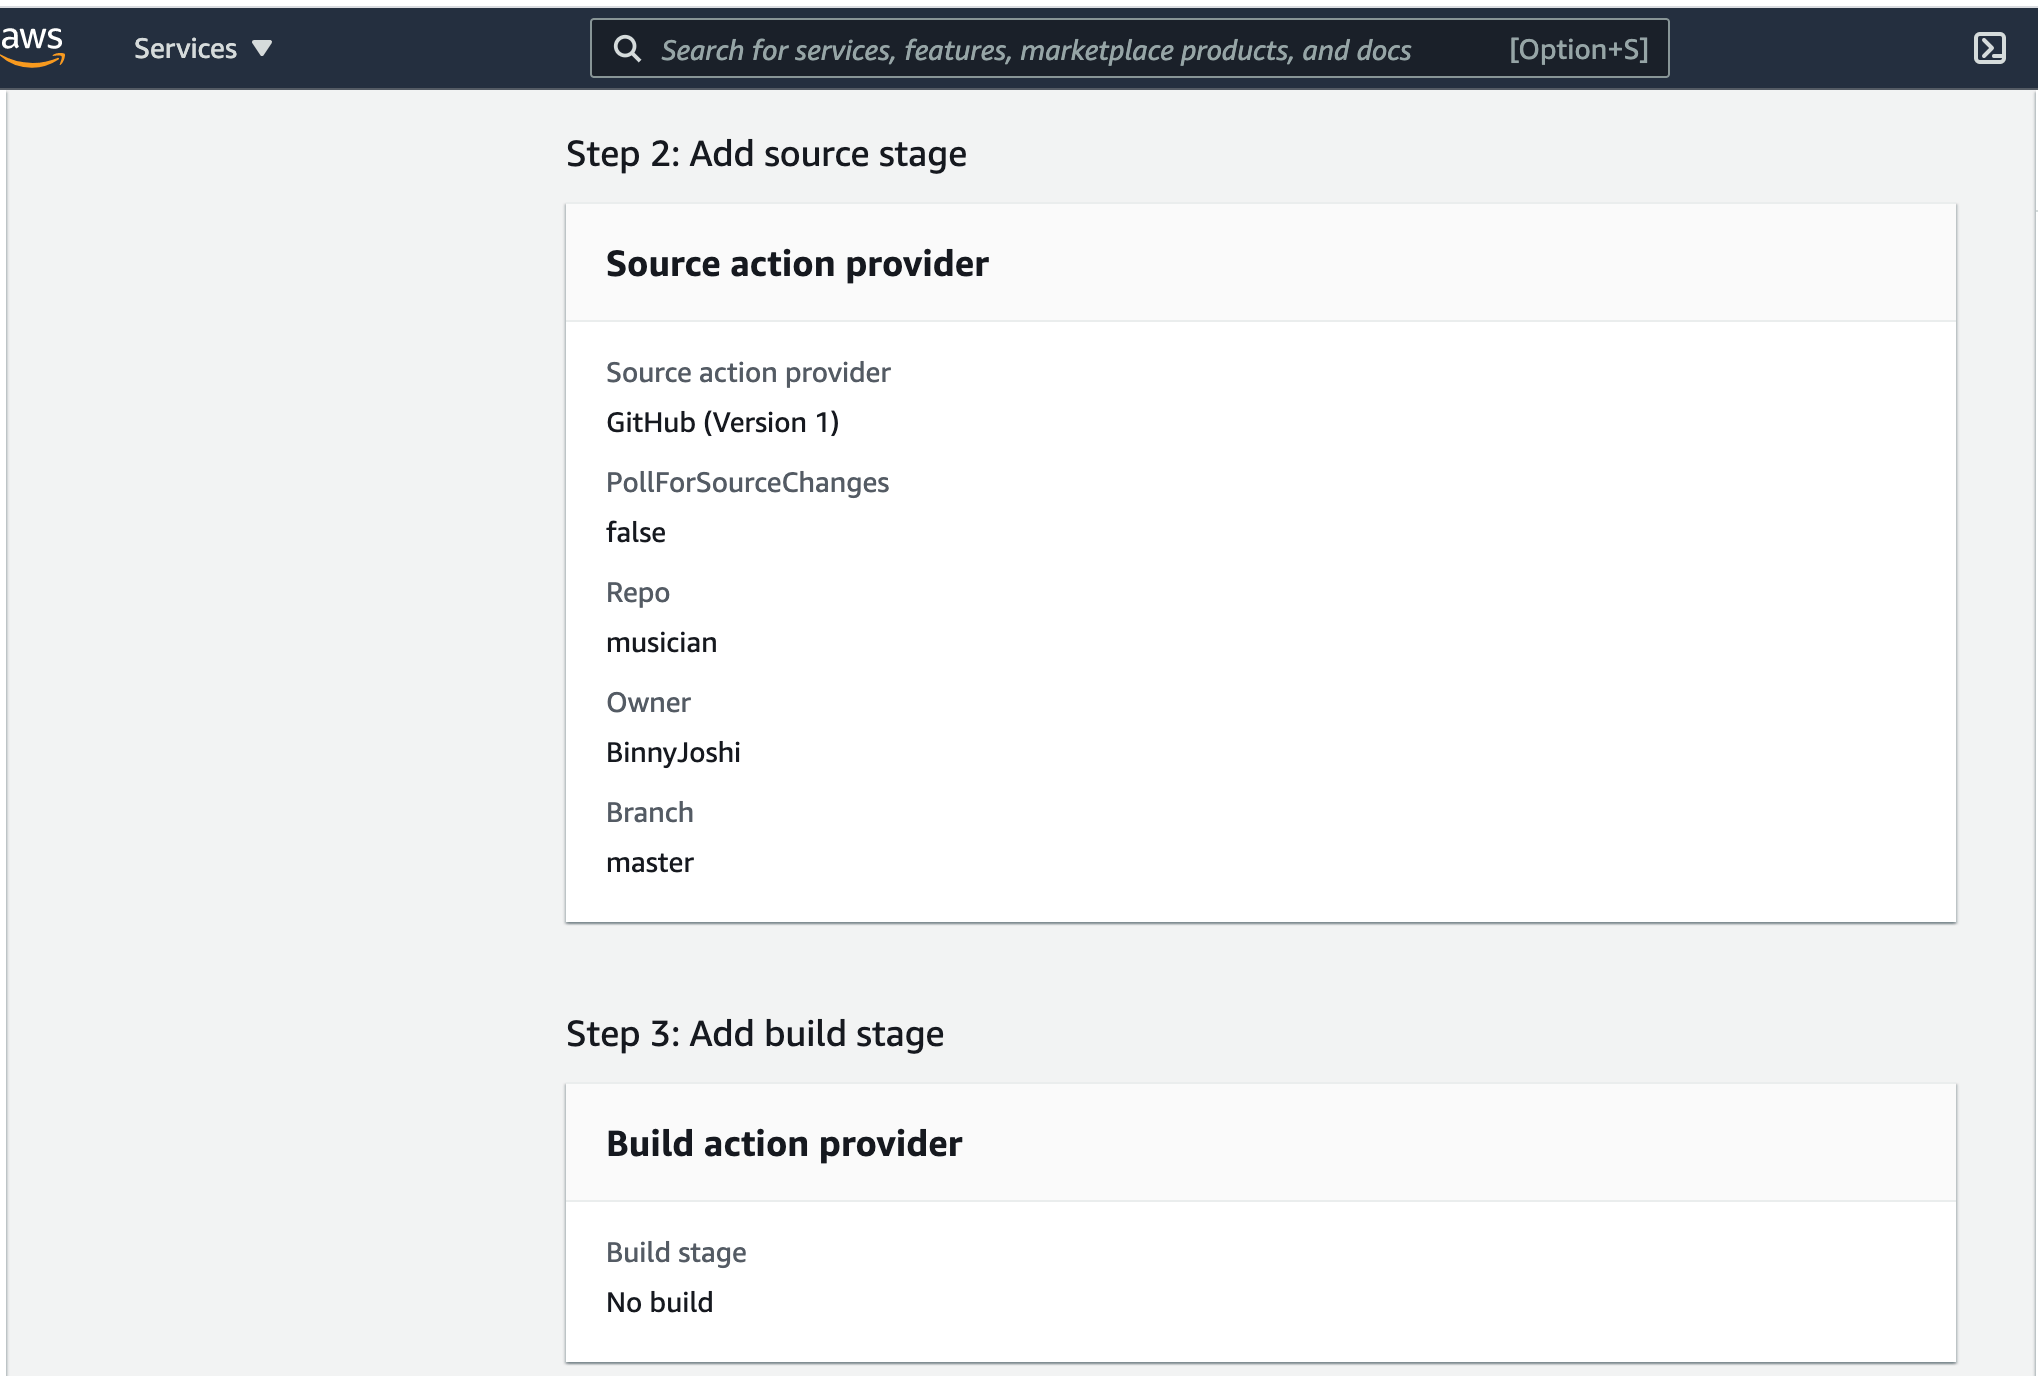
Pipeline Review page details – as shown in below figure:

  • Pipeline Settings,
  • Add Source stage
  • Add Build stage
  • Add Deploy stage

Figure 11: Review page

Click on “Create pipeline” button.

In the pipeline view, you will see the success message banner is displayed, and the build action continues until it is completed.
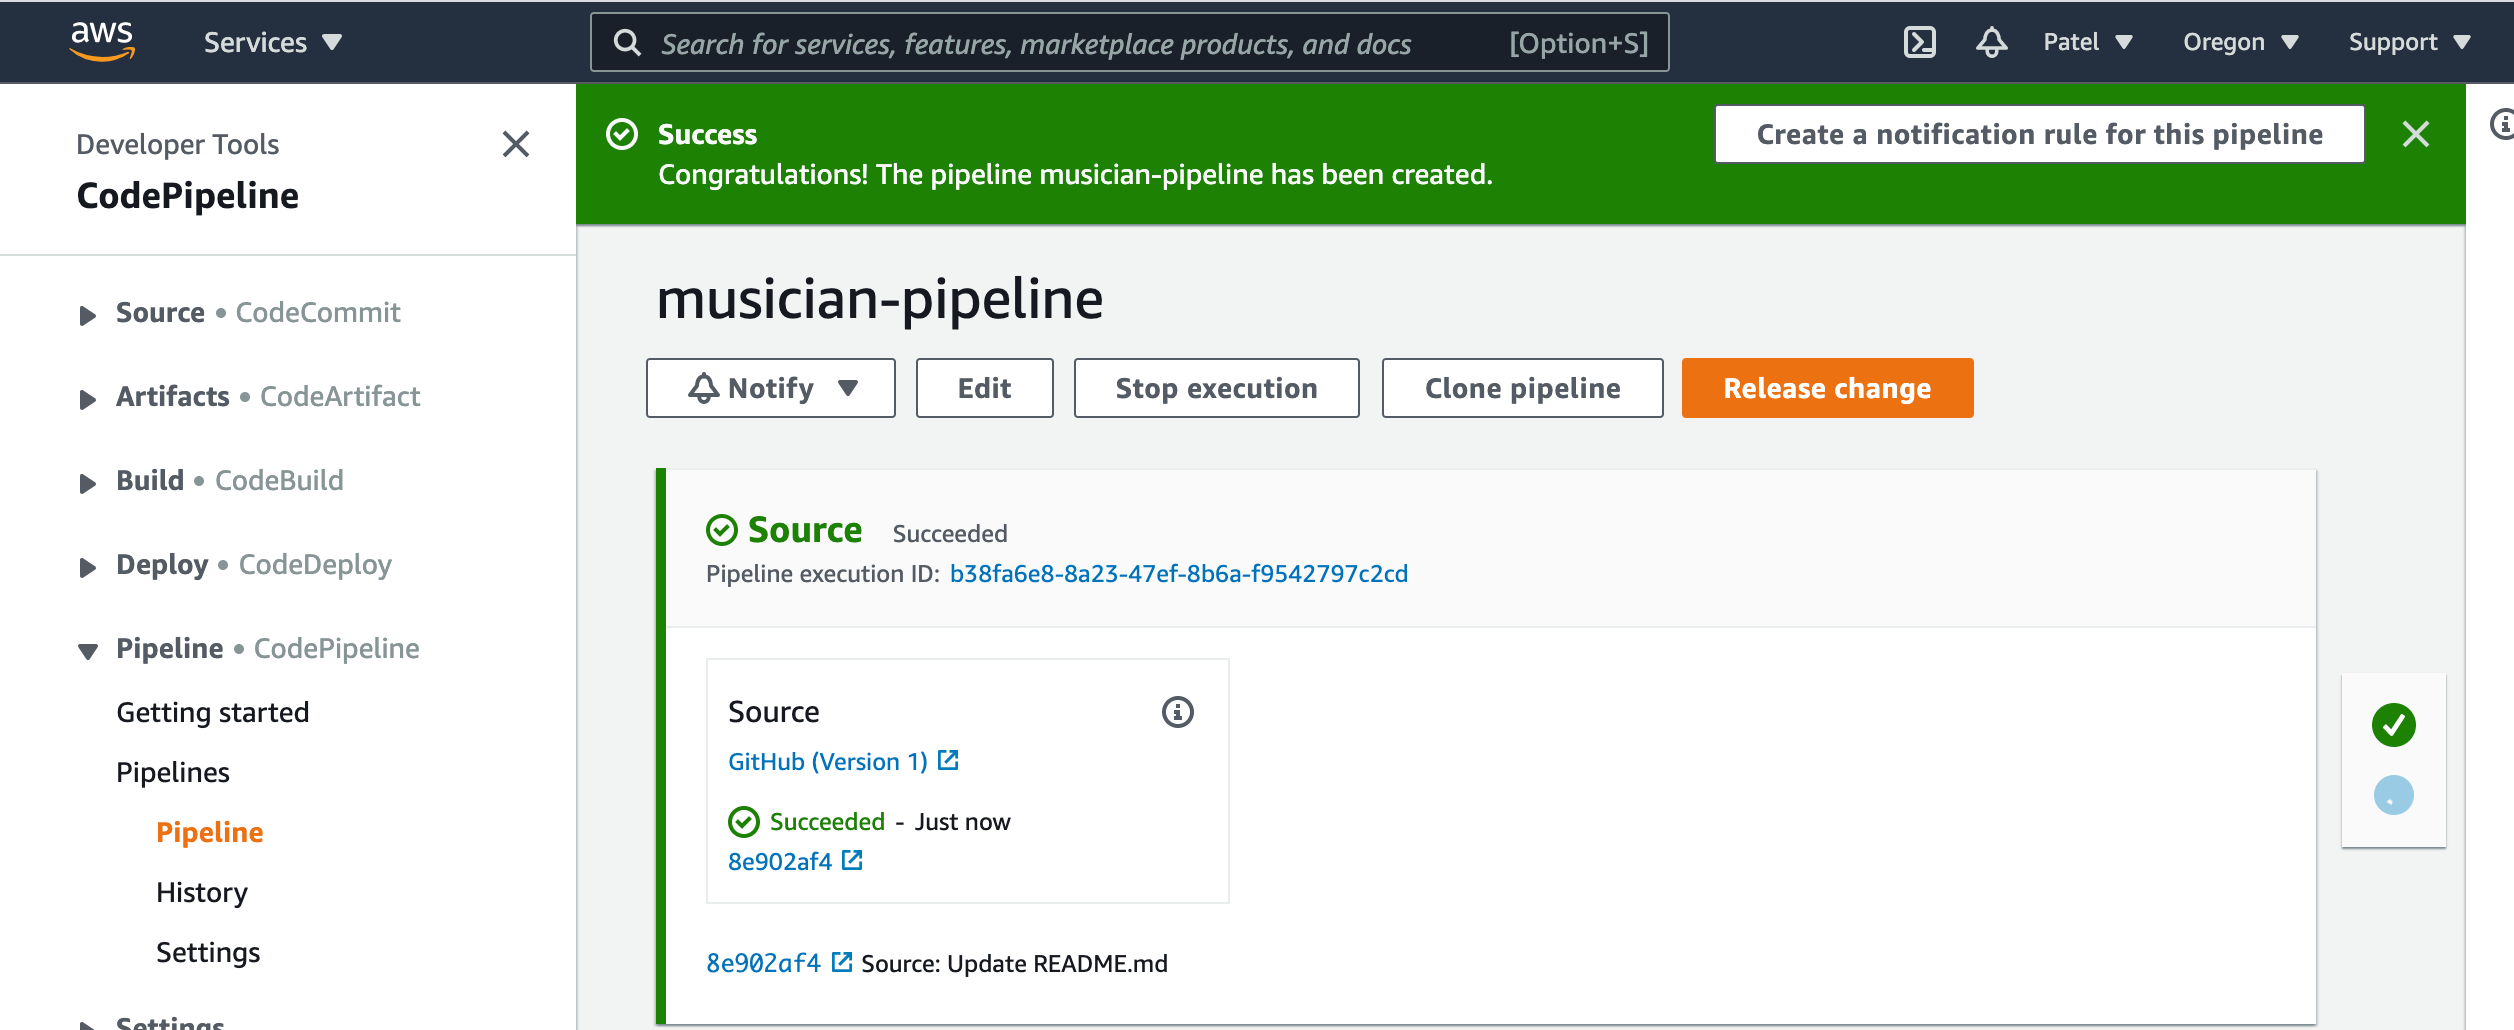
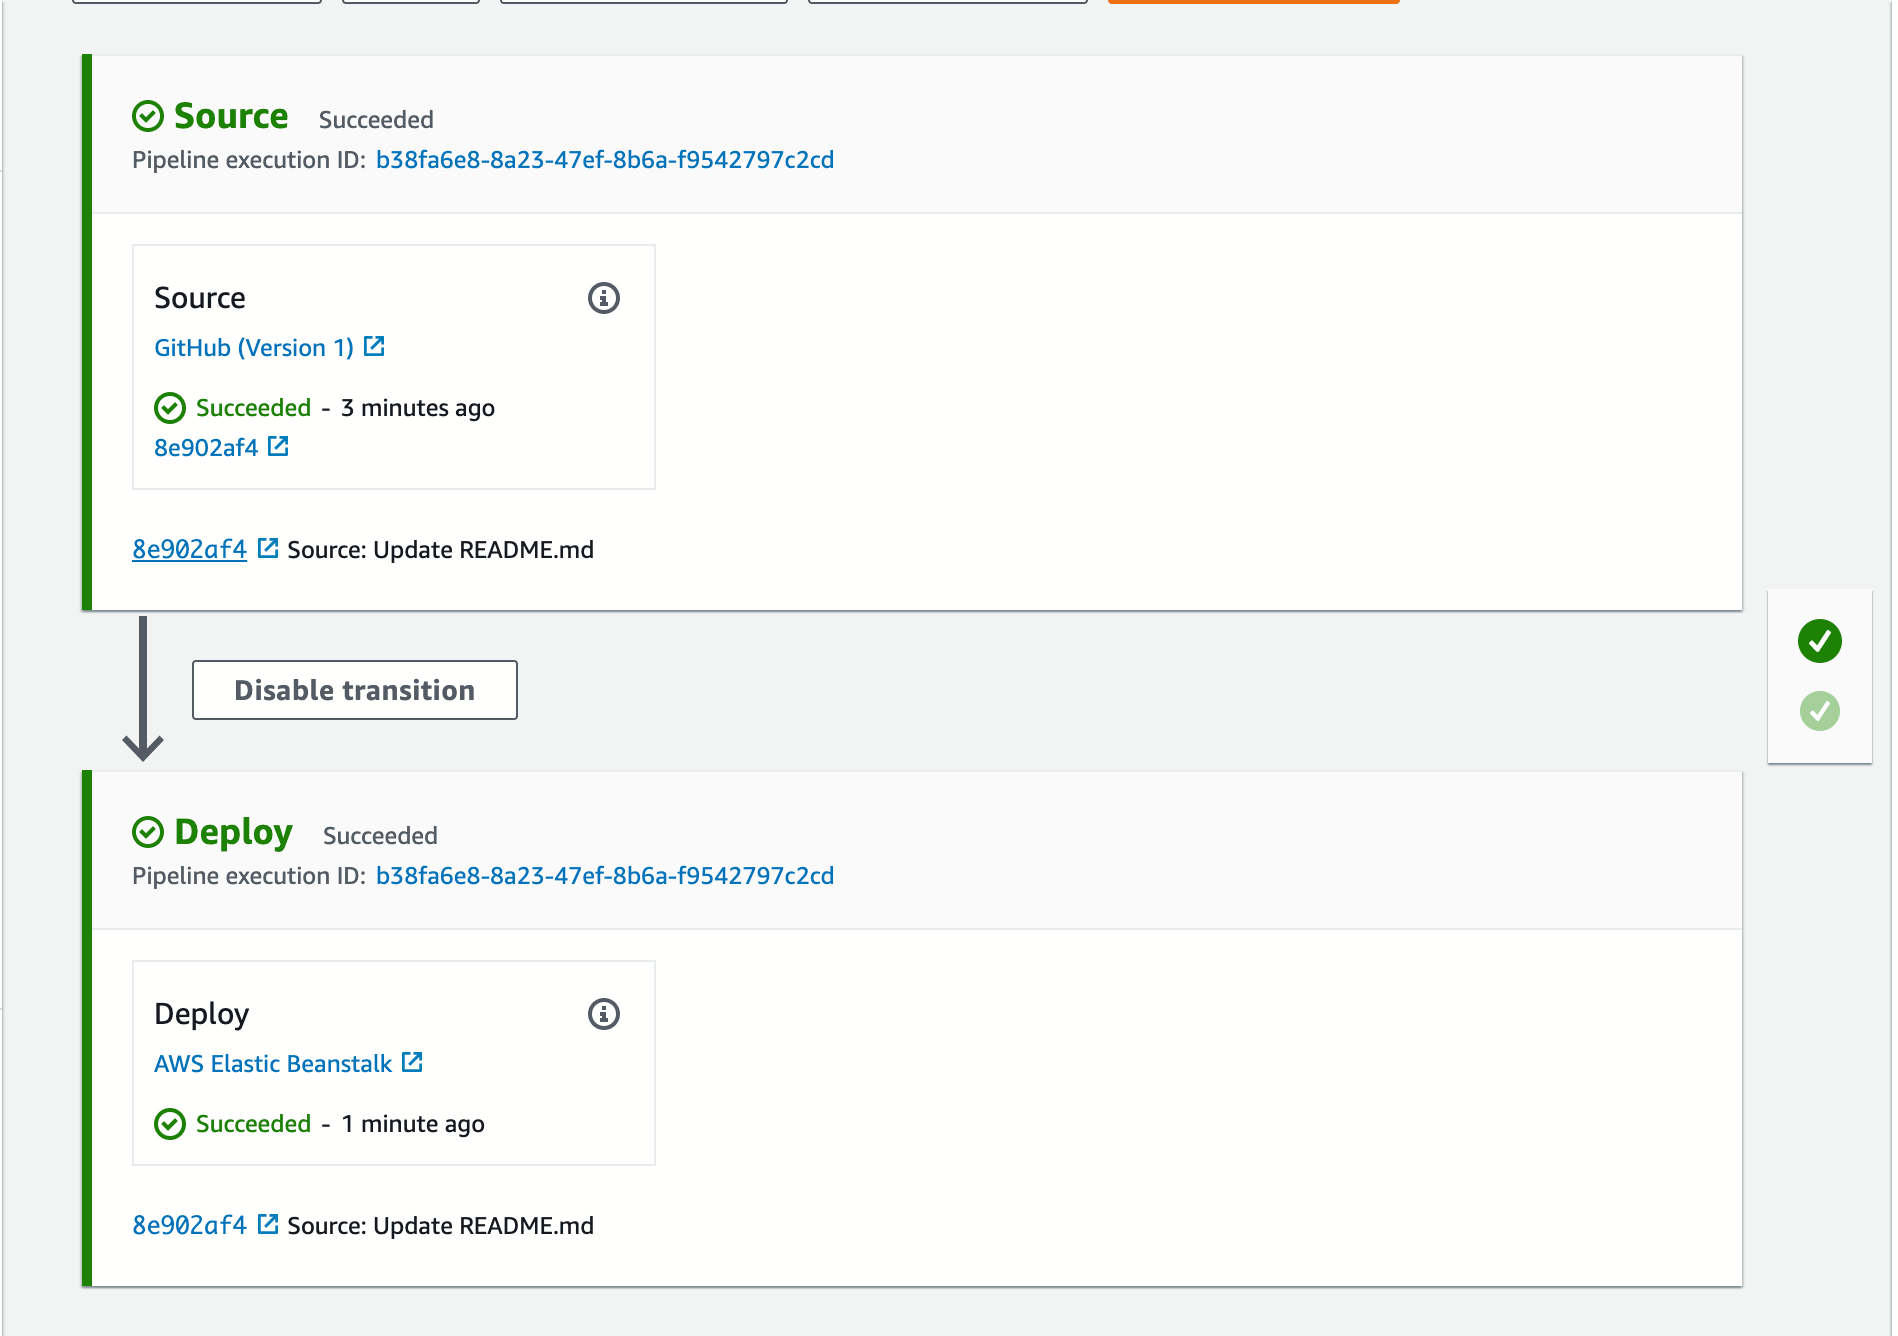
Figure 12: Pipeline View page

Delete Application

a) Login into AWS Account here and search for AWS Elastic Beanstalk service and open console.

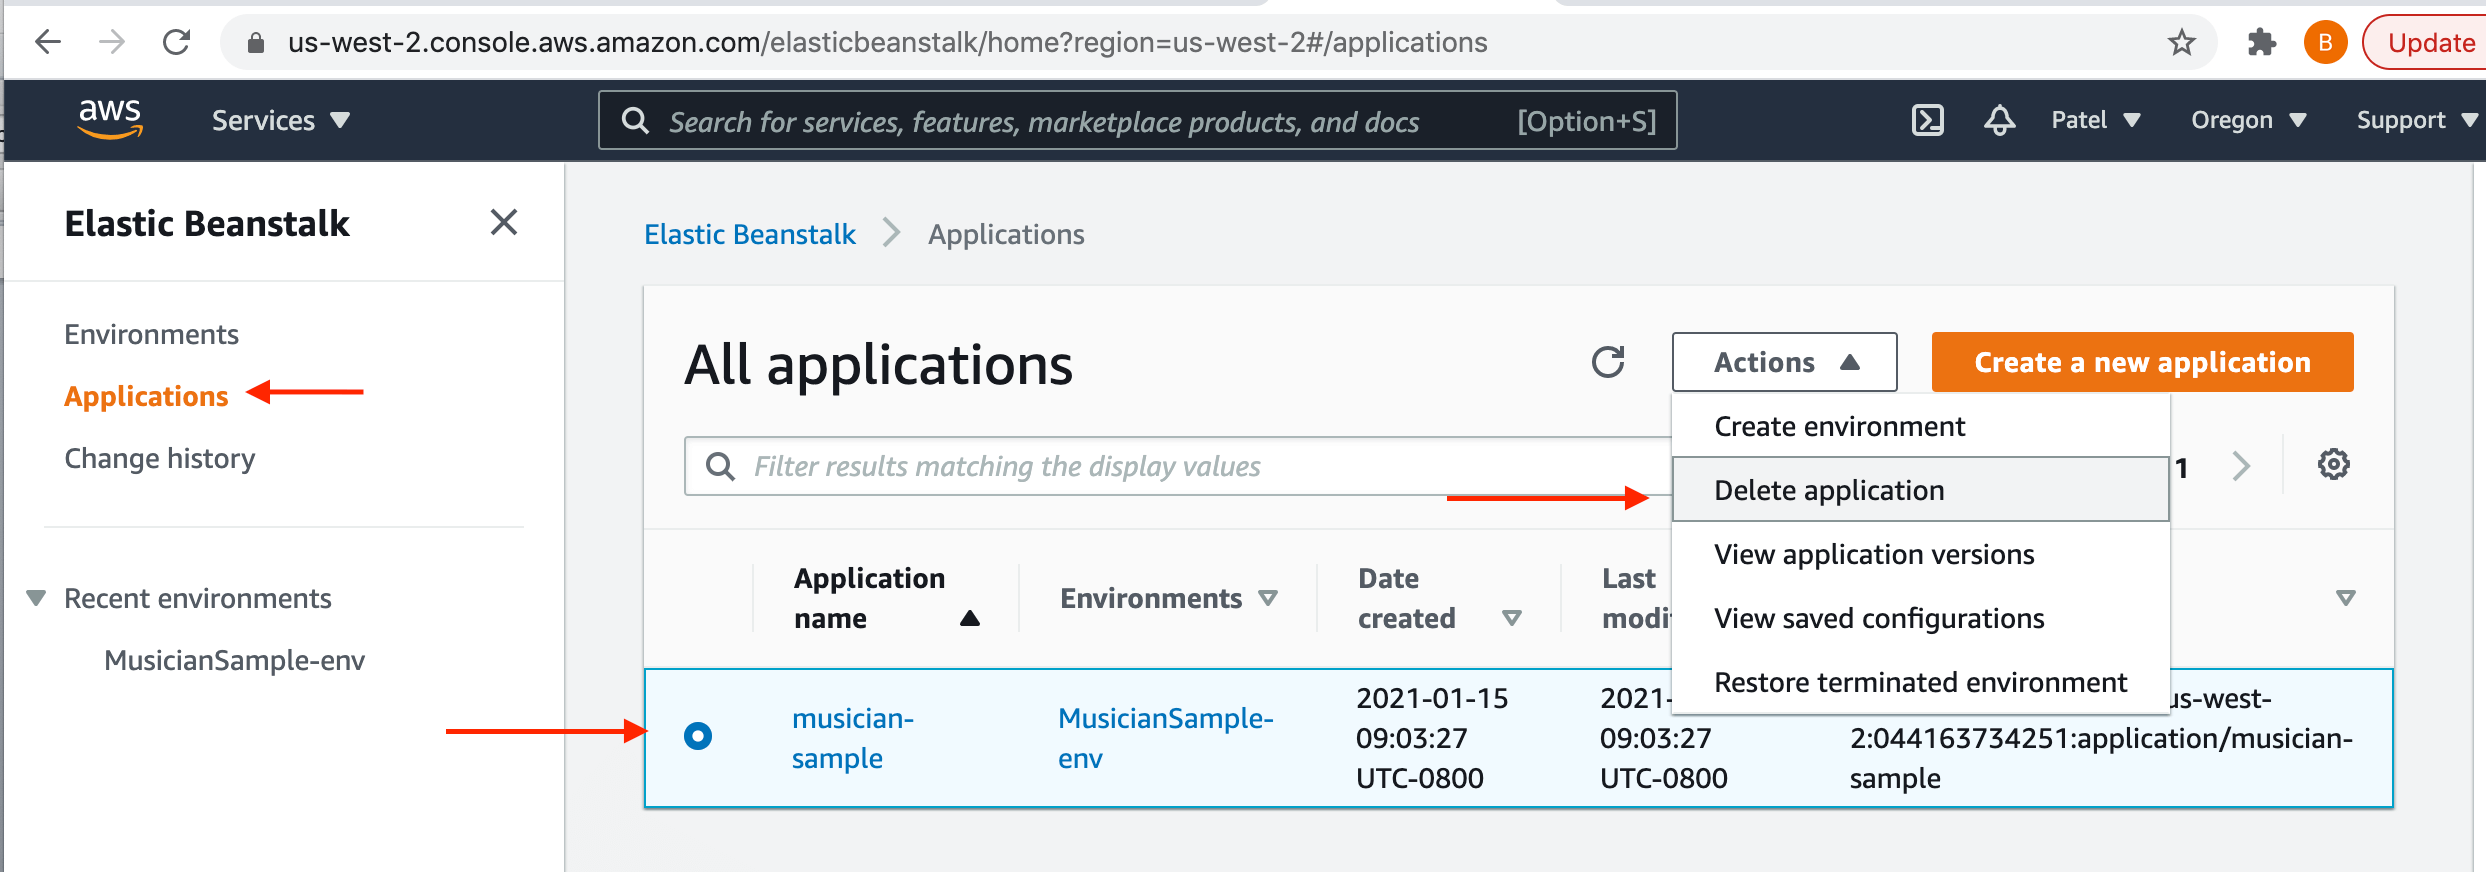
b) Select “Applications” .

c) Find your application name and select that you want to delete .

d) Select “Delete Application” from Action drop-down.

e) Turn on Delete version and select “Delete “ and “Done”.
Delete Environment

  1. Login into AWS Account here and search for AWS Elastic Beanstalk service and open console.
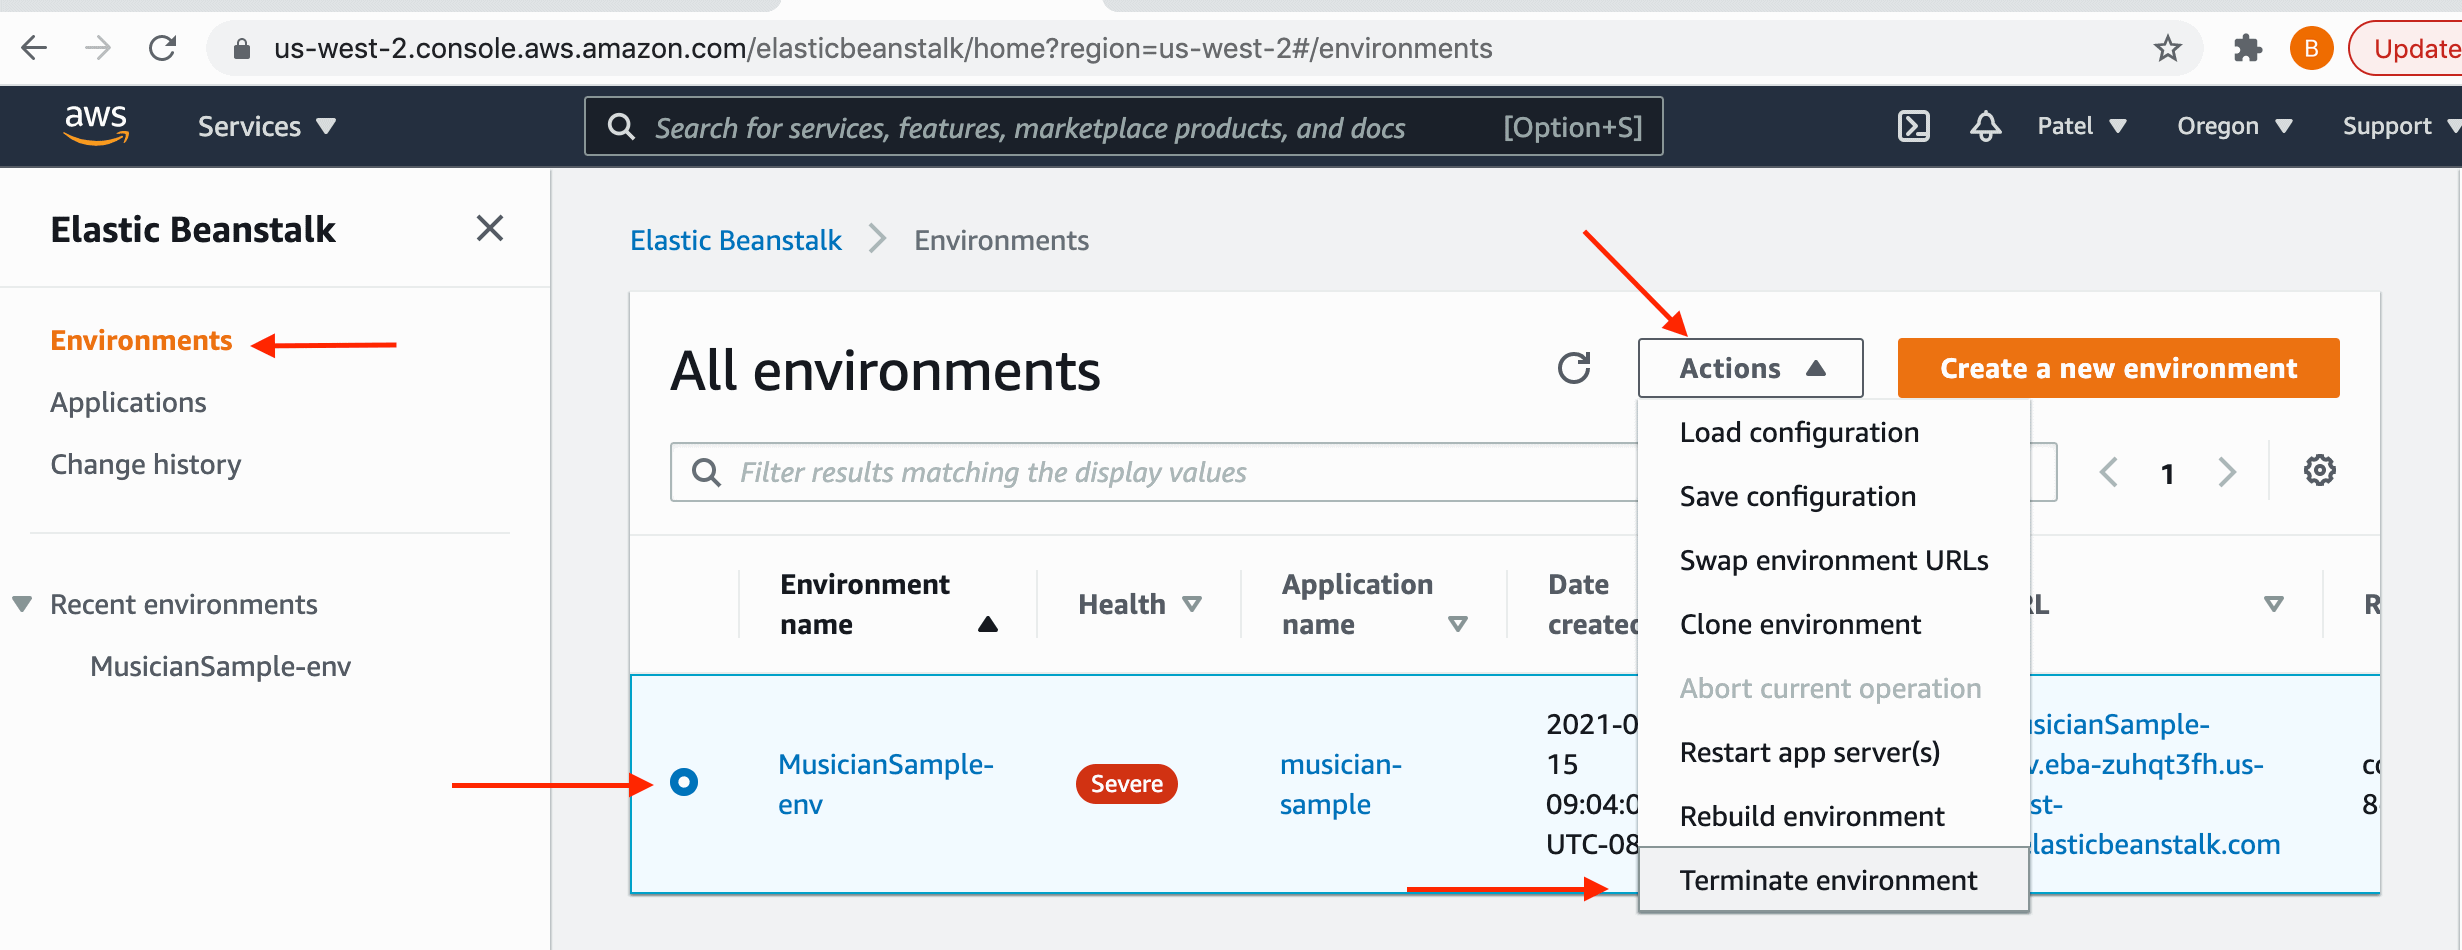
  2. In the Navigation pane on left choose “Environments” .
  3. In the Navigation pane, find your Environment name that you want to delete.
  4. Click on Environment “Action” drop-down and choose “Terminate Environment” button.
  5. Type Environment name and than choose Terminate .
How to start Pipeline Execution ?

When a developer makes changes to there code and pushed to a repository , the configured pipeline will detect changes and start execution. you can either trigger this pipeline execution manually by staring your pipeline or it can be automatically executed.

CI/CD Process

Before we tend to get to automated deployment to Elastic Beanstalk, however, it’s vital to refine the CI/CD pipeline for the cloud surroundings. Elastic Beanstalk is meant from the bottom up to be sturdy and climbable, therefore you’ve got to adapt your pipeline to totally leverage the benefits offered by the cloud platform. For starters, you’ll be able to standardized the event and preparation surroundings. A pipeline run should not be allowed to switch the surroundings as a result of extra runs can face difficulties in adapting to the new changes. Instead, the runtime should keep your surroundings clean.

Quality assurance and security checks got to be components of the method. For the pipeline to own shorter cycles whereas remaining reliable, these tasks got to be embedded into the progress. You’ll be able to keep your cloud surroundings safe by integration security into development.

Last however never least, confirm reviews and checks are performed before preparation. Scripts got to be checked against famed attacks and malicious scripts databases to form certain that dangerous line of code never get to the assembly surroundings.

The last half is very important. You’ll be able to assemble Elastic Beanstalk to expect bound flags or configuration entires before deploying a replacement update. As for integration the pipeline itself, the method is fairly simple with the tools that are currently on the market.

Benefits of CI/CD pipeline

Software Release Process can be Automated:

Continuous delivery provides a technique for your team to check-in the code that’s technically designed, tested, and ready for unharness to production in order that your software delivery is resilient, rapid and secure.

Increased in the Productivity of Developers:

CI/CD practices enhance your team’s productivity by releasing developers from manual tasks, acting on advanced dependencies, and returning focus to delivering new options. Rather than desegregation their code with different components of the business and outlay time on a way to deploy this code to a platform, developers will specialize in coding logic that delivers the options you wish.

Improving Code Quality:

Continuous Delivery will assist you to discover and address bugs within the delivery method before they grow into bigger issues later. Your team will simply perform extra varieties of code tests as a result of the complete method has been machine-driven. With the discipline of a lot testing of the complete method that has been iterated quicker with immediate feedback on the impact of changes. This permits groups to drive quality code with high assurance of stability and security. Developers can understand through immediate feedback whether or not the new code works and whether or not any breaking changes or bugs were introduced. Mistakes caught earlier within the development phase are simplest to repair.

Faster Updates Delivery

CD helps your team deliver updates to customers quickly and regularly. Once CI/CD is enforced, the velocity of the complete team, as well as the discharge of options and bugs fixes, is accumulated. Enterprises will respond quicker to plug changes, security challenges, client desires, and value pressures. For example, if new security feature is needed, your team will implement CI/CD with automatic testing to introduce the fix quickly and dependably to production systems with high confidence. What accustomed take weeks and months will currently take days or perhaps hours.

View Progress:

You will be able to review current status of your running application, checks alerts, failed actions, read details regarding the supply revisions utilized in the newest pipeline execution in every stage, and manually rerun any pipeline.

View Pipeline History :

You will be able to read details regarding executions of a pipeline, together with begin and finish times, run period, and execution ID’s.

Challenges of CI/CD Pipeline:

Security

The orchestration tool employed by the team ought to have an efficient security model that would offer higher visibility into the state of the complete CI/CD pipeline for example , to spot the causes of check failure, the team would need to examine the results of the check section. However they ought to not lean permission to switch or disable the configuration of that check step.

Managing multiple CI/CD pipeline

It would be troublesome to investigate metrics like turnouts, sure-fire execution, and cycle time if each pipeline ends at completely different stages within the delivery method. It’s easier to manage an outsized set of CI/CD pipelines if every one is predicated on a regular example. This may facilitate in purposeful comparative coverage and it will offer helpful feedback to boost alternative pipelines.

Limited dedicated Environments

Restricted shared check environment will increase the risks of a bottlenecks during CI/CD pipeline implementation. You’d have to be compelled to reserve associate degree surroundings to avoid multiple CI/CD pipelines running aspect by aspect from making an attempt to deploy and check within the same surroundings. One among the leading causes of readying failures is misconfigured environments changed by previous groups or check runs.

Summary

Continuous Integration and Continuous Delivery together is the fast and effective process of getting your product in market as well as releasing new feature and bug fixes to keep your current customer happy.

References

https://aws.amazon.com/


The post Deploying a NodeJS application from GitHub to AWS Elastic Beanstalk and creating a CI/CD AWS CodePipeline. appeared first on Simple Talk.


from Simple Talk https://ift.tt/3rgtScx
via

PowerShell editors and environments part 1

During the 2020 PASS Virtual Summit, a person tweeted something about how he wanted to scream at the next presenter who used the PowerShell ISE that comes with Windows. Several people leapt to the defense of that particular tool. In addition, during the live panel discussion on PowerShell, someone asked what would be the best editor to use. Between these two incidents, and my previous desire to write an article on moving from the ISE to Visual Studio Code, I thought it was time to write an article on the tools you can use to write PowerShell scripts, so this article covers PowerShell editors and environments.

I’ll start by saying that, most of the time, I still use the PowerShell ISE that comes with Windows, but I really should be moving to Visual Studio Code, and, in this article and the second part, I’ll explain why I should but also why I haven’t.

Editing versus running

Before I go too deep into this article, I want to distinguish between editing a file and running it. I’m going to focus on editors here, but most development environments include a way to execute a PowerShell script or PowerShell commands. However, do not confuse the editor with the execution environment.

Notepad

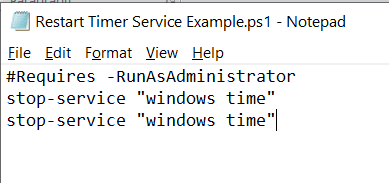
The simplest tool one can use to write and edit PowerShell Scripts is Notepad. A PowerShell script is basically a text file that is interpreted when it’s run. If no other tool is available on the machine you’re on, Notepad is almost certainly there. That said, it only allows you to edit a file, you can’t actually execute your file. You have to save it and then execute it using another tool such as the PowerShell shell.

powershell code in notepad

This script is valid PowerShell, and I could edit the file, for example, replace the name of the service if I wanted, but I can’t do more than simple editing. For a quick and dirty edit, this may be all that is needed. In my experience, it is the fastest way to open, edit, and then close a file, but that’s about the only real advantage. If I want to run this script, I still need to have an execution environment.

PowerShell shell

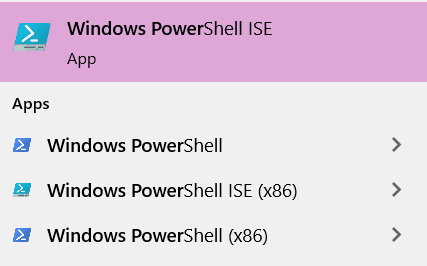
If you go to your start menu and enter Windows PowerShell, you should see something like the following:

list of PowerShell editors and environments

In this case, select the second choice: Windows PowerShell.

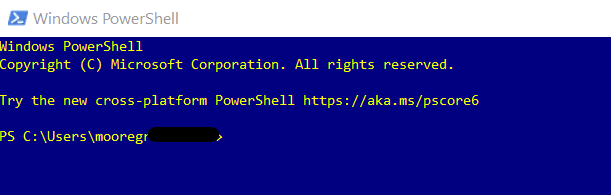
This action opens a window that looks similar to the following:

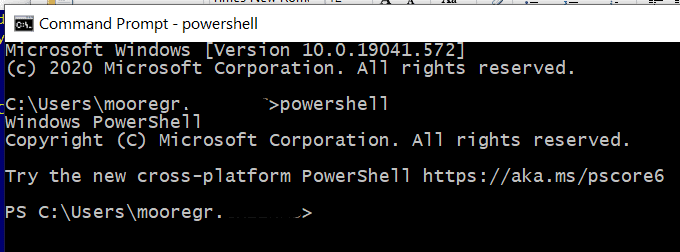
The window looks a lot like a standard CMD window, but with the addition of PS before the prompt. You can also get here from a CMD window itself by typing PowerShell in the CMD window.

Other than the color, these are the same. You can type PowerShell Cmdlets into either one and execute them, or even run actual PowerShell scripts.

However, you can’t edit a PowerShell script here. The window is only the CMD line for PowerShell.

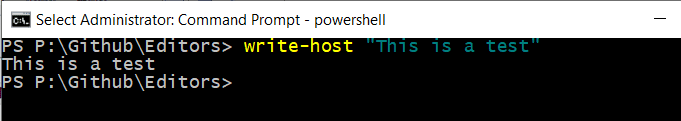
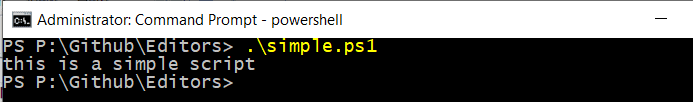
To execute a cmdlet, you can simply type it:

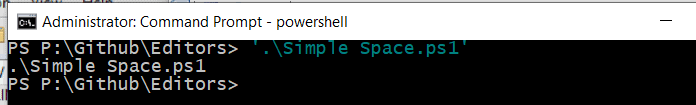
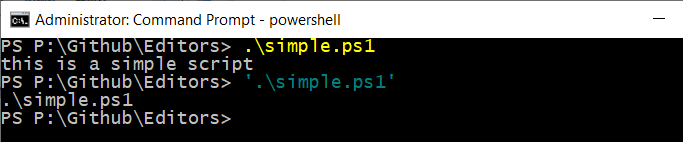
To run an actual script, you need to tell PowerShell the string you’re giving it is the name of a script to run, not a string to echo back.

Note here that PowerShell takes the passed string and echoes it back.

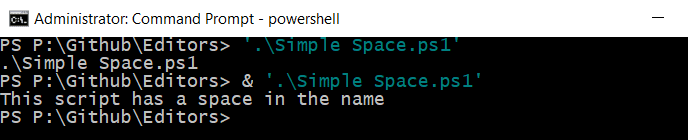
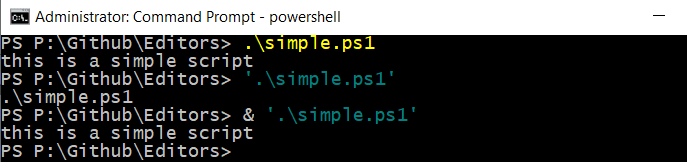
To force PowerShell to execute the string in quotes, start with an & symbol:

The & causes the script to be executed.

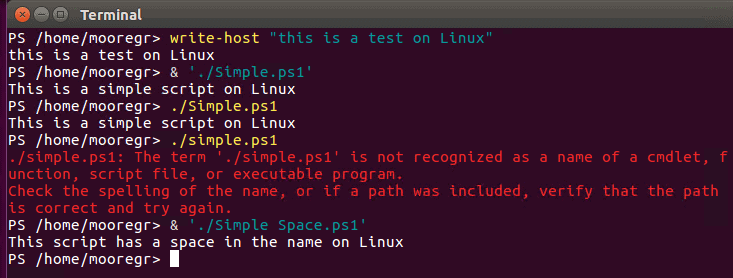
Note, however, if the script has no spaces in the name, you don’t need quote marks. As a result, PowerShell attempts to execute it:

If you do put quotes around it, PowerShell treats it as a string.

Generally it’s safer to use the & symbol, which is also known as the call operator

Note that in the PowerShell Command Line, generally auto-completion works as you might expect and will intelligently try to insert the & and quotes as needed if it can find a script in the directory that matches what you type.

One last tip: if you already have a CMD window open, you can start the PowerShell shell by running the command powershell. This command gets you to the shell the same way as if you had done it via the GUI.

Linux

One of PowerShell’s wonderful features is that you are not limited to running it only on Windows. You can, of course, write scripts and execute them on Linux. In the examples below, I am running Ubuntu Linux, but this should work for other distributions of Linux also.

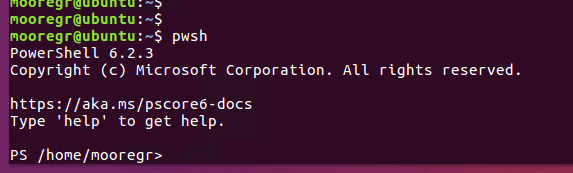
Whereas the command on Windows to open the PowerShell shell is PowerShell, on Linux it’s pwsh:

You can run most PowerShell scripts and cmdlets on Linux just like you would in Windows. However, some scripts or cmdlets such as those that make calls to the Windows GUI or Windows specific concepts will obviously fail. For example, get-services can’t run on Linux, but get-help will.

Another important detail is that Linux is case sensitive, as seen in the examples below:

Note that simple.ps1 and Simple.ps1 are not treated the same on Linux like they would be under Windows.

While Linux won’t have Notepad like Windows, you should be able to find VIM or a similar text editor available in your distro.

PowerShell ISE

A comment about this the PowerShell ISE prompted this article. The PowerShell ISE is the PowerShell Integrated Scripting Environment. Despite it being disparaged by some, honestly, it’s my go-to tool most of the time. Let me start by saying what it is not and why it is often disparaged: it’s not a modern IDE. Most of all, I would say what it lacks that I would look for the most in a modern IDE is tight control with some sort of source control system such as git. This limitation is not a show-stopper since you can still use git and other source control systems via the command line, but it can be inconvenient.

That said, an advantage of the PowerShell ISE is that you will almost certainly find a copy of it on every Windows computer where you might run PowerShell Scripts. It is not available on Linux.

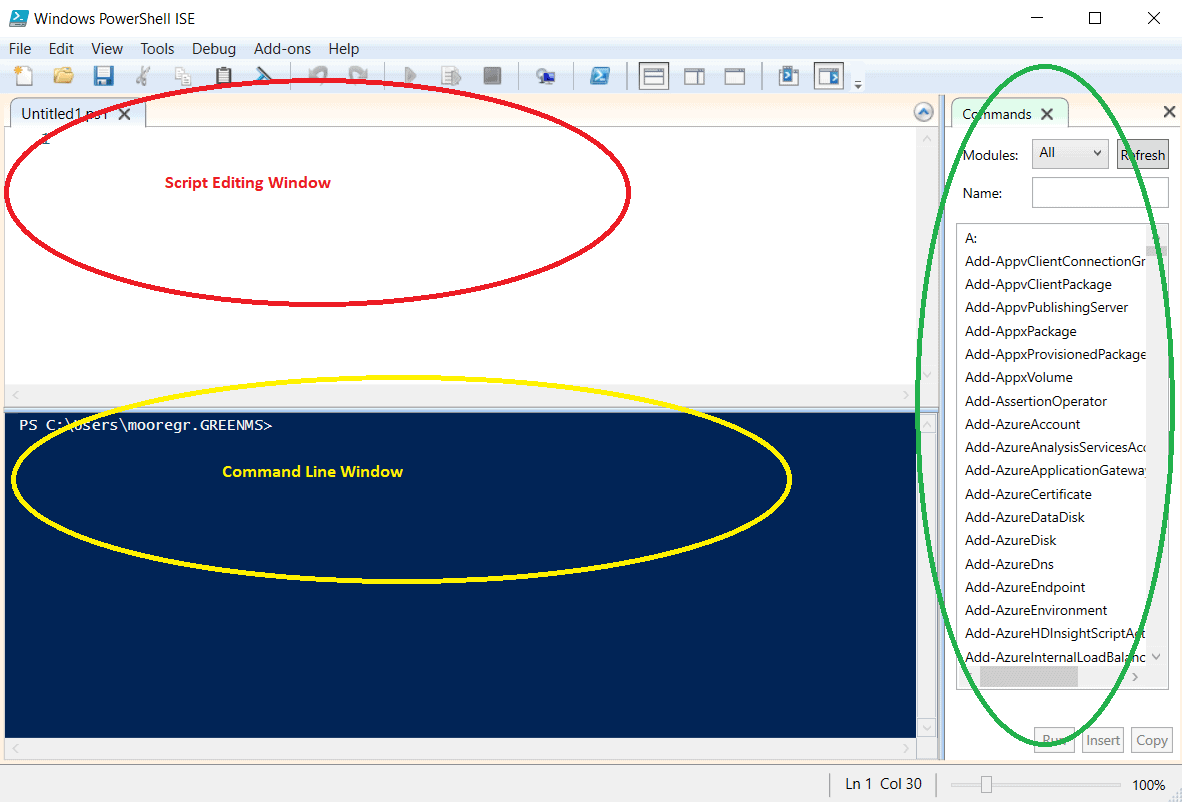
There are three main parts to the PowerShell ISE. The most obvious one is the largest, the Script Editing Window. This window is where you can open scripts, edit them and even run them. In the screenshot below, it’s the large white area with the red circle and text. In this case, PowerShell ISE has just been opened and is ready for creating a new script. By default, it is titled Untitled1.ps1. To open another window, press Ctrl-N. This action creates a new window called Untitled2.ps1, and so on. The file menu allows you to open and save files.

Below this window in the default layout is the command line window. This window operates very similarly to the PowerShell shell described above. It has one important addition that I find very helpful that I will describe in a bit.

Finally, a help window is found to the right of both windows. This windows shows installed cmdlets and allows searching for them and to get additional help. This functionality can be quite useful at times.

PowerShell ISE

Script editing window

This section is not meant to be a full tutorial on all the PowerShell ISE features, but I wanted to call out a couple of important features.

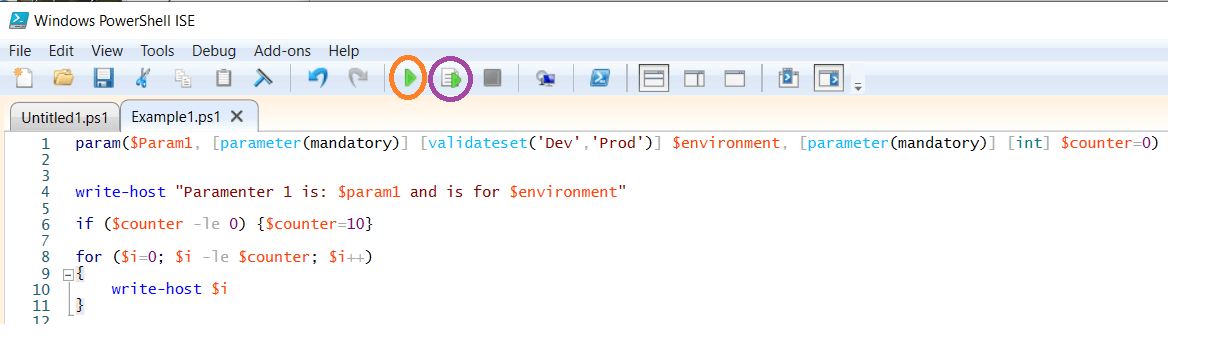
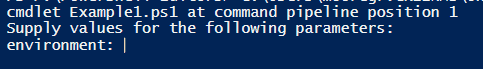
There are two icons with a green arrow on them. The one circled in Orange runs the entire script in the current edit window. If there are mandatory parameters, you are prompted for them. If a parameter is not mandatory, you will not be prompted for it and cannot provide a value when running it this way.

Pressing F5 performs the same action; this is your basic run command.

However, if you highlight just a portion of the script and press the button circled in purple, or press F8, it runs ONLY the lines highlighted.

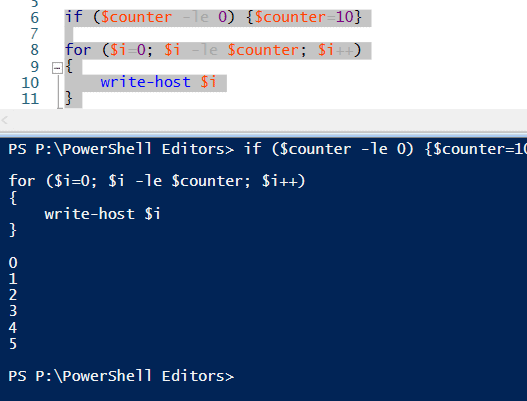
Now note, that in the ISE, variables remain in scope within the session. Since the last time I ran this script I had given $counter the value of 5, it remembered that for this script scrap.

This behavior can be confusing but also useful.

Using this ability to run only a portion of your script, and the fact that variables remain in scope and valid during your session can be convenient when debugging. However, it can also mean that sometimes you get unexpected results if you aren’t keeping track of what you last ran and what value some variables may have.

Command line window

The command line window of the ISE has several useful features. You can execute simple scripts and cmdlets in it if you desire.

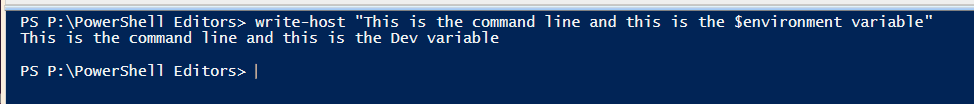
Notice this too will recall the last value of a variable.

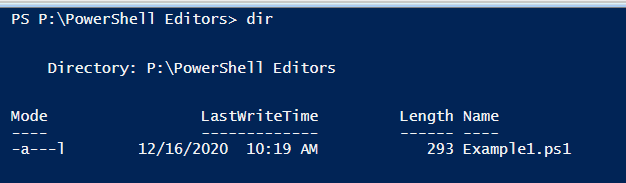
You can execute many CMD commands here, though many will be interpreted using a PowerShell native cmdlet.

That’s a dir command but acting much like the PowerShell cmdlet Get-ChildItem because it’s an alias.

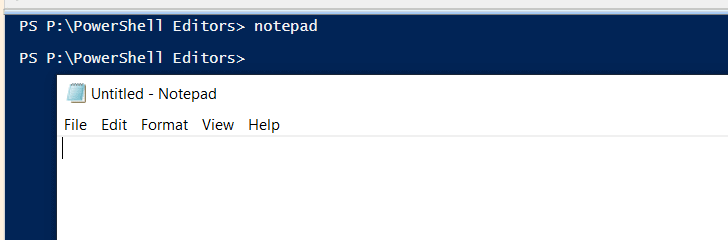
You can also start other programs in there.

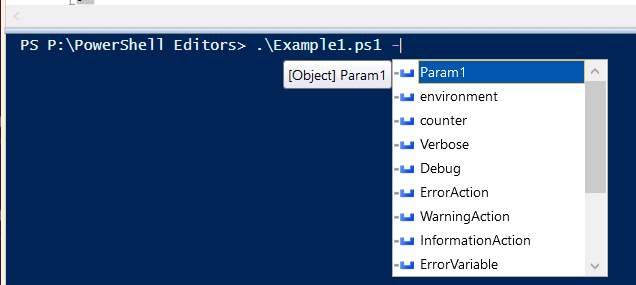
However, what’s most powerful about this window is the way it handles parameters for PowerShell scripts.

Notice that as soon as I press the key, a drop-down appears showing the available parameters. The drop-down window helps run a seldom-used script when I don’t recall the available parameters.

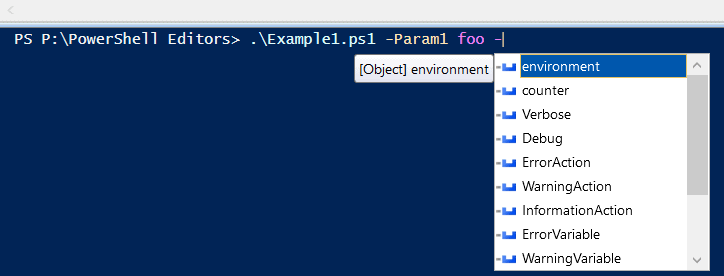
Notice that as you provide parameters, the available parameter list shrinks, only showing you the ones that have not yet been assigned a value. This behavior prevents you from entering the same parameter twice.

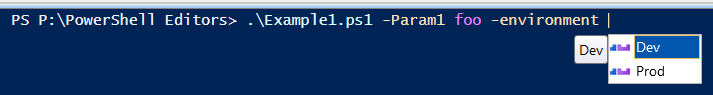
Finally, you’ll notice that the available options are shown if a parameter has a validateset. This means I’m far less likely to enter Development when I really need to enter Dev.

I mentioned above there’s a reason I still tend to use PowerShell ISE a lot and honestly, it’s because of this auto-completion. It’s a VERY handy tool and saves me a lot of time and effort when running seldom used scripts or initially debugging them.

Threads

One more area of interest in the PowerShell ISE is how it handles running multiple scripts at once.

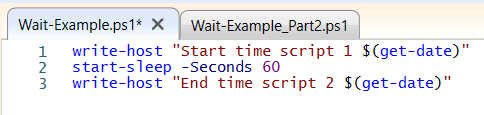
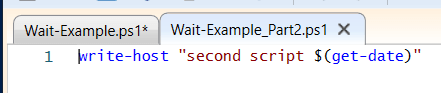
To demonstrate load the following two scripts:

Wait-Example.ps1 and Wait-Example_Part2.ps1 are both available at github for this article.

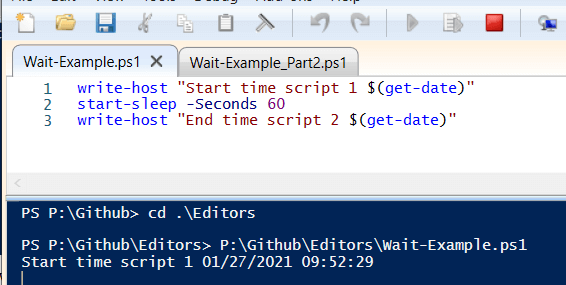
If you go to the first tab and press F5, it starts to execute. It sleeps for 60 seconds, giving you plenty of time to go to the 2nd tab and try to execute Wait-Example_Part2.ps1. However, you will find that you can’t.

The red box is a button to let you know a script is running, but you can also press that to abort a script’s execution. As long as the first script is running, you don’t have the option to execute the second script.

Normally, this is not an issue, but there are times when you may want to start a long-running script and do other work in the meantime. Fortunately, the PowerShell ISE offers a solution.

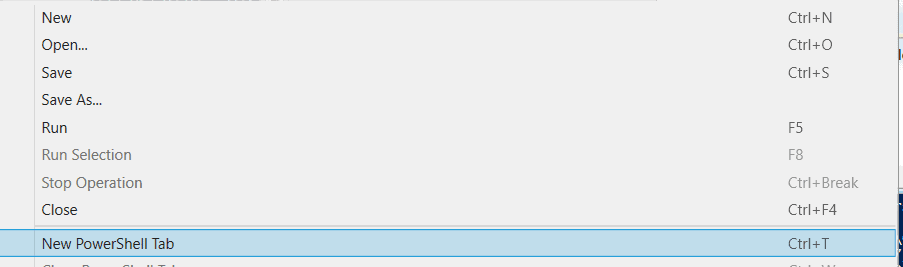
Instead of pressing Ctrl-N or using the menu to open a new PowerShell editor window, press Ctrl-T or use the menu to open a new PowerShell Tab

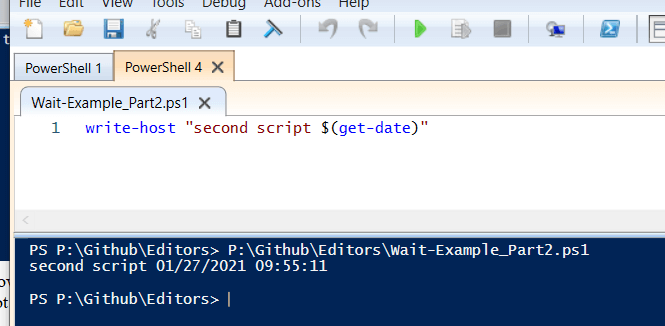
You will end up with a window similar to below.

Now you can execute a long-running script in the PowerShell 1 tab and continue working in your second tab (in my case it’s PowerShell 4 because I had previously opened two other tabs and then closed them).

Essentially, you’re running two instances of PowerShell at this point which can be very useful at times.

PowerShell editors and environments

More can be done in the PowerShell ISE such as opening a remote window or debugging, but this should be enough to get you started. As I mentioned, it’s not a full-fledged modern IDE with git support and other features, but honestly, it’s often good enough for what it does. I would not look askance at anyone for using it for demos and quick scripting needs.

That said, there are other tools out there, and in my next article, I’ll discuss those.

Until then, happy scripting!


If you liked this article, you might also like How to Use Parameters in PowerShell


The post PowerShell editors and environments part 1 appeared first on Simple Talk.


from Simple Talk https://ift.tt/3j9IyXW
via

Monday, February 1, 2021

Azure SQL and Managed Identity

Azure SQL has a close relationship with Azure Storage. Features like Polybase, backups, extended events and more make use of Azure Storage.

On Azure SQL Database, probably the most common use is Extended Events. When we create a file target, we need to point to the Azure Storage URL where the file will be stored.

Using Keys

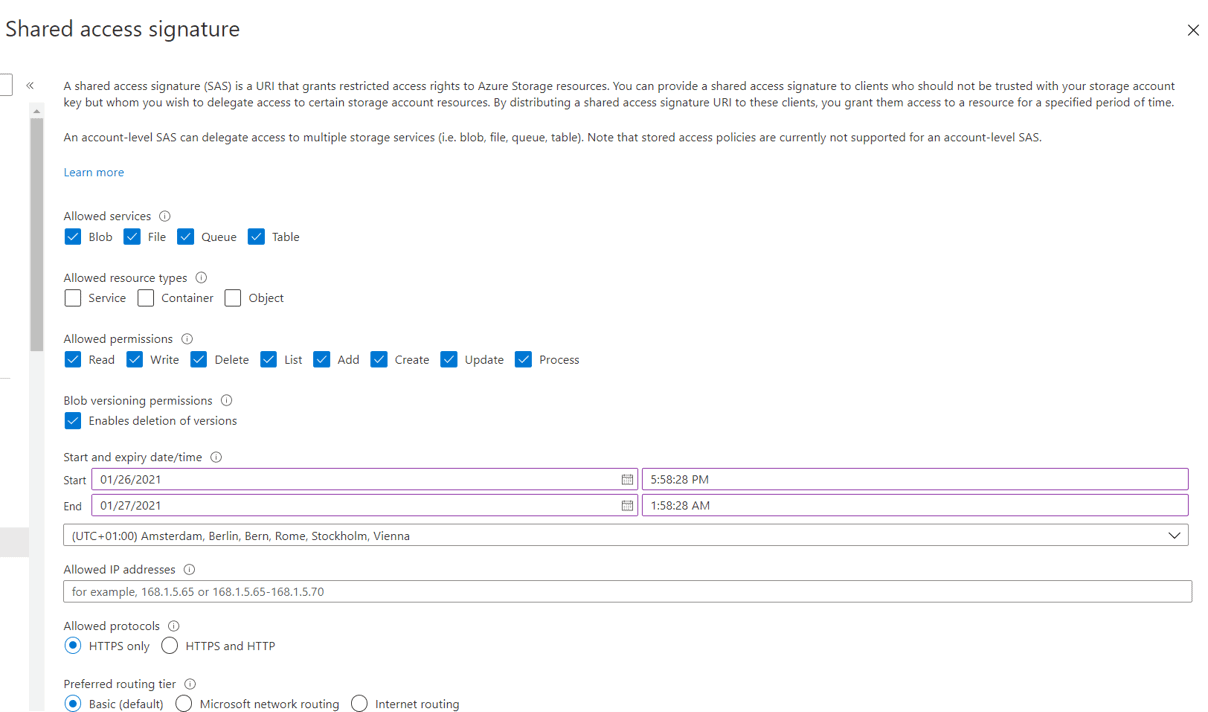
In order to access Azure Storage, we need to control the authentication. The most common way is to use credentials, creating a credential with the storage SAS key

. Graphical user interface, text, application, email Description automatically generated

Once we generate the SAS key, we create the credential object inside our database. For this we have Database Scoped a new feature introduced exactly for these situations, allowing us to create the credential inside the database, instead of at server level.

The statement to create the credential would be like this:

CREATE DATABASE scoped credential
[https://ift.tt/3crN6aZ] WITH IDENTITY
=‘SHARED ACCESS SIGNATURE’, secret =
‘sv=2019-12-12&ss=b&srt=sco&sp=rwdlacx&se=2021-12-30T20:03:34Z&st=2021-01-22T12:03:34Z&spr=https&sig=kMj8oq7bKderywanUcYN9vE3ebx0GxOaj3N7NU%2BMdgE%3D’ 

The Identity value is fixed, to identify the kind of key we are using, a SAS key. The name needs to be the URL to the container, but not always, it depends on what feature will be using this credential.

Some more recent features are prepared to use credentials, receiving the name of the credential as a parameter. In these cases, the credential can have whatever name we would like.

However, older features, such as Extended Events, are not prepared to be linked to a credential. This is solved by ensuring the credential name has the same name of the path used by the feature. In this way, SQL Server identifies which credential should be used for that access.

Avoiding Keys

This method ends up spreading SAS keys all around. We can’t really tell this is unsafe, since the credentials are kept encrypted using the SQL Server encryption system, but it would be better if we could make the authentication without directly using a key or password.

That’s what we can achieve using Managed Identities. Each service on Azure can have its own identity registered with Azure Active Directory. Once the identity is stablished, we can use Role Based security (RBAC) to set permissions for the service, avoiding the use of passwords or keys.

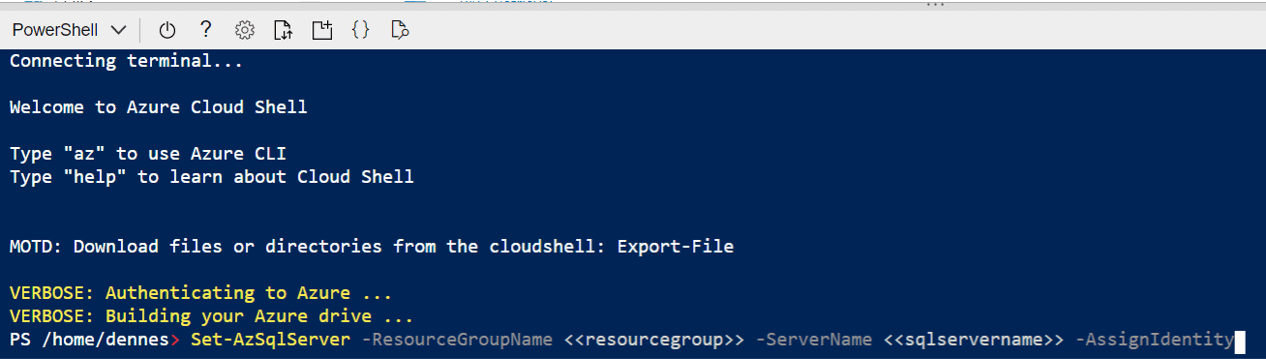
Azure SQL Database doesn’t have a control on the UI to set the managed identity, but we can easily do it using PowerShell in the cloud shell on the portal.

Graphical user interface, text, application Description automatically generated

The statement to set the managed identity is like this:

Set-AzSqlServer -ResourceGroupName <<resourcegroup>> -ServerName <<sqlservername>> -AssignIdentity

Setting Identity Permissions

Once we execute this statement, the server gets an identity, and we can use this identity to control the access to the Azure Storage. The next step is to give permission to this identity.

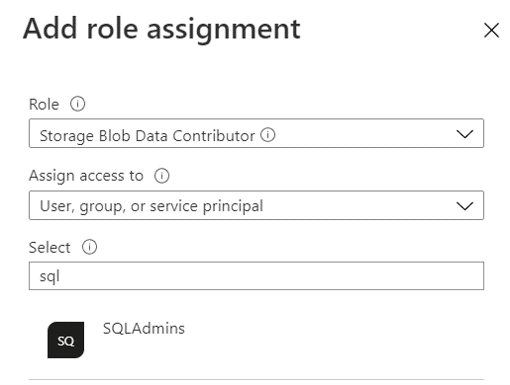
When dealing with RBAC permissions it’s important to mind there are two kinds of permissions: Object permissions, for managing the object, and data permission, to access the data within the object. In this case, we need the data permissions, so SQL Server will be able to write the extended events file to the blob storage. We can set the Managed Identity with the permission Storage Blob Data Contributor, which is different than Storage Blob Contributor.

On the storage account, we access the tab Access Control (IAM) and click the Add button. A new window will open, where we configure the identity and permission. The permission is set on Role dropdown, we just choose it. We type on the Select text box to filter the identities. The Manage Identity will have the same name as the SQL Server we created. Once found, we select it and complete the creation of the role assignment.

Graphical user interface, text, application Description automatically generated

Next step is creating a credential in the database to use the managed identity. This time we don’t have a secret for the credential, we only define the type of Identity we will use:

CREATE DATABASE scoped credential
[https://ift.tt/3crN6aZ] WITH IDENTITY
= ‘Managed Identity’; 

Creating the XE Session

This is only an example of an Extended Events session pointing to the blob storage. It will use the credential to authenticate and, in our example, will be using the SQL Server Managed Identity.

CREATE EVENT SESSION [queries] ON DATABASE
ADD EVENT sqlserver.sql_statement_completed(
ACTION(sqlserver.client_app_name,sqlserver.client_hostname,sqlserver.context_info,sqlserver.database_id,sqlserver.database_name,sqlserver.username)),
ADD EVENT sqlserver.sql_statement_starting(SET collect_statement=(1)
ACTION(sqlserver.client_app_name,sqlserver.client_hostname,sqlserver.database_id,sqlserver.database_name,sqlserver.username))
ADD TARGET package0.event_file(SET filename=N’https://ift.tt/3oHtUIG;)
WITH (STARTUP_STATE=ON)GO

Conclusion

Managed Identities can make our cloud environment safer, removing keys and passwords from our control.

The post Azure SQL and Managed Identity appeared first on Simple Talk.


from Simple Talk https://ift.tt/3pE7AkA
via