Friday, January 17, 2020

Speaking at Nashville SQL Saturday this weekend

Boy does time fly, and it is already mid January. The holidays flew by, and now the Christmas tree and (most of) the Christmas décor has been boxed up in the attic (yeah, there is a Santa on a shelf staring at me that he needs to be put up!). The college bowl games are over, rendering all college teams a blissful 0-0 record again, and in the SQL Server community area, one of the very first events is upon us: SQL Saturday Nashville.

This year, I am speaking in the first slot at 8:30, talking out that favorite topic of mine: The fundamentals Relational Database Design. Even if you are not going to be building databases and are just writing code to use them, understanding why the data architect gets really grumpy when a database has 2 tables with 1000 columns each (even though it “gets the job done, I suppose”) will at least let you know the issues you might run into with less than optimal designs.

I have been doing a variation of this presentation for 20 years, and while the reasons to build a relational database a certain way haven’t changed, a lot has changed as to why it is so important to at least understand the basics. The amount of data being stored, even for simple transactions, has skyrocketed over the years, and businesses are looking for more information from their data than just knowing that a product was shipped, and that we got paid for it. The big question people want to know is “how do we get them to do it again with the least amount of effort?” To do that calculation, the better the data, the easier the calculation.

The abstract for the presentation is:

Data should be easy to work with in SQL Server if the database has been organized as close as possible to the standards of normalization that have been proven for many years, but are often thought of as old-fashioned. Many common T-SQL programming “difficulties” are the result of struggling against these standards and can be avoided by understanding the requirements, applying normalization, as well as a healthy dose of simple common sense. In this session I will give an overview of how to design a relational database, allowing you to work with the data structures instead of against them. This will let you use SQL naturally, enabling the query engine internals to optimize your output needs without you needing to spend a lot of time thinking about it. This will mean less time trying to figure out why SUBSTRING(column,3,1) = ‘A’ is killing your performance, and more time for solving the next customer problem.

Of course, all of this is a very tall order for an hour, and when I did this as a webinar for SentryOne with the fabulous Kevin Kline as my color commentator, it took about 2 hours, over two sessions (the second one is here). So come to see it live, or check it out on your own pace because you had rather go see Monica Rathbun talk about performance. Hey, if you build tables and don’t care about the right way to design a relational database is probably a good idea anyhow. Though I do expect one of her items might be (don’t do a crappy job designing in the first place!)

Hope to see you there!

The post Speaking at Nashville SQL Saturday this weekend appeared first on Simple Talk.


from Simple Talk https://ift.tt/2QXzVDx
via

Thursday, January 9, 2020

Capturing a Mind

When the Netflix series Black Mirror began in 2011, I watched a few episodes. Recently, I “binge-watched” more to catch up. If you’re not familiar with the series, each episode is about technology, and how people must deal with it when it goes awry. For the most part, the technology featured in the series doesn’t exist…yet.

One episode from 2016, Nosedive, is almost too close for comfort. As people interact, they give each other ratings much like giving an Uber driver or passenger a rating today. A person’s rating determines how others in society treat them and the opportunities that they have. Once a rating drops too low, it’s almost impossible to climb back up. The characters accept that whole situation is normal, and it is similar to how we have accepted the intrusion to our privacy from social media like Facebook today.

Since I was watching several episodes in one weekend, I noticed a theme: the ability to copy a person’s mind into a “cookie” that can interact with other people. In each case, the copy thought they were the real thing. In one episode, a scientist took a cookie from a convict as he was executed. The scientist then placed the cookie in a museum where tourists could execute the “man” over and over without eliminating him. This was terrible torture as he could feel the pain and agony each time.

In another case, a husband had the cookie of his comatose wife implanted into him. This allowed her to see and feel everything he experienced which was great for interacting with their son. You can probably imagine the problems that came up as the husband tried to live his life with this implant, and the husband eventually agreed to place her into a toy that their son soon abandoned. By the way, she ended up in the same museum as the convict.

Police used a cookie to extract a confession in one episode, and a software developer punished his co-workers by putting copies of them into a video game of his favourite TV show.

In each case, the real humans didn’t care much about the rights or experiences of the cookies, and the ethical and legal questions come up quite often. Is it legal to terminate a copy of a mind? Is it ethical to put a copy on pause or give it nothing to do for several months?

Even though this series is science fiction, I wonder how far away we are from achieving some of the technology featured. Capturing an entire mind does seem far off, but many things we accept today were science fiction not too long ago.


The post Capturing a Mind appeared first on Simple Talk.


from Simple Talk https://ift.tt/2ZZtdQm
via

Wednesday, January 8, 2020

But the Database Worked in Development! Preventing Broken Constraints

You’re working in development, releasing a new version of the application. You’ve temporarily disabled constraints in the new version of the database, you’ve imported the current data, your hand is poised to enable constraints. Is it going to spring errors at you? What if it does?

Or, what if you synchronize a source with a target by changing the metadata, only to find that the process has an error saying a constraint, index or foreign key can’t be created?

How could this happen? What has happened in both cases is that the data does not comply with the constraints. Maybe you’ve added or altered some constraints, and you have tested them on a different version of the data, changing this data slightly to satisfy the new constraints but without providing your changes as a data migration script. Perhaps you’ve only tested the new or altered constraints using an artificial data set, with no troublesome duplicates or broken references? Possibly, you are working in development and staging is done by a different team. Deployment and release are often, from necessity, done by a different team to development. You release the new database version to staging, which perhaps is managed by a different team, and when they try to update the existing database to the new build, the build breaks.

Often, at this point, one or other of the teams will need to repeatedly try releasing while fixing all the bad data, one error message at a time. This isn’t going to help team bonding; you need a better way of dealing with these problems.

In this series of articles, I’ll provide a more reliable way to be able to tease out all the duplicates, the broken foreign key references or all the values that will cause CHECK constraint errors, before you run a deployment. It will not only report where the errors would occur, but which data in which tables would cause which constraints to fail.

Dealing with Data that Breaks the Build

Sometimes a database build breaks only when you try to release it to staging or, worse, to production. Up to that point everything is sweetness and light. Then you either synchronise or try to load the data. What has happened? Well, it could be that in the new version of the databases, you’ve added DEFAULT constraints, FOREIGN KEYs or unique indexes, as you should, or modified existing keys and constraints to enforce referential integrity, and do a better job at preventing ‘bad data’ from creeping into the database.

If you are very fortunate, you will have access to the real data, so you can enable constraints one at a time and, when one causes an error, fix the data that is recorded in the error, and develop the scripts to heal the data in a pre-deployment script in order to remove the duplicates and bad data and fix the broken FOREIGN KEY references that initially inspired you to do the work.

There’s nothing wrong with that sort of data migration script, of course, although it requires a lot of careful work, gathering up all the de-duplicating statements, making them idempotent, testing them, and then using them in a pre-deployment script for a release. Even after all this, new data may have been inserted into Production, since you took the backup for testing, which might still break the build. If you are importing the existing data into a new build, then you would disable all constraints, import the data, heal it in-situ with the data-migration script and then finally enable constraints.

What, though, if you can’t access the production data, for several good reasons? In this case, you’re most likely testing with an artificially generated set of data for testing or a masked copy of the production data. However, unless you are one of the wild men of IT, it isn’t the actual production data, and so doesn’t have all the real data’s failings. Now, either the Ops team will need to try to fix all the duplicates and bad data, until the build succeeds, or they will pass the baton back to you.

Unless you enjoy buying all the drinks on the Friday afternoon DevOps team meeting, you must never deliberately break the database build or release. What you need to do is to provide a way that the Ops people can check the data of the target database beforehand to make sure it will pass all the checks done by constraints and unique indexes, and that all the FOREIGN KEY references are in place. If it doesn’t, and this is the key difference, they will need a report of what data failed the new constraints, so that you can provide scripts to allow DevOps people to fix the data.

When you know what is failing, you can create the deduplication, broken FOREIGN KEY reference or data-sanitizing scripts. Then you re-test until you get a clean bill of health. Although I can’t really help with the actual de-duplication, I can, in this article, help you to generate the list of the constraints that will fail and why.

Duplicates

Duplicates are like rats: they get in unless you take active steps to stop them. Data just seems to want to reproduce itself. The grey-muzzled database developer will take elaborate steps to check for duplicates everywhere by using unique constraints, whilst the cub developers snigger amongst themselves at how impossible it would be for a duplicate to get in there anyway. The blighters always insinuate themselves wherever there are no checks against them. Duplicates, I mean, rather than cub developers. This means that every database revision seems to have more uniqueness checks, inspired by the labour of teasing duplicates out and stamping on them. If the production data has duplicates, this must be fixed before you can release new unique constraints successfully to that target database.

Constraints and Bad Data

However often I go on about CHECK constraints, there will always be a developer who will leave them out or mutter in a dignified manner about how all checks need to be done only at the application level. This attitude soon gets divine retribution. Bad data springs up like a rotting fungus over your database unless you add CHECK constraints to all your tables. This is fine but then how do you prevent the excellent and estimable habit of adding them to then interfere with a release? The constraints will stop the build if they meet bad data: it is what they are trained to do. If you don’t like that, then you must fix the bad data first.

Unreferenced Foreign Keys

These are less frequent, but I’ve seen them. What happens here is that you import your data, enable constraints, and you get a message about a foreign key reference. This happens if, for example, the name of a country that is referenced in an address list or currency table is missing. Getting data right in a referenced table can be like picking up lots of tadpoles and putting them in a jar. Unless you know what failed, this can be very tricky to fix.

Checking the CHECK Constraints: First Principles

We’ll show how to do a check. The whole point of this type of test is that it must report the breakages in enough detail that you can smilingly pass to the Ops Guy a script that will heal it.

Let’s do the very simplest check: a check of constraints. We’ll do this by assembling a batch as a string. This batch will execute every constraint in the database, on the table to which it belongs, and tot up the grand total of rows that failed a constraint.

DECLARE @AllTheFailures INT; --tally of all the 
   --failures in the constraints
DECLARE @CheckAllYourConstraints NVARCHAR(MAX) = 
   'Select @RowsFailed =0;
';
SELECT @CheckAllYourConstraints = 
   @CheckAllYourConstraints --accumulate each query
  + N'
    Select @RowsFailed=@RowsFailed+count(*) from ' --the table spec
  + QuoteName(Object_Schema_Name(CC.parent_object_id)) + N'.'
  + QuoteName(Object_Name(CC.parent_object_id)) + N' WHERE NOT ' 
  + definition
  FROM sys.check_constraints AS CC
  WHERE is_ms_shipped = 0;
--Now we have a list of select queries that will accumulate 
--the total number of rows that fail the condition
EXECUTE sp_executesql @CheckAllYourConstraints, 
  N'@RowsFailed int output',
  @RowsFailed = @AllTheFailures OUTPUT;
SELECT @AllTheFailures;

We run this in our test copy of AdventureWorks2016. It returns no rows, because all the constraints are enabled and so the rows are already well-policed by those constraints if they are in a ‘trusted’ state.

The batch that was executed was this:

Select @RowsFailed =0;
Select @RowsFailed=@RowsFailed+count(*) from [Person].[Person] 
WHERE NOT ([EmailPromotion]>=(0) AND [EmailPromotion]<=(2))
Select @RowsFailed=@RowsFailed+count(*) from [Sales].[SalesTaxRate] 
WHERE NOT ([TaxType]>=(1) AND [TaxType]<=(3))
Select @RowsFailed=@RowsFailed+count(*) from [Sales].[SalesTerritory] 
WHERE NOT ([SalesYTD]>=(0.00))
Select @RowsFailed=@RowsFailed+count(*) from [Sales].[SalesTerritory] 
WHERE NOT ([SalesLastYear]>=(0.00))
Select @RowsFailed=@RowsFailed+count(*) from [Production].[Product] 
WHERE NOT ([SafetyStockLevel]>(0))
Select @RowsFailed=@RowsFailed+count(*) from [Sales].[SalesTerritory] 
WHERE NOT ([CostYTD]>=(0.00))
…and so on.

Now we’ll mangle our copy of AdventureWorks2016. Don’t worry, since it is a clone maintained by SQL Clone, I can do what I like and refresh it when I want it back to its pristine state. We’ll disable a constraint and alter the data so that when I try to reenable it, it will fail. Dave the Dev of AdventureWorks has decided that the MaritalStatus code in the employee table needs more options than M for married or S for single. What about P for Partner? He disables the CHECK constraint, CK_Employee_MaritalStatus.

ALTER TABLE humanResources.employee 
NOCHECK CONSTRAINT CK_Employee_MaritalStatus

Then he makes the necessary changes.

UPDATE humanresources.employee SET maritalStatus='P' 
WHERE BusinessEntityID=1  
UPDATE humanresources.employee SET maritalStatus='P' 
WHERE BusinessEntityID=7  
UPDATE humanresources.employee SET maritalStatus='P' 
WHERE BusinessEntityID=11 
UPDATE humanresources.employee SET maritalStatus='P' 
WHERE BusinessEntityID= 14 
UPDATE humanresources.employee SET maritalStatus='P' 
WHERE BusinessEntityID=17 
UPDATE humanresources.employee SET maritalStatus='P' 
WHERE BusinessEntityID=18 
UPDATE humanresources.employee SET maritalStatus='P' 
WHERE BusinessEntityID= 19

Developer Dave is just getting ready to change the constraint and enable it when he is called into an important team discussion, and he forgets.

Now we’ll rerun the code to monitor constraints. It will tell you that seven rows failed. It doesn’t tell you which rows in which table, and for which constraint. It is nice to have, but we’d want even more for the code to be useful.

If you want to play along and you don’t have SQL Clone, that is fine. We can replace the code this way once you’re done with testing.

UPDATE humanresources.employee SET maritalStatus='S' 
WHERE BusinessEntityID=1  
UPDATE humanresources.employee SET maritalStatus='M' 
WHERE BusinessEntityID=7  
UPDATE humanresources.employee SET maritalStatus='S' 
WHERE BusinessEntityID=11 
UPDATE humanresources.employee SET maritalStatus='S' 
WHERE BusinessEntityID= 14 
UPDATE humanresources.employee SET maritalStatus='S' 
WHERE BusinessEntityID=17 
UPDATE humanresources.employee SET maritalStatus='S' 
WHERE BusinessEntityID=18 
UPDATE humanresources.employee SET maritalStatus='S' 
WHERE BusinessEntityID= 19
ALTER TABLE humanResources.employee WITH CHECK 
CHECK CONSTRAINT CK_Employee_MaritalStatus

We can also alter what is in a constraint in order to simulate a problem

ALTER TABLE Production.Product DROP CONSTRAINT CK_Product_ProductLine;
GO
ALTER TABLE Production.Product WITH NOCHECK
ADD CONSTRAINT CK_Product_ProductLine
  --CHECK (upper([ProductLine])='R' OR upper([ProductLine])='M' 
  --  OR upper([ProductLine])='T' OR upper([ProductLine])='S' 
  --  OR [ProductLine] IS NULL); 
  CHECK (Upper(ProductLine) = 'A'
      OR Upper(ProductLine) = 'B'
      OR Upper(ProductLine) = 'C'
      OR Upper(ProductLine) = 'D'
      OR ProductLine IS NULL
        );

This constraint is set as disabled in this code; otherwise it wouldn’t execute without an error since the existing data fails the check.

You can run the test and then check that the code has picked up the problem. Then when you are finished, you can revert the change or, in my case, revert the clone.

ALTER TABLE Production.Product DROP CONSTRAINT CK_Product_ProductLine;
GO
ALTER TABLE Production.Product WITH NOCHECK
ADD CONSTRAINT CK_Product_ProductLine
  CHECK (upper([ProductLine])='R' OR upper([ProductLine])='M' 
  OR upper([ProductLine])='T' OR upper([ProductLine])='S' 
  OR [ProductLine] IS NULL);

Which Rows Violated which Constraints?

Now we decide what we really want. I can be sure that I want a copy of all the metadata about CHECK constraints in source control with each build, generated after the first build, so I can then test all the subsequent data sets in the deployment chain to make sure they are free from ‘breaking data’.

To store this information means a JSON document because it is text-based, and this can be more versatile. We are likely to need to test data held in a different version of the database, so we abandon the idea of using the metadata directly. I also like to know more about the data that was selected as failing the test. I would like the name of the table and the name of the constraint. I need where possible, to see a good sample of the data though this isn’t possible or necessary with CHECK constraints. We need to get more serious about the tests, even if we lose some of the elegance of the code. One other thing is necessary once we decide to make it possible to run this on other versions of the database: In the case of unique indexes and FOREIGN KEY constraints, we need to check whether all the columns and tables involved are there under the same name. With CHECK constraints, all we can realistically do is to check for the table’s existence.

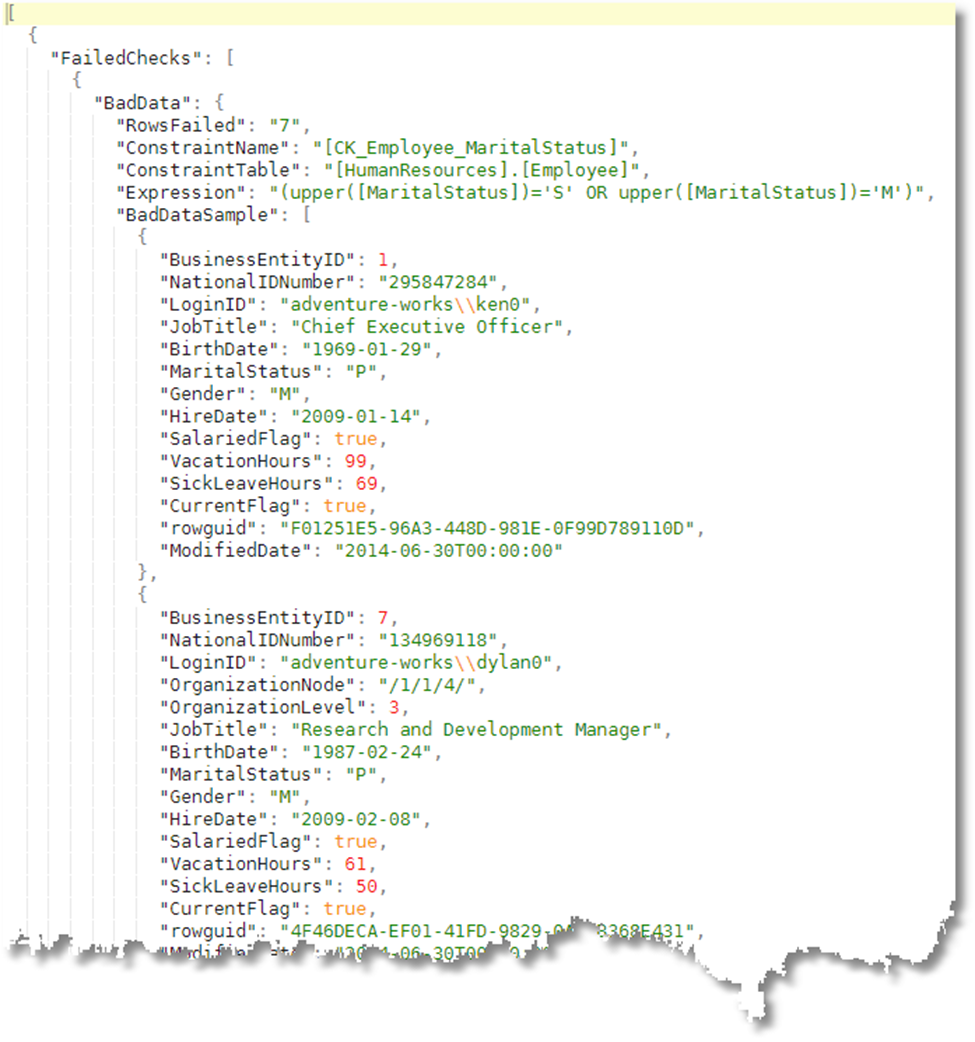
Here is an example of the report we get:

It is easy to see what is wrong in the data. That MaritalStatus column will need to be either ‘M‘ or ‘S‘ until Developer Dave fixes the constraint.

My apologies that this sort of convenience makes for more code.

DROP PROCEDURE IF EXISTS #ListAllCheckConstraints;
GO
CREATE PROCEDURE #ListAllCheckConstraints
  /**
Summary: >
  This creates a JSON list of all the check constraints in the database. 
  their name, table and definition
Author: Phil Factor
Date: 12/12/2019
Example:
   - DECLARE @OurListAllCheckConstraints  NVARCHAR(MAX)
     EXECUTE #ListAllCheckConstraints 
           @TheJsonList=@OurListAllCheckConstraints OUTPUT
     SELECT @OurListAllCheckConstraints AS theCheckConstraints
   - DECLARE @OurCheckConstraints  NVARCHAR(MAX)
     EXECUTE #ListAllCheckConstraints 
           @TheJsonList=@OurCheckConstraints OUTPUT
     SELECT Constraintname, TheTable, [definition]
      FROM OPENJSON(@OurCheckConstraints)  WITH
      (Constraintname sysname '$.constraintname',
           TheTable sysname '$.thetable', 
      [Definition] nvarchar(4000) '$.definition' ); 
Returns: >
  the JSON as an output variable
**/
  @TheJSONList NVARCHAR(MAX) OUTPUT
AS
SELECT @TheJSONList =
  (
  SELECT QuoteName(CC.name) AS constraintname,
    QuoteName(Object_Schema_Name(CC.parent_object_id)) + '.'
    + QuoteName(Object_Name(CC.parent_object_id)) AS thetable, 
    definition
    FROM sys.check_constraints AS CC
    WHERE is_ms_shipped = 0
  FOR JSON AUTO
  );
GO
DROP PROCEDURE IF EXISTS #TestAllCheckConstraints;
GO
CREATE PROCEDURE #TestAllCheckConstraints
  /**
Summary: >
  This tests the current database against its check constraints. 
  and reports any data that would fail a check were it enabled
Author: Phil Factor
Date: 15/12/2019
Example:
   - DECLARE @OurFailedConstraints  NVARCHAR(MAX)
     EXECUTE #TestAllCheckConstraints 
          @TheResult=@OurFailedConstraints OUTPUT
     SELECT @OurFailedConstraints AS theFailedCheckConstraints
  Returns: >
  the JSON as an output variable
**/
@JsonConstraintList NVARCHAR(MAX)=null,--you can either provide 
   --a json document or you can go and get the current
@TheResult NVARCHAR(MAX) OUTPUT --the JSON document that gives 
   --the test result.
as
IF @JsonConstraintList IS NULL
  EXECUTE #ListAllCheckConstraints 
      @TheJSONList = @JsonConstraintList OUTPUT;
DECLARE @Errors TABLE (Description NVARCHAR(MAX));--to temporarily 
      --hold errors
DECLARE @Breakers TABLE (TheObject NVARCHAR(MAX));--the rows that 
      --would fail
DECLARE @TheConstraints TABLE --the list of check constraints 
      --in the database
  (
  TheOrder INT IDENTITY PRIMARY KEY, --needed to iterate 
     --through the table
  ConstraintName sysname, --the number of columns used in the index
  TheTable sysname, --the quoted name of the table wqith the schema
  Definition NVARCHAR(4000) --the actual code of the constraint
  );
--we put the constraint data we need into a table variable
INSERT INTO @TheConstraints (ConstraintName, TheTable, Definition)
  SELECT Constraintname, TheTable, Definition
    FROM OpenJson(@JsonConstraintList)
    WITH --get the relational table from the JSON
      (
      Constraintname sysname '$.constraintname', 
       TheTable sysname '$.thetable',
      Definition NVARCHAR(4000) '$.definition' --the mapping
      );
DECLARE @iiMax INT = @@RowCount;
--to do the actual check
DECLARE @CheckConstraintExecString NVARCHAR(4000);
--make sure the table is there
DECLARE @TestForTableExistenceString NVARCHAR(4000);
--to get a sample of broken rows
DECLARE @GetBreakerSampleExecString NVARCHAR(4000);
--temporarily hold the current constraint name
DECLARE @ConstraintName sysname;
--temporarily hold the current constraint's table
DECLARE @ConstraintTable sysname;
--temporarily hold the constraint code
DECLARE @ConstraintExpression NVARCHAR(4000);
--the number of rows that fail the current constraint
DECLARE @AllRowsFailed INT; 
--a sample of failed rows
DECLARE @SampleOfFailedRows NVARCHAR(MAX);
--Did the table exist in the current database
DECLARE @ThereWasATable INT;
DECLARE @ii INT = 1;--iteration variables
WHILE (@ii <= @iiMax)
  --------------------start of the loop------------------
  BEGIN --create the expressions we need to execute 
        --dynamically for each constraint
    SELECT @CheckConstraintExecString = --expression that checks 
                                        --the constraint
      N'SELECT @RowsFailed=Count(*) FROM ' + TheTable + N' WHERE NOT '
      + Definition, @ConstraintName = ConstraintName,
      @ConstraintTable = TheTable,
      @GetBreakerSampleExecString = --expression that gets 
                                    --sample of failed rows
        N'SELECT @JSONBreakerData= (Select top 3 * FROM ' + TheTable
        + N' WHERE NOT ' + Definition + N'FOR JSON AUTO)',
      @ConstraintName = ConstraintName, @ConstraintTable = TheTable,
      @ConstraintExpression=[definition],
      @TestForTableExistenceString = --expression that checks 
                                     --for the table
        N'SELECT @TableThere=case when Object_id(''' + TheTable
        + N''') is null then 0 else 1 end'
      FROM @TheConstraints
      WHERE TheOrder = @ii;
      --check that the table is there 
    EXECUTE sp_executesql @TestForTableExistenceString,
      N'@TableThere int output', @TableThere = @ThereWasATable OUTPUT;
    IF @ThereWasATable = 1
      BEGIN --it is a bit safer to check the constraint
        EXECUTE sp_executesql @CheckConstraintExecString,
          N'@RowsFailed int output', @RowsFailed = @AllRowsFailed OUTPUT;
        IF @AllRowsFailed > 0 --Ooh, at least one failed constraint
          BEGIN--so we get a sample of the bad data in JSON
            EXECUTE sp_executesql @GetBreakerSampleExecString,
              N'@JSONBreakerData nvarchar(max) output',
              @JSONBreakerData = @SampleOfFailedRows OUTPUT;
            INSERT INTO @Breakers (TheObject)
              SELECT--and save the sample of bad rows along with 
                    --information about the constraint
                (
                SELECT 
                  Convert(VARCHAR(10), @AllRowsFailed) AS RowsFailed,
                  @ConstraintName AS ConstraintName,
                  @ConstraintTable AS ConstraintTable,
                  @ConstraintExpression AS Expression,
                  Json_Query(@SampleOfFailedRows) AS BadDataSample
                FOR JSON PATH, WITHOUT_ARRAY_WRAPPER
                );
          END;
      END;
    ELSE INSERT INTO @Errors (Description) 
         SELECT 'We Couldn''t find the table '
+ @ConstraintTable;
    SELECT @ii = @ii + 1; -- and iterate to the next row
  END;
 SELECT @TheResult= -- so we construct the JSON report.
  (SELECT
    (SELECT Json_Query(TheObject) AS BadData 
     FROM @Breakers FOR JSON AUTO) AS FailedChecks,
  (SELECT Description FROM @Errors FOR JSON AUTO) AS errors
FOR JSON PATH);
go

The first job the code does, using the temporary procedure #ListAllCheckConstraints is to create, from the development database a JSON-based list of all the check constraints that you can then use for the test. The obvious place to get this information from is the new build of the database. You don’t need any database data at this point as we’re just interested in the metadata. We just want to know what to check once you’ve imported the data and before you enable constraints.

With this data, stored as a JSON document to make it portable, we can then test the data within the target database this is done by #TestAllCheckConstraints

DECLARE @OurFailedConstraints  NVARCHAR(MAX)
     EXECUTE #TestAllCheckConstraints 
        @TheResult=@OurFailedConstraints OUTPUT
     SELECT @OurFailedConstraints AS theFailedCheckConstraints

You can then run all the tests on the target database automatically, using the data in this JSON document. If the table no longer exists, it will report the fact and avoid an error by bypassing the constraint check. Ideally, the check should really be in the pre-deployment script because you may decide that you want to prevent the build from going ahead if there is bad data in a column.

Here is an error where I’ve duplicated a row. This indicates that you will not be able to enable the index AK_SalesTaxRate_StateProvinceID_TaxType or AK_SalesTaxRate_rowguid without getting an error. It is telling you what duplicates will cause the error.

[{
    "duplicatelist": [{
        "duplicated": {
            "indexName": "AK_SalesTaxRate_StateProvinceID_TaxType",
            "tablename": "[Sales].[SalesTaxRate]",
            "columnlist": "[StateProvinceID],[TaxType]",
            "duplicates": [{
                "duplicatecount": 2,
                "StateProvinceID": 1,
                "TaxType": 1
            }]
        }
    }, {
        "duplicated": {
            "indexName": "AK_SalesTaxRate_rowguid",
            "tablename": "[Sales].[SalesTaxRate]",
            "columnlist": "[rowguid]",
            "duplicates": [{
                "duplicatecount": 2,
                "rowguid": "683DE5DD-521A-47D4-A573-06A3CDB1BC5D"
            }]
        }
    }]
}]

You will, however, be relieved that there is no ‘errors’ array in this document. Yes, it is easy to test. Why would you be relieved? This is because, if there were errors, the routine would be telling you that for one or more of the tests, either the table or one of the columns is missing. It does this check first, and if it knows that the duplicate check couldn’t even run, it doesn’t do it. You have a minor but tedious problem if you’ve changed the table columns used in these indexes as part of the release. This is because you’ll need to amend the list to allow an automated test, but this will be a relatively minor task. The script to make changes requires judgement and is not easily automated, but an existence-check for the columns is there and the information yielded should make a repair easy.

Another concern is that you may want to only test for certain constraints. As tables get much larger, it just takes too long. You only want to do them where you are putting in a new or changed constraint. Here, the answer is simple: you store the JSON document in source control and generate a new JSON document that lists just the new or altered constraints to be tested.

Summary

One aspect of DevOps teamwork involves a sort of remote running of test software. You as a developer devise the test, it is run by someone else under circumstances you can’t directly control, and you get back a report that gives you enough information to fix any problems that come up. It is curiously like the old Sybase technique of sending queries via email to be run, but without the scary surface-area exposure.

This type of test should avoid throwing errors and should collect all the information you need to script out a solution. It should not add work for the person who runs the script.

In the next article, we’ll add the routines for foreign key references and unique constraints. Armed with these, we can tie it all together to show how it fits in with a sophisticated deployment system such as SCA.


The post But the Database Worked in Development! Preventing Broken Constraints appeared first on Simple Talk.


from Simple Talk https://ift.tt/39T9l5I
via

Saturday, January 4, 2020

Comments and More in PowerShell

As with any programming language, PowerShell supports comments. In fact, it will support two styles of comments. However, as you will see later in this article, PowerShell can use comments in a couple of interesting and unexpected ways that can be quite powerful.

Using Comments

The most common style of comment you will see is a line preceded with a # symbol. (I leave it to you to decide if you want to call that a hashtag, a pound symbol, or even a good old octothorpe!)

As an example, you might have a comment block at the start of your program with details about it:

#This is an example of single-line comments
#
#Author: Greg D. Moore mooregr@greenms.com 
#Date: 2019-11-12
#Version: 1.0
#

Comments like this can go anywhere in your code. An alternative way of doing this, however, would be more what I would call a C language style or sometimes referred to as a block comment:

<#This is an example of a block comment
Author: Greg D. Moore mooregr@greenms.com 
Date: 2019-11-12
Version: 1.0
#>

This style allows you to more easily add lines of comments without having a # in front of each one. You’re free to use either style or even both. Just remember, though, the usefulness of comment blocks like this when you come back to debug your own code a year from now. However, comments don’t have to come at the start of a line either. In fact, personally I find myself only using comment blocks like above at the start of a script or right before a particularly complicated block of code. I’m far more likely to do endline commenting such as:

$Callback_Test_Form.Show() | Out-Null #absorbs cancel message at end. This occurs for reasons outside scope of this article

I included this comment in a recent script because the | Out-Null was not something I expected to be required, and I know a year from now if I didn’t have the comment there I’d be wondering why I had it there. Or worse, I’d remove it and then wonder why I was getting a cancel message that kept showing up.

Note that when you start a comment with a #, everything to the end of the line is treated as a comment. This can be useful for example when you are testing and might want to comment out the end of a command.

get-help write-host #Ooops, I don't want to go -online

This lets you later remove the comment and get the –online version of help, but what if you want a comment in the middle? Again, PowerShell gives you that power.

get-help write-host <# I want the most recent, so I'll go #> -online

Note that by using a block style comment, you get the ability to have a comment in the middle of your command and still execute or interpret items to the right of it. Finally, you may be wondering, “what if I want to print out a # or do something similar?” If you try

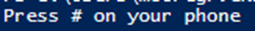
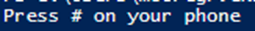
write-host Press # on your phone

You’ll find it doesn’t write out what you want. You simply get:

This is where the grave-accent ` comes in handy.

write-host Press `# on your phone

This will print out the message you want.

You could also wrap that entire string in quotes:

write-host 'Press # on your phone'

That would work, but I wanted to give an example of how to escape the # qualifier.

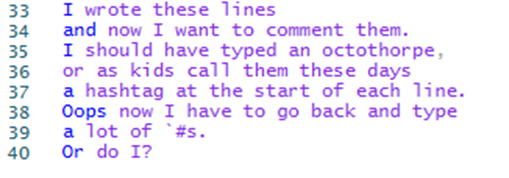
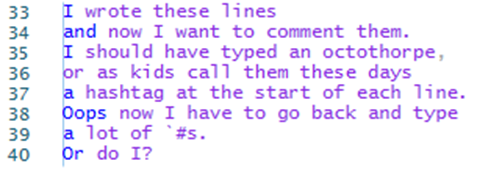
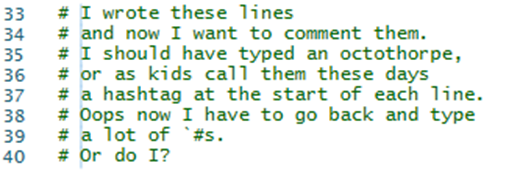
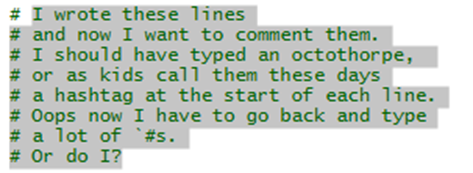
If you, like me, often use the PowerShell ISE to write scripts, there is one last useful trick I want to share, but can only describe and give some screenshots for, not actually provide a script for it. It’s a keyboard shortcut that’s not comment specific but useful if you have a chunk of code you want to comment out, say for testing. Put the cursor at the start of the line and holding down Shift-Alt use the arrow keys to move it up or down. You will notice a thin line (blue on my screen) appear. Once you’ve marked the lines you want to comment, simply type a # and it will appear at the start of each line.

This is an example of the code to comment:

When clicking at the right of the text on line 40 and after pressing Shift-Alt and the up arrow several times, you’ll see the blue line:

After pressing # <space> you’ll see the characters added to the code:

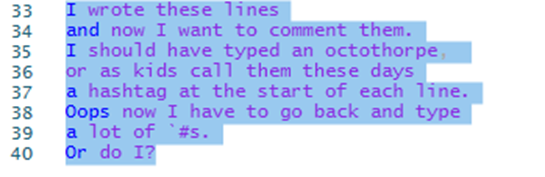
As a note, you can use this trick anywhere on the line (so if you wanted to put a bunch of comments at the end of a number of lines you could use this trick to easily put in the # for you) and is obviously not specific to commenting, but that’s one of the most obvious usages. You can also do this using regular expressions. Highlight the block of code in question:

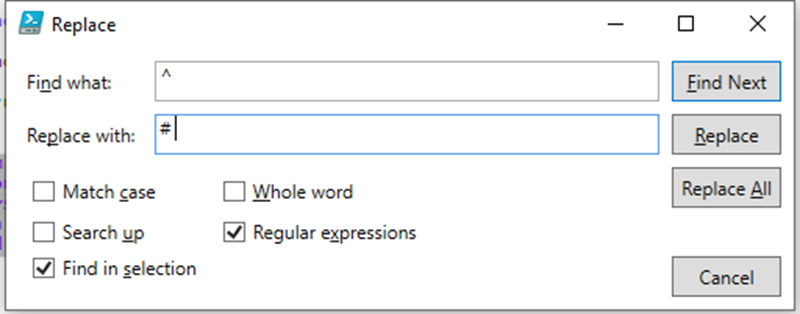
Then Ctrl-H to get the Find and Replace dialog box. Make sure Find in Selection and Regular expressions are selected:

The caret ^ is used to anchor the start of a line and of course the # (there is a space there) basically inserts a # and space at the end of the highlighted lines. Note if you fail to highlight a block of code, this will operate on your entire script.

And More

However, if that was all that comments could do in PowerShell this would be a very short and boring article (and my editor would be shaking her head saying, “Greg, I need more than 850 words!”) Like many things in PowerShell, the creators added features that make it more powerful than you might expect.

I was recently preparing for a presentation I was giving at the Hampton Roads SQL Server User Group. During this presentation, I run a script in PowerShell that starts and stops SQL Server. To do this, I need to run it as administrator. Of course, I had completely forgotten that during a practice, and when I ran it as myself, it ended up throwing several ugly errors. This was not a showstopper, but not what you want during a demo. This got me thinking about how I could ensure this wouldn’t happen during the actual talk.

My first thought was to find some cmdlet that would check to see who I was logged in as and then abort if I wasn’t the right user. Part of the problem with this approach of course is that when you run a program (such as PowerShell ISE) as administrator, you show up as the user logged in. This was going to be harder than I thought.

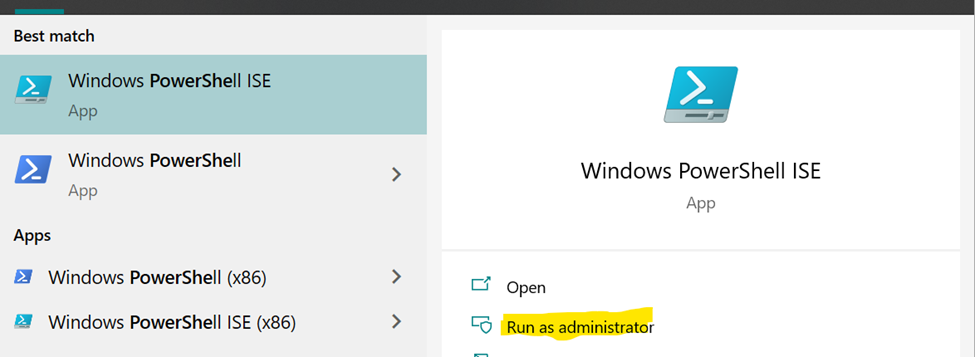
Once again, PowerShell surprised me. Solving this problem is trivial. To see how to solve the problem, open the PowerShell ISE as yourself (i.e. do NOT select Run as administrator and make sure your user doesn’t have local admin privileges) and enter the following code:

stop-service "windows time"
start-service "windows time"

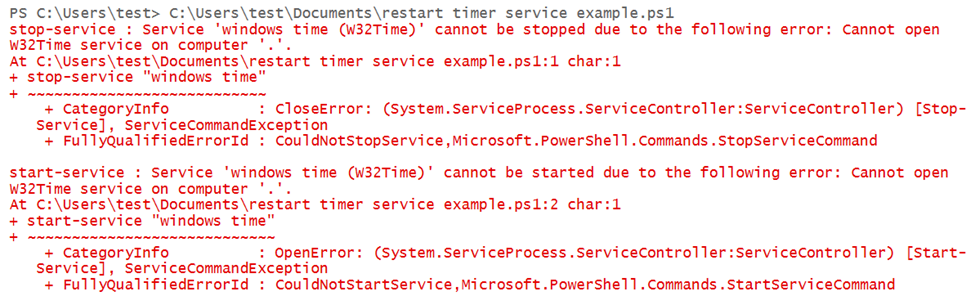
Save this to a file called restart timer service example.ps1 and then try to run it. Unless you’re a local admin on your machine you should get an error screen similar to below.

If you run this using the Run as Administrator option, it should run without error. In this example, the failure is pretty benign, but perhaps you’re writing a script were a failure would not be so harmless. To solve this problem, simply put the following comment at the top of the script above and resave it.

#Requires -RunAsAdministrator

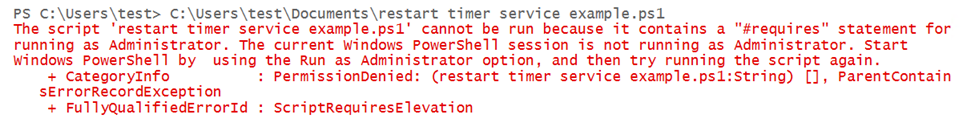
Now you will get a different error:

It’s still a bit ugly but far better than running the script and perhaps breaking something. Note if you simply cut and paste the script into a new window, but do not save it, PowerShell will attempt to run the whole thing. Basically the #requires gets ignored unless it’s an actual saved file. This solved my initial issue, but it got me looking into other features I wasn’t aware of. For #requires, there’s an entire list:

#Requires -Version N[.n]
#Requires -PSEdition [ Core | Desktop ]
#Requires –PSSnapin PSSnapin-Name [-Version N[.n]]
#Requires -Modules { Module-Name | Hashtable } 
#Requires –ShellId ShellId
#Requires –RunAsAdministrator

As you can see, these give you a lot of power in controlling how and when your script is run. The #Requires –Version is useful if your script requires features that are only available in a more recent version of PowerShell. Note that this is a minimum number. The version of PowerShell you are running must match this or be higher. You can’t use this to require a previous version of PowerShell. For example, a useful cmdlet I used in a recent script is compress-archive. Fortunately, this script was specific to the problem I was trying to solve, but if I were trying to write a more general script, I might want to put #requires –Version 5.0 at the stop of my script. To demonstrate save the following script as requires version example.ps1.

#requires -Version 5.0
Get-Process | Out-File -FilePath .\Process.txt
Compress-Archive -Path .\Process.txt -DestinationPath .\Process.zip -Force

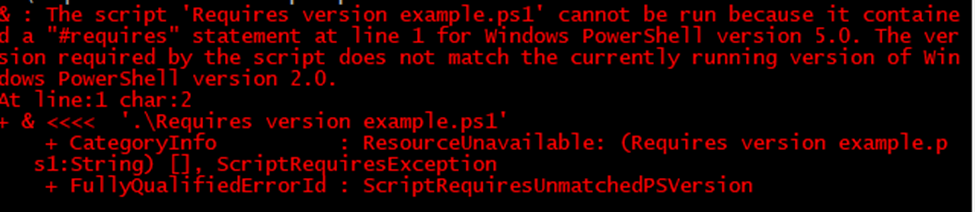
If you run this within your existing PowerShell ISE instance, it should run without an issue, but if you try to run in an older version, such as PowerShell 2.0, the script will error on the #requires line and never execute the rest of the script. This is the desired outcome.

For testing, you could also put in something like –Version 99.99 and you will see error messages similar to the examples below, but I wanted to show how this would work in the real world on existing systems and also demonstrate the command line ability to fall back to a previous version of PowerShell.

To test this, you will have to use command line version of PowerShell and start it as follows:

C:\>Powershell –version 2.0

Then run the file you saved above requires version example.ps1. You should see an error such as:

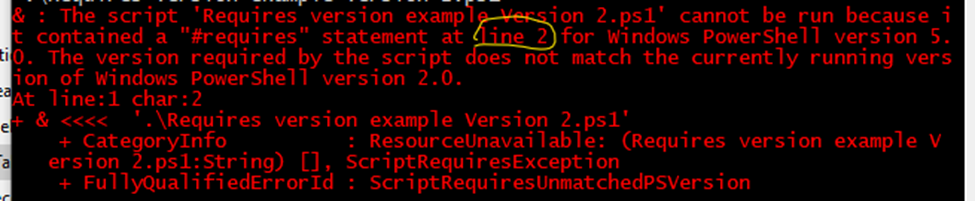
While I would recommend putting the #Requires comment at the very beginning of the file, in truth, you can put it anywhere and it will act the same way. If you recreate the above file but move the comment down after the Get-Process and save as requires version example Version 2.ps1.

Get-Process | Out-File -FilePath .\Process.txt
#requires -Version 5.0
Compress-Archive -Path .\Process.txt -DestinationPath .\Process.zip -Force

Try to run it under version 2.0 as above, and you’ll get a similar error and the entire script will fail to run.

This means you can’t have part of a script that can run under an older version (or run as non-administrator) and then part that requires a particular version or to run as administrator. If you want to do something like that in code, you need to get smarter. Save the following script as Requires version example Version 3.ps1.

Get-Process | Out-File -FilePath .\Process.txt
if ($PSVersionTable.PSVersion. Major -ge 5)
{
    Compress-Archive -Path .\Process.txt -DestinationPath .\Process.zip -Force
}
else
{
    Write-Host "I'm sorry Dave, I can't do that."
}

If you run this under Version 5 or greater, it will create the Process.txt file and zip it up. If you run it under an earlier version, such as the –Version 2.0 above, the script will still be able to create the Process.txt file since Get-Process is a cmdlet available in version 2.0. Since Compress-Archive is not, the script will skip that step and give an error message. It’s up to you if you want to write scripts that can detect the version of PowerShell and behave differently depending on the version, but in many cases if you simply want to abort the script, the #Requires comment is by far the easiest way of handling things.

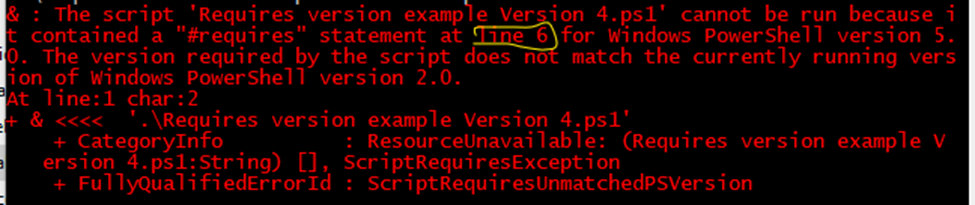
Two last caveats on using a #Requires comment. It must start at the beginning of the line; you can’t have any spaces or tabs before it. In addition, you can’t try to outsmart it and put it as part of a try/catch block to more gracefully handle it. Save the following script to illustrate both caveats: Requires version example Version 4.ps1.

#requires -Version 5.0
try
{
    write-host "We're at version 5.0!"
#requires -Version 5.0
}
catch
{
    write-host "Hey, we're not at version 5!"
}

Note it is the #requires on line 6 that aborted the script, not the one on line 1, and the try/catch had no effect. #Requires are global and impact the entire script, regardless of where they are, provided they start on the line. And yes, you can have more than one #Requires in a script. You could require a specific version of PowerShell, certain modules to be present and to RunAsAdministrator.

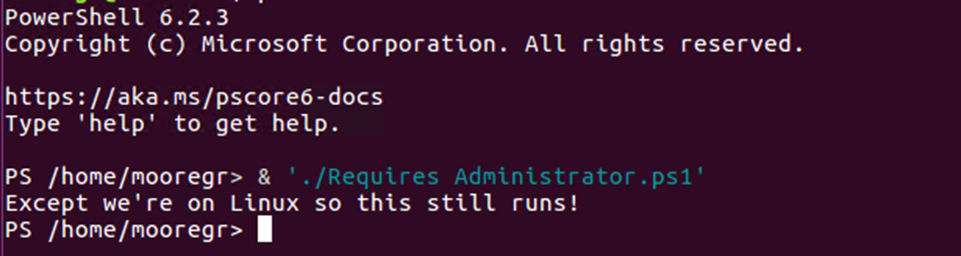
Two final caveats on the #Requires – RunAsAdministrator comment. It was introduced in PowerShell version 4.0 and does not work on non-Windows systems (yes, remember, PowerShell is now cross-platform!). Save the following script as Requires Administrator.ps1.You will need a Linux instance to test this, but assuming you do, PowerShell can be installed on Linux using the methods explained here. Once installed copy over or save the script above to your Linux instance. To run the script you can enter:

Pwsh "./Requires Administrator.ps1"

You should see

Finally, you may be wondering if you can use block style comments with the #Requires. From my limited testing, this does not work. You need to put each Requires on its own line with a preceding #. This script works:

#Requires -RunAsAdministrator
#Requires -Version 5.0

This script doesn’t work:

<#Requires -RunAsAdministrator
Requires -Version 5.0 #>

Conclusion

As you can see, PowerShell comments are useful not only for their obvious role of allowing you to comment your code, but also are useful for controlling execution of your code. You can choose between single-line comments or block comments and you can put them before blocks of code or inline with the code. Note that all these scripts are available on Github.


The post Comments and More in PowerShell appeared first on Simple Talk.


from Simple Talk https://ift.tt/36p5zz1
via

Using Calendars and Dates in Power BI

The series so far:

  1. Creating Calculated Columns Using DAX
  2. Creating Measures Using DAX
  3. Using the DAX Calculate and Values Functions
  4. Using the FILTER Function in DAX
  5. Cracking DAX – the EARLIER and RANKX Functions
  6. Using Calendars and Dates in Power BI

Creating and using a calendar table is pretty straightforward, but this article will explain not just how to create a table, but also why you should want to do this. The article will also answer questions such as: what happens if you have two or more dates in the same table that you want to reference? Or if you have another table which holds information at a different level of granularity? Or if you want to report sales by bank holidays? Read on for how to create a robust data model for handling time-based data!

Loading the Sample Data for this Article

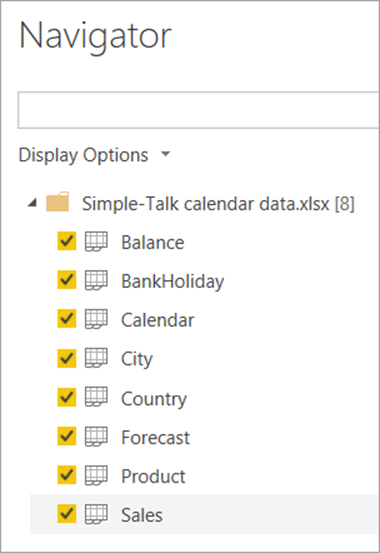
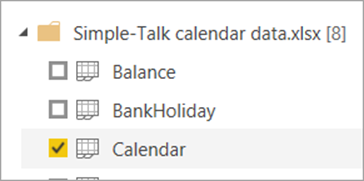
To work through the examples in this article, you’ll need to download the worksheets from this workbook. Tick all of the worksheets when you’re loading data into a new Power BI report:

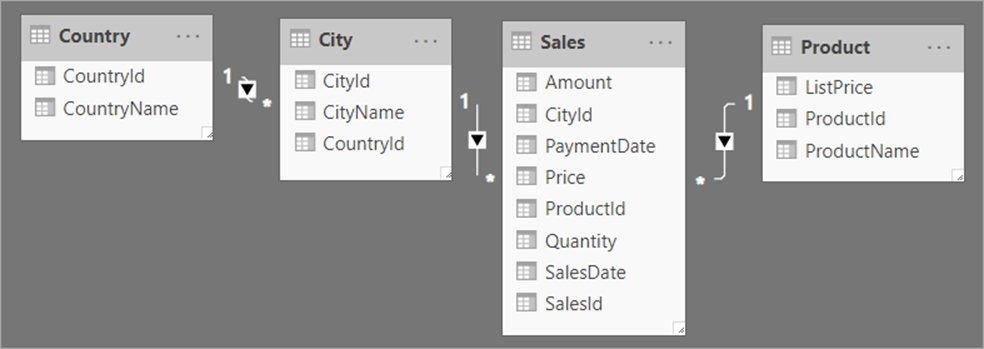
These tables will give you the following data model:
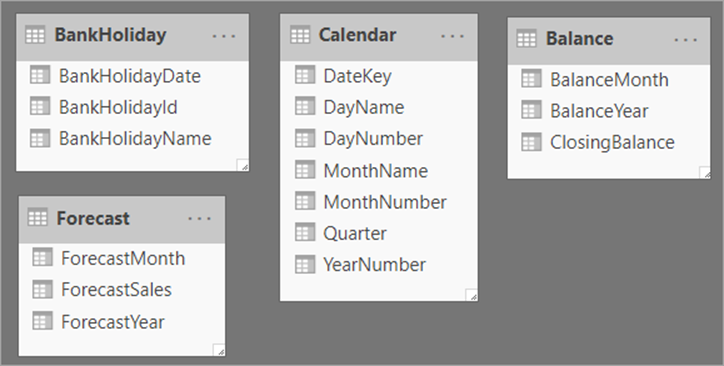
In addition, you should have the following four tables which aren’t linked:

You’ll be using some of these tables in what follows, and some in the next article in the series.

Why Do You Need to Create a Calendar?

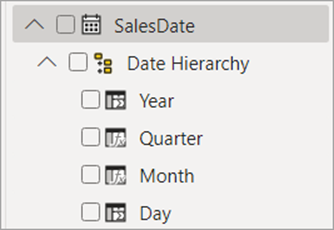
When I was first learning Power BI (actually, it was PowerPivot in those days, those many moons ago), I didn’t initially see the point of calendars. After all, Power BI allows you to include fields from date hierarchies which are created automatically for you:

However, having a calendar table gives two big advantages:

  • It allows you to aggregate data by non-standard columns (think your company’s financial year, or your timesheet weeks, or the Mayan calendar!).
  • It gives you access to all of the wonderful time-intelligence functions in DAX, with names like TOTALYTD and CLOSINGBALANCE. Without a calendar table these won’t work.

Given that most people’s main interest in creating measures in DAX is to compare numbers across time periods, the second point is a bit of a clincher!

The Requirements for a Calendar

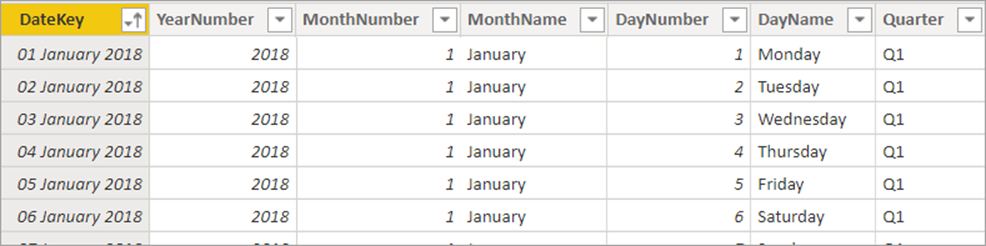
What should a calendar table in Power BI look like? Here’s an example:

Thus, a calendar table should include one row for each date in your model in which you might be interested. In the example above, the table consists of all the dates in 2018, 2019 and 2020, since this is the lifespan of the transactions in the Sales worksheet. In addition, each date row should have a primary key (a unique field which tells you the date you’re looking at). This doesn’t have to be a date; you could use a separate numeric field instead. However, since dates are stored internally as numbers, I can’t see any reason not to use a date column as your primary key, as above.

Creating a Calendar in DAX

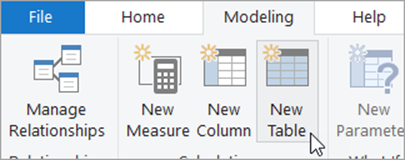
DAX contains a couple of functions which will auto-generate a calendar table for you (this sounds like a good idea, but probably isn’t – read on). One of these is the CALENDARAUTO function. To use this, click on the following tool found on the Modeling tab to create a new table:

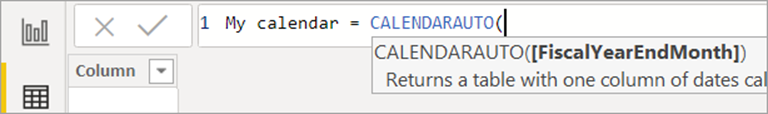
Type in a name for your table. Here I’ve called mine My calendar. Then use the CALENDARAUTO function to say what it will contain:

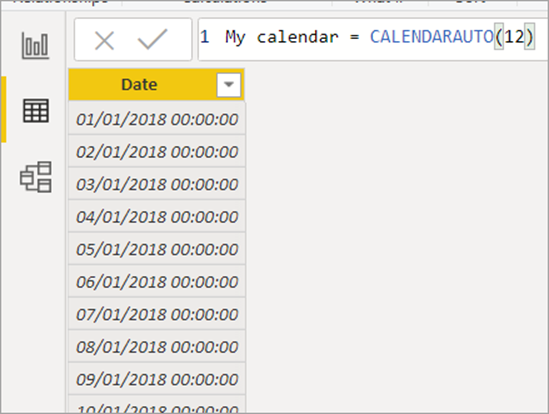
In this case, just assume that the fiscal year ends in December. You could leave out the argument 12, since December – month 12 – is the default anyway:

My calendar = CALENDARAUTO(12)

When you confirm, you’ll see that this formula Power BI will create a set of dates going from the first date it finds in your data model to the last. In this example the first date is 10th February 2018 and the last date is 8th January 2020. Because the financial year ends in December, the function will generate a table containing all the dates for the months January through to December for the years 2018, 2019 and 2020:

This was all very quick, but also not that useful, as you’re now going to have to add columns giving the year, month, quarter and so on for each date AND then do the same thing for each model that you create.

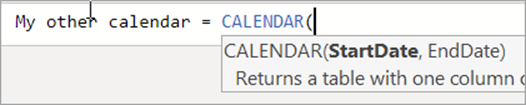
A variation of the above is the CALENDAR function, which lets you specify a start and end date:

This works in exactly the same way (and suffers from the same drawbacks), but it does at least give you more control over which dates are generated.

Creating a Calendar in Excel

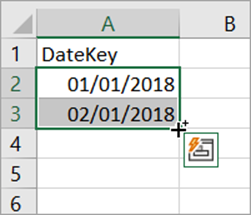
Another way to create a calendar is using an Excel spreadsheet. To do this, type in a column heading and the first couple of dates, and click and drag down using the black cross shown:

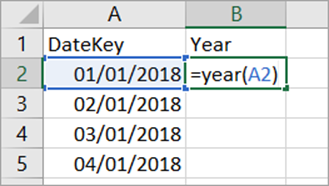
You can now add columns giving the year number, month number, etc. For example, for the year number:

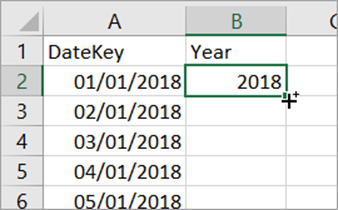
You could then double-click on this black cross to copy this formula down:

Here are some functions that you could use:

  • =YEAR(A2) – to get the year number, as above
  • =MONTH(A2) – to get the month number, as above
  • =TEXT(A2,"mmmm") – to get the month name
  • =TEXT(A2,"mm - mmmm") – to get the month number/name
  • =DAY(A2) – to get the day number
  • =TEXT(A2,"dddd") – to get the day name
  • ="Q" & INT((MONTH(A2)+2)/3) – to get the quarter number

You could then save the Excel workbook (possibly pasting the formulae as values first) and use this as a source for your Power BI calendar table.

Creating a Calendar in SQL Server

If you’re using SQL Server, this is probably the best option. Here’s a sample procedure which you can adapt to generate one row for every date in a given range. It doesn’t claim to be that efficient (it uses cursors!), but you’re only going to have to run it once.

CREATE PROC spCreateCalendarTable (
        @StartDate datetime = '20180101',
        @EndDate datetime = '20201231'
) AS
-- create a table of dates for use in Power BI
-- first get rid of any old versions of table
DROP TABLE IF EXISTS tblCalendar
-- create the table of dates
CREATE TABLE tblCalendar(
        DateKey date PRIMARY KEY,
        YearNumber int,
        MonthNumber int,
        [MonthName] varchar(10),
        DayNumber int,
        [DayName] varchar(10),
        [Quarter] char(2)
)
-- now add one date at a time
DECLARE @i int = 0
DECLARE @curdate datetime = @StartDate
WHILE @curdate <= @EndDate
        BEGIN
        -- add a record for this date 
        --(could use FORMAT function if SQL Server 2012 or later)
        INSERT INTO tblCalendar (
                DateKey,
                YearNumber,
                MonthNumber,
                [MonthName],
                DayNumber,
                [DayName],
                [Quarter]
        ) VALUES (
                @curdate,
                Year(@curdate),
                Month(@curdate),
                DateName(m,@curdate),
                Day(@curdate),
                DateName(weekday,@curdate),
                -- the quarter number
                'Q' + CAST(floor((month(@curdate)+2)/3) AS char(1))
        )
        -- increase iteration count and current date
        SET @i += 1
        SET @curdate = DateAdd(day,1,@curdate)
END

Using a Calendar

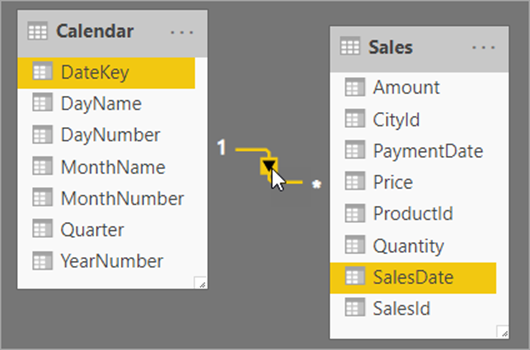
Once you’ve created a calendar, here’s how to use it. First load it into your data model (in this case, it was loaded with the Excel data), then link it to a date column. Here I’ve assumed that you want to analyse sales by the sale date and not the payment date. Later in this article you’ll learn how to cope with the situation where you have two or more dates in a table.

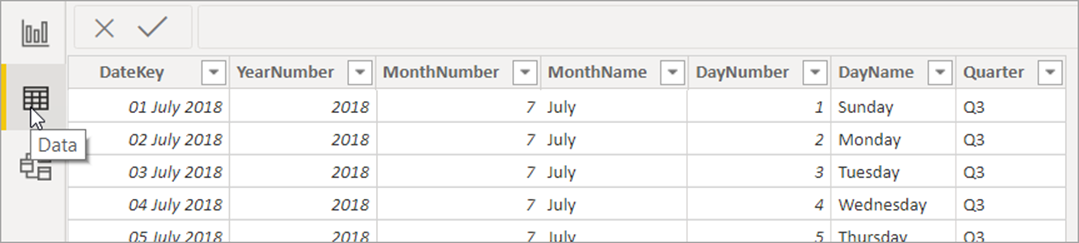
You now need to tell Power BI that the Calendar table is … a calendar table! To do this, make sure you’re looking at the calendar table in Data view:

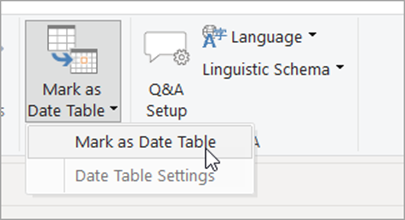
On the Modeling tab, choose to mark this as a calendar table:

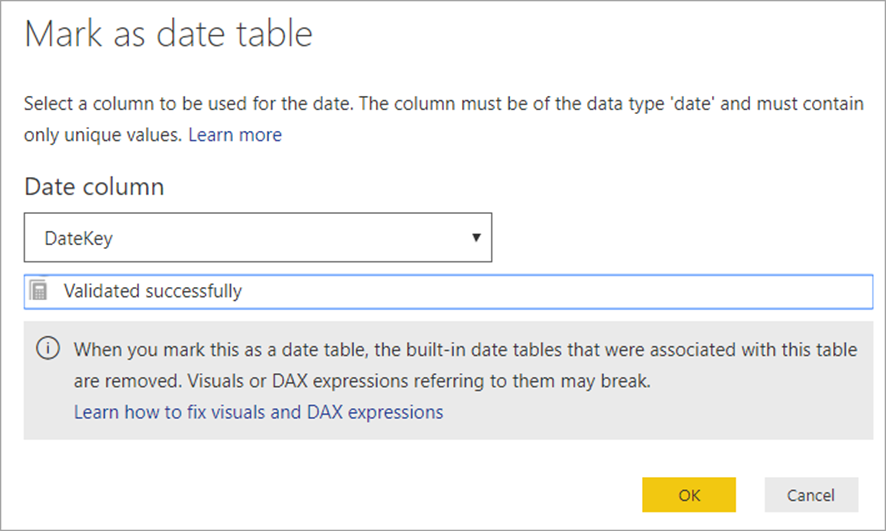
Choose the column which uniquely identifies each date, then choose OK:

The only problem with all of this is that I’m not convinced it’s necessary! It certainly can’t do any harm, but my understanding is that if you’ve chosen a date column as your primary key, DAX time-intelligence functions will work even if you omit this step.

Fine-tuning Your Calendar Table

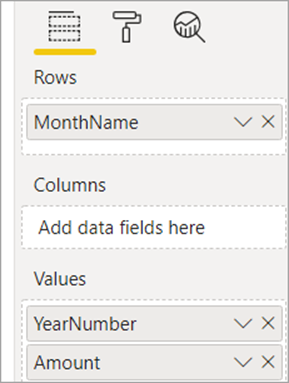
To see the Calendar table in action, create a matrix based upon your calendar, using these fields:

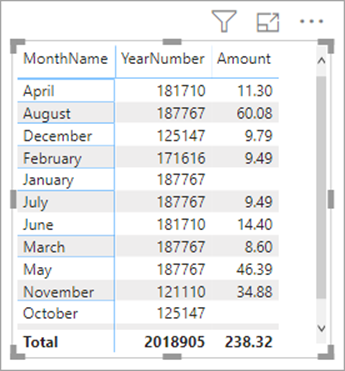
You’ll get something like this:

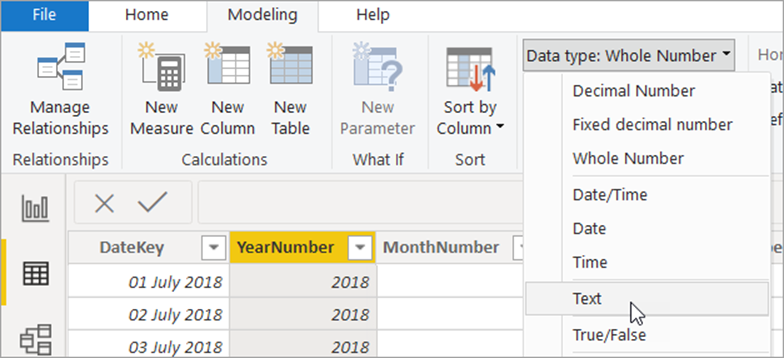
There are two problems here: Power BI has assumed that the year number is an integer which needs summing, and it has also assumed that the month name is text which can be sorted alphabetically. There are other solutions to both problems, but the simplest ones are as follows. First, change the year number to a text column:

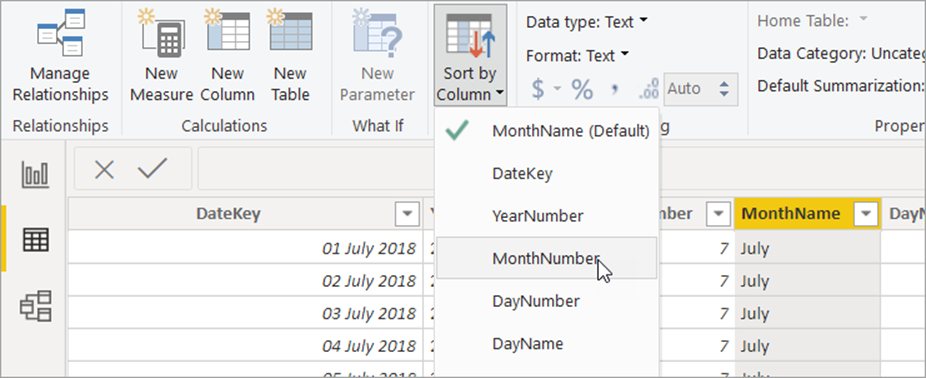
Secondly, with the month name column selected, choose to sort it by month number:

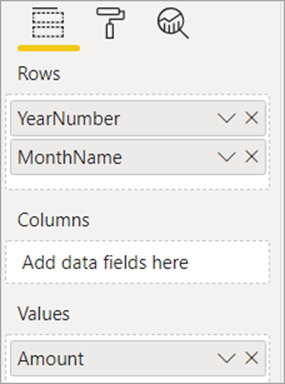
You can now create a matrix with these fields:

To get this visual:

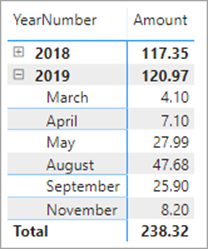
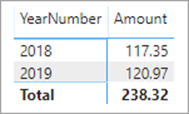
Note that instead of the visual shown above, you may get something like this one:

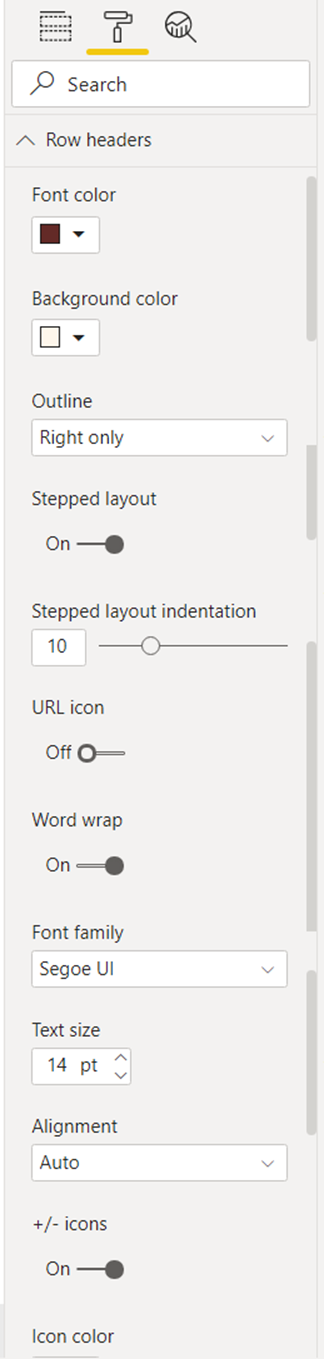
In this case, try finding and setting the +/-icons settings for your matrix in the Row headers card, to enable you to expand and collapse rows:

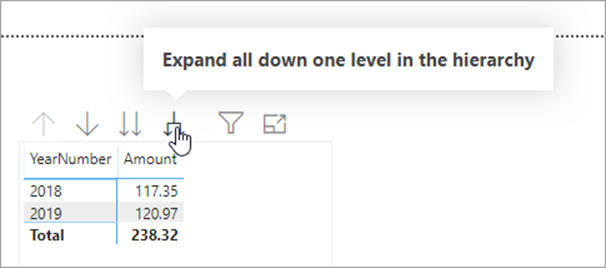
If you don’t have this property, it may be that you’re using an older version of Power BI, in which case, drill down to show all the levels of detail for your matrix:

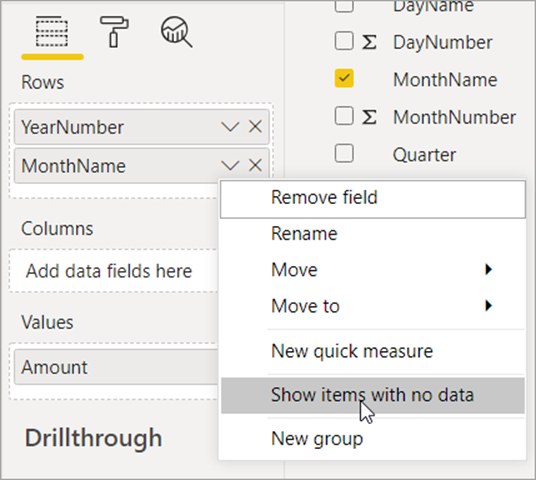
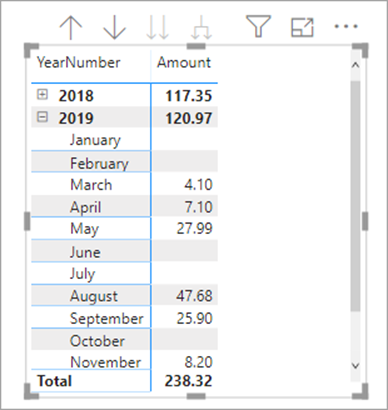
As one final touch, it would be nice to have all of the months appearing, so choose to show items with no date by clicking on the drop arrow next to the MonthName column:

And finally, you’ll see the perfect matrix!

Dealing with Different Levels of Granularity

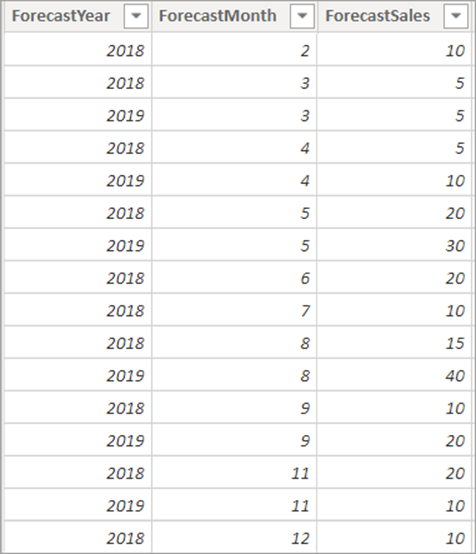
Suppose now that you want to compare actual and forecast sales which is a common enough requirement. This should be easy – you already have a table of monthly forecasts for sales:

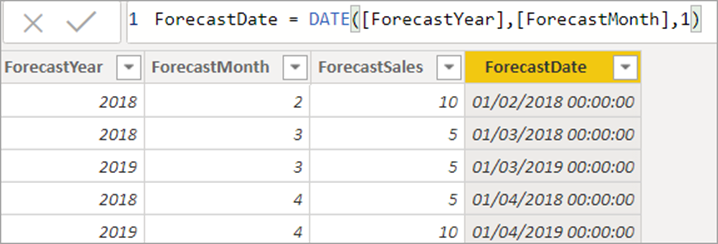
However, these forecasts are by month and the Calendar table is by date. The easiest solution is to create another column which arbitrarily assigns each forecast to the first day of the month in which it occurs:

Here’s the formula used:

ForecastDate = DATE([ForecastYear],[ForecastMonth],1)

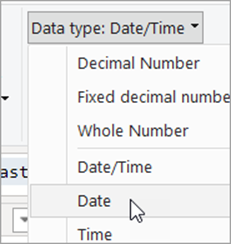
It’s probably a good idea to narrow the data type for this column from Date/Time to just Date:

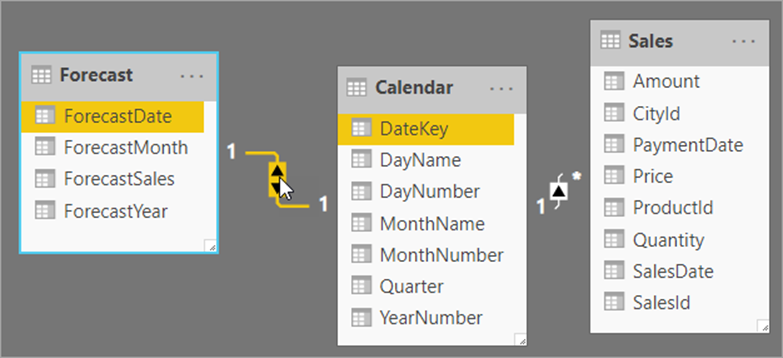
You can now create a relationship between this new forecast date column and the calendar’s date key column:

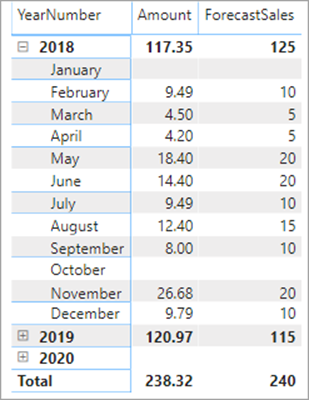
This will enable you to compare actual and forecast data at any level of granularity down to month:

Note that you’ll obviously have to be careful not to drill down to day level, since the forecast sales have been arbitrarily assigned to the first day in each calendar month and the results would be misleading.

Creating New Aggregator Columns (Like Bank Holidays)

Readers outside the UK will need to know that a bank holiday is a day which is treated like a Saturday or Sunday (that is, you don’t have to go to work); there are about 10 of them each year, including Christmas Day, Boxing Day, New Year’s Day, etc. The solution divides sales into working and non-working days where a non-working day is either a Saturday, a Sunday or a bank holiday. To do this, create some new columns in the Calendar table.

Note that you can use this principle to report by any type of date: examples could include periods when you’re offering a discount to customers, timesheet weeks, times of the day when shops are open, etc.

Although you could just create a complicated single column, to make things easier to understand – and to work with – you’ll create three:

  1. A column saying whether this is a weekend or not.
  2. A column saying whether this is a bank holiday or not.
  3. A column combining these two conditions.

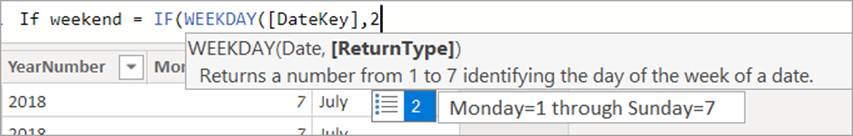
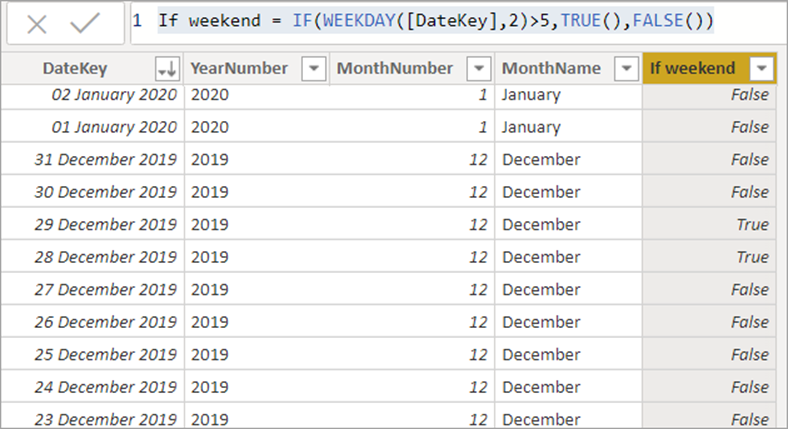
To do the first, use the WEEKDAY function, but tweak the second argument so that it returns 6 for Saturday or 7 for Sunday:

So the full calculated column will be:

If weekend = IF(WEEKDAY([DateKey],2)>5,TRUE(),FALSE())

You could use the shorter form, if you’re comfortable with Boolean algebra!

If weekend = (WEEKDAY([DateKey],2)>5)

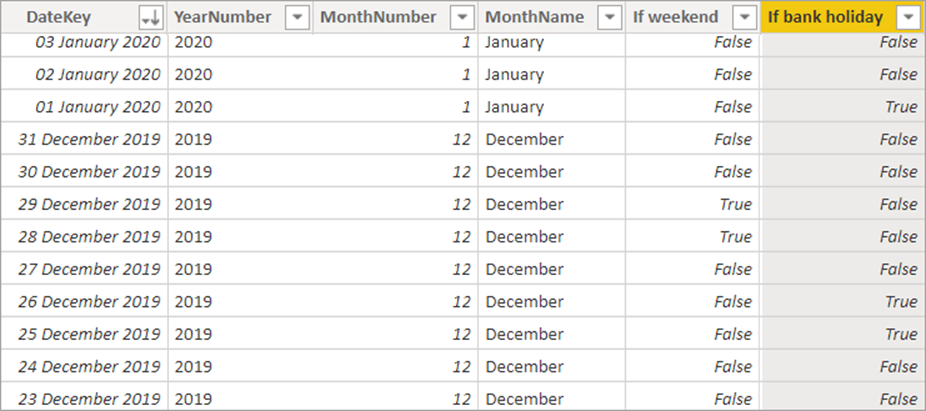
This shows, for example, that Christmas Day 2019 was on a Wednesday (that is, 3 days before the next weekend started):

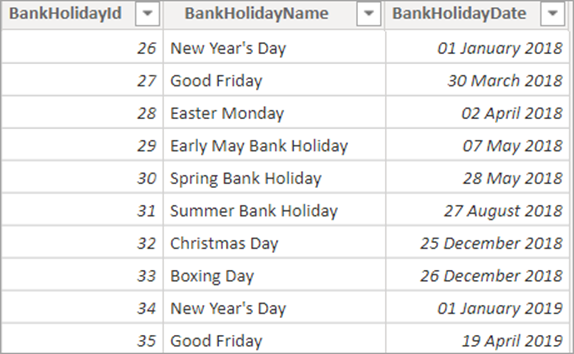
To say whether a day is a bank holiday, for example, you should first create and load a table of bank holidays (or use the one supplied in this article’s Excel workbook):

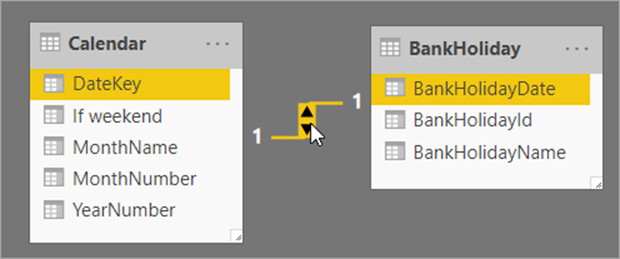
Now create a one-to-one relationship between the two tables:

It’s created as one-to-one automatically because the DateKey is unique in the Calendar table, but the BankHolidayDate column is also unique in the bank holidays table too.

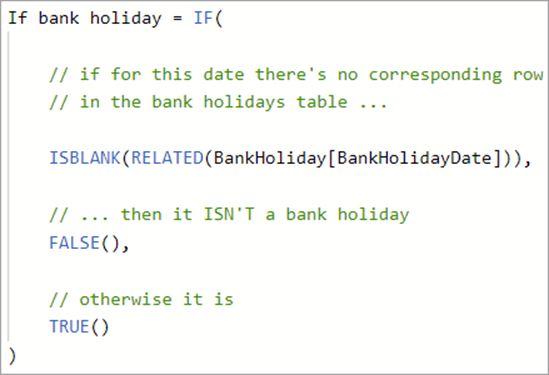
You can now create another calculated column in the Calendar table:

Here’s the code used, for copying:

If bank holiday = IF(
    
    // if for this date there's no corresponding row
    // in the bank holidays table ...
    ISBLANK(RELATED(BankHoliday[BankHolidayDate])),
    // ... then it ISN'T a bank holiday
    FALSE(),
    // otherwise it is
    TRUE()
)

This shows that Christmas Day 2019 was a bank holiday as expected:

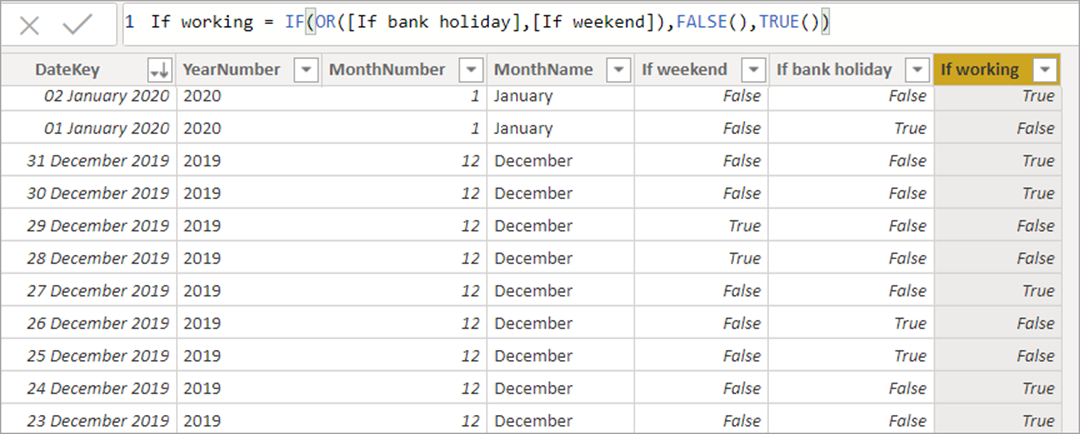
You could now combine the two conditions to get the status of any day:

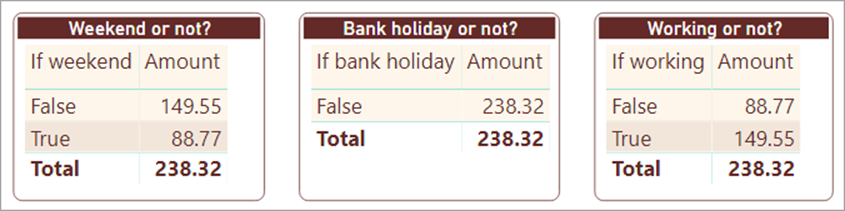
This method will allow you to create reports dividing sales into working and not-working days, although the results aren’t that exciting because as it happens no sales were made on a bank holiday:

Handling Multiple Dates

How do you cope when (as is nearly always the case in the real world) a table has two or more dates? For this example, how could you create a visual comparing the month of purchase with the month of payment? There are two ways. One way is to have multiple relationships between the same tables and specify in your measures which one you want to reference:

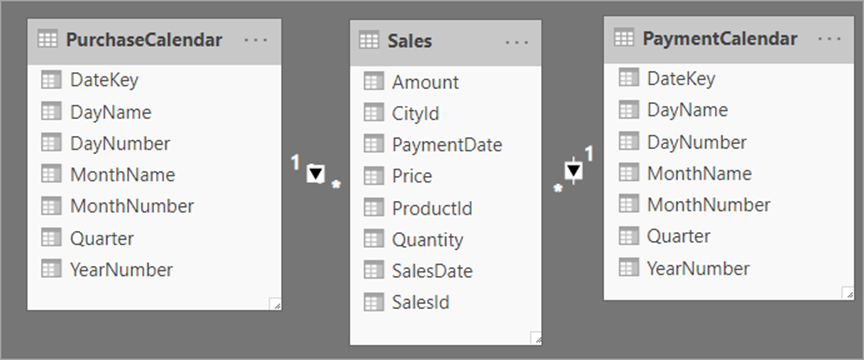
The second method is to use multiple versions of the calendar table:

Which solution you prefer will tell you a bit about what sort of person you are – think of it as a simple personality test. If you’re the sort of person who likes technology for its own sake, you’ll probably prefer the first solution: you’ll like the fact that you’re not storing the calendar table more than once, and you’ll be prepared to sacrifice a bit of ease of use. If on the other hand, you’re the sort of person who likes technology solely as a means to an end, you’ll probably prefer the second solution. Even though it involves holding multiple copies of the calendar table, the resulting model is easier to work with.

The Wise Owl Recommendation

If you’re interested, I prefer the second method (but then I do work for a training company, so by temperament am likely to want to make things as easy to use as possible). However, it doesn’t make you a bad person if you prefer the first method – just different to me.

Both methods are shown under separate headings below. I’ll begin with the multiple table approach since it’s easier to understand and is probably the one that most people will use.

Multiple Tables for Multiple Dates

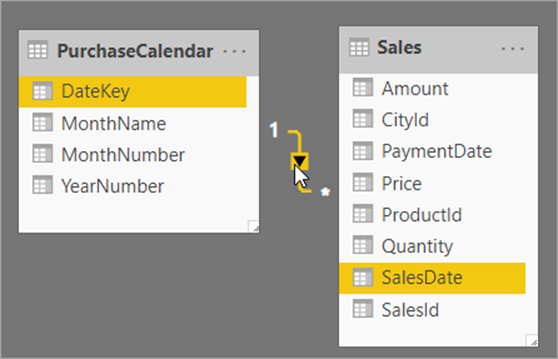
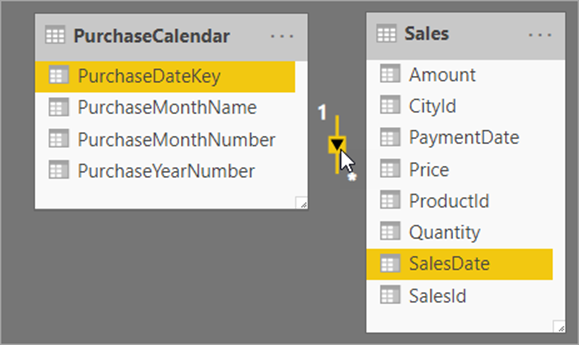
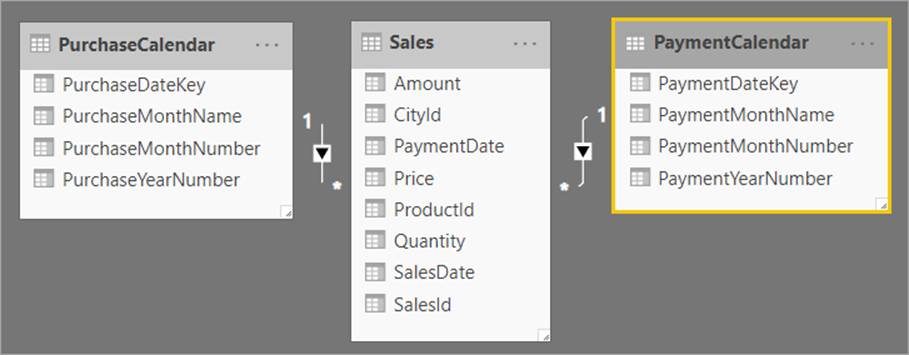
For this method, start by renaming the first calendar table that you’ve imported. For the model below, the calendar table is linked to the SalesDate column (the date on which a purchase took place), so I’ve renamed the Calendar table to PurchaseCalendar to make it clear what’s going on. I’ve also removed some of the calendar columns to keep the table simple:

If you have the energy, it would probably be a good idea to rename each of the columns in this table too:

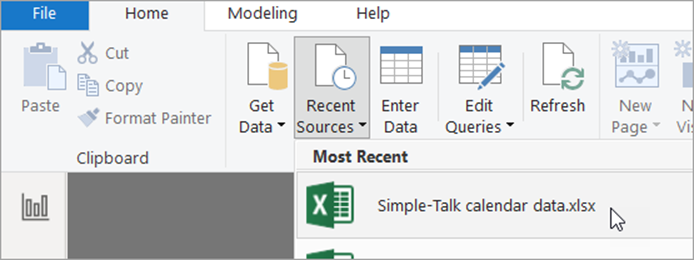
Now choose to load another version of the calendar table using your recent sources (the workbook or database from which you loaded the calendar table will be listed here):

Choose to import another version of the calendar table:

Drag this onto the same layout diagram, and create a relationship between the SalesData table and your recently loaded calendar table, but this time using the PaymentDate column as the link field:

Once again, you could now rename this version of the calendar table (and also rename the columns it contains) to make it clearer what’s what. In this example, I’ve also deleted some columns I don’t want:

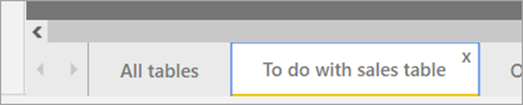
There are two arguments you could make against this approach: that it wastes memory, and that it clutters up your model. Both are true. But it doesn’t waste that much memory. Each table stores about 1,000 dates, which is peanuts in today’s memory terms. It doesn’t have to clutter up your model if you use different tabs like this (one tab for each table containing multiple dates):

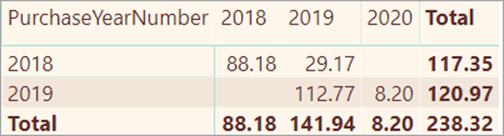
Having loaded all of your calendar tables and created the necessary relationships, you could use your model to create a matrix like this, showing the lag between purchases made and payments received:

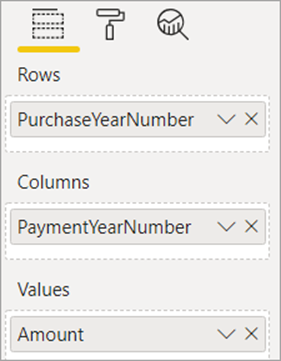
Here’s what the fields for this visual look like:

Although the extra table is a bit messy, it does mean that you don’t have to create any additional measures: you can just drag fields into the field well as usual.

Multiple Relationships for Multiple Dates

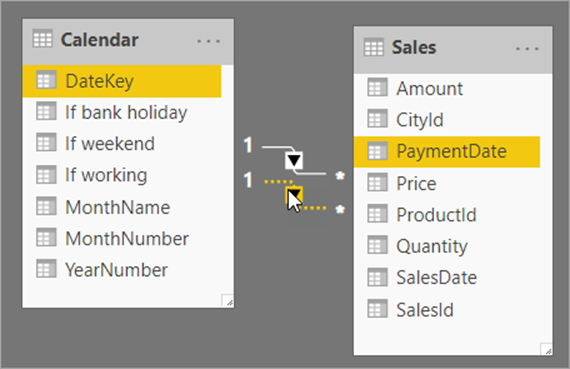
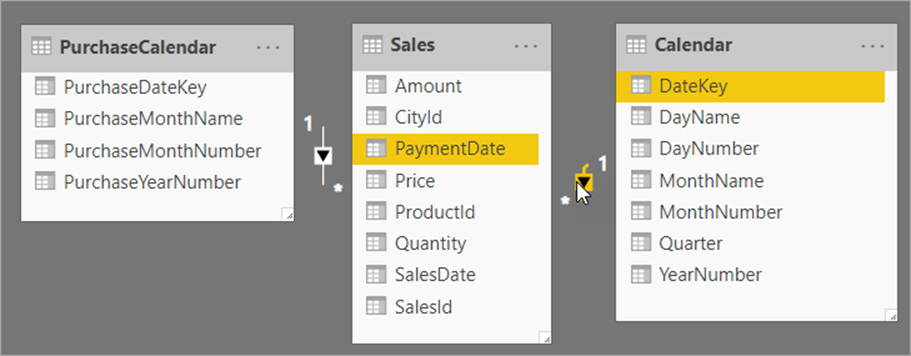
The alternative approach is to load one version of the calendar table, but create a second relationship:

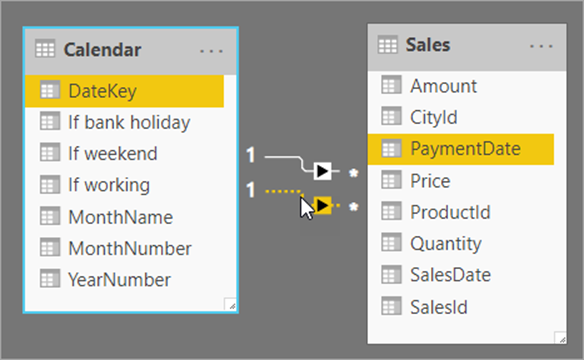
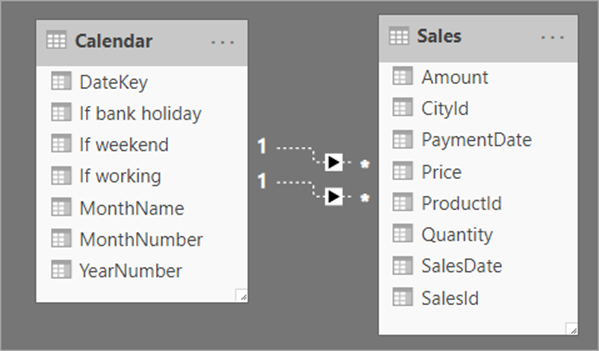
There are now two relationships:

  • The active relationship (the one with the solid line) is between the DateKey column in the Calendar table and the SalesDate column in the Sales table
  • The selected relationship above (the one with the dotted line) is between the DateKey column in the Calendar table and the PaymentDate column in the Sales table

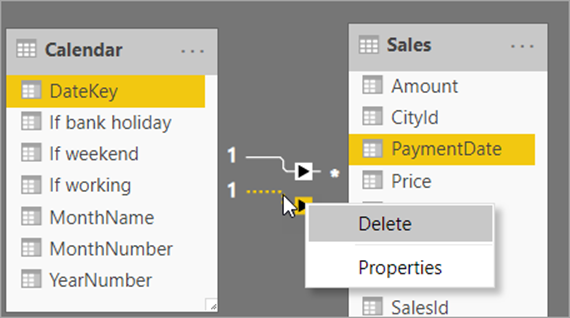
You can change which is the active relationship by right-clicking on it and choosing to show its properties:

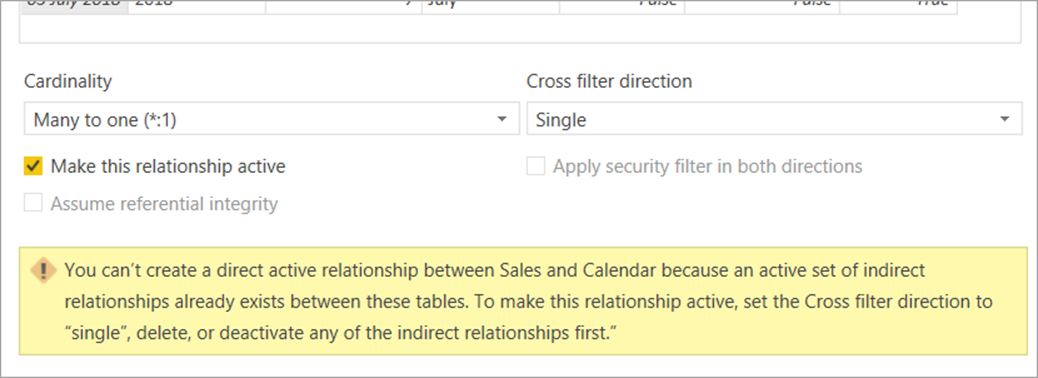
You can then tick the box to make a relationship the active one, but only after making all of the other relationships inactive first, as the following screenshot explains:

If you’re going to use multiple relationships, it may be a good idea to make all of them inactive. Then you won’t inadvertently create a measure referring to the wrong relationship by mistake:

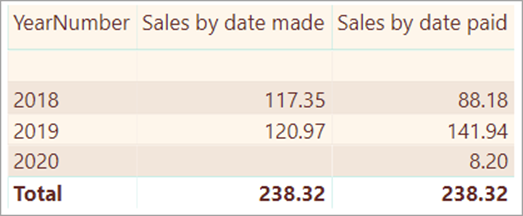
What you now have to do is to create measures saying for any calculation to which table it should refer. For example, suppose you want to show for each year:

  • The total sales made in that year; and
  • The total sales paid for in that year.

To do this, create two measures using the USERELATIONSHIP function in each case. Here’s the first one:

Sales by date made = CALCULATE(
    SUM(Sales[Amount]),
    USERELATIONSHIP(
        'Calendar'[DateKey],
        Sales[SalesDate]
    )
)

And here’s the second:

Sales by date paid = CALCULATE(
    SUM(Sales[Amount]),
    USERELATIONSHIP(
        'Calendar'[DateKey],
        Sales[PaymentDate]
    )
)

These measures will allow you to show the required figures:

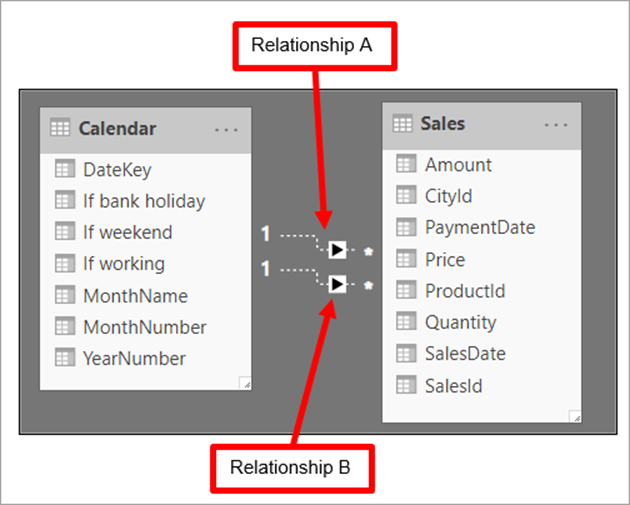
However, there’s no way that I can see to display an aged debtor matrix like the one created for the multiple table approach. It’s also a bit irritating that in the USERELATIONSHIP function that you have to specify the two columns that you’re joining together. It would be better if you could just specify which relationship you’re using. Something like this in fact:

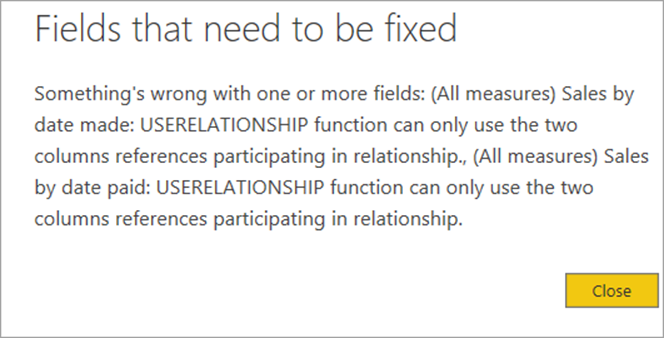
You might also expect that because you are referencing the start column and end column of the relationship, you don’t need the relationship to actually exist, but you’d be wrong, as this error message which appears if you delete the above relationships shows:

And with that mild bit of whingeing, that’s the end of this article!

Conclusion

In this article, you’ve learned how and why you might want to create a calendar table in Power BI, how to use it to report on figures at different levels of granularity, how to add additional aggregator columns to the table and two different ways to cope with the situation where you have more than one date column in the same table. In the next and final article of this series, I’ll show how to use the calendar(s) that you’ve created to show things like year-to-date figures, cross-period comparisons and moving averages.

The post Using Calendars and Dates in Power BI appeared first on Simple Talk.


from Simple Talk https://ift.tt/2ugvQ4s
via